diff --git a/docs/quickstart.mdx b/docs/quickstart.mdx
index d9ecbb86d4..49576f9ef2 100644
--- a/docs/quickstart.mdx
+++ b/docs/quickstart.mdx
@@ -7,17 +7,12 @@ sidebar_custom_props: {
sidebarIcon: LucideRocket
}
---
+
RAGFlow is an open-source RAG (Retrieval-Augmented Generation) engine based on deep document understanding. When integrated with LLMs, it is capable of providing truthful question-answering capabilities, backed by well-founded citations from various complex formatted data.
-This quick start guide describes a general process from:
+This guide takes you from deploying RAGFlow with Docker Compose to asking your first question about your documents. After deployment, follow the 10-minute tutorial to configure models, create a Dataset, upload a document, and start a Chat.
-- Starting up a local RAGFlow server,
-- Creating a dataset,
-- Establishing an AI chat based on your datasets.
-
-:::danger IMPORTANT
-This guide deploys RAGFlow using Docker images and the Docker Compose configuration provided in the repository. Docker images are available for Linux x86-64 and ARM64 starting with v1.0.0-rc3. Docker automatically selects the image matching your host architecture when you use the release tag.
-:::
+If RAGFlow is already running, go directly to the [10-Minute Tutorial](#10-minute-tutorial).
## Prerequisites
@@ -27,7 +22,11 @@ This guide deploys RAGFlow using Docker images and the Docker Compose configurat
If Docker is not installed, see [Install Docker Engine](https://docs.docker.com/engine/install/).
-## Start up the server
+## Start Up the Server {#start-up-the-server}
+
+:::note
+This guide deploys RAGFlow using Docker images and the Docker Compose configuration provided in the repository. Docker images are available for Linux x86-64 and ARM64 starting with v1.0.0-rc3. Docker automatically selects the image matching your host architecture when you use the release tag.
+:::
1. For the default Elasticsearch document engine, ensure `vm.max_map_count` is at least 262144 on the Docker host:
@@ -80,86 +79,105 @@ If Docker is not installed, see [Install Docker Engine](https://docs.docker.com/
A successful response has HTTP status 200. If you changed `SVR_WEB_HTTP_PORT` in `.env`, include that port in the URL. Wait for this check to pass before opening the web interface.
-5. Open `http://IP_OF_YOUR_MACHINE` in a browser and log in. If you changed `SVR_WEB_HTTP_PORT` in `.env`, include that port in the URL.
+5. Open `http://IP_OF_YOUR_MACHINE` in a browser and log in. If you changed `SVR_WEB_HTTP_PORT` in `.env`, include that port in the URL. For first-time access, register an account if registration is available, or use an account provided by your administrator.
The RAGFlow container runs the API server, ingestion workers, and data synchronization. Its startup script runs the database migrations before starting the services.
-## Configure LLMs
+## 10-Minute Tutorial
-RAGFlow is a RAG engine and needs to work with an LLM to offer grounded, hallucination-free question-answering capabilities. RAGFlow supports most mainstream LLMs.
+Create a Dataset, upload a document, and use Chat to ask questions about its content. By the end of this tutorial, you will have a Chat that answers questions with references to your document.
-:::note
-RAGFlow also supports deploying models locally using Ollama or vLLM, but this part is not covered in this quick start guide. See [Deploy Local Models](./guides/models/deploy_local_llm.mdx) for instructions.
-:::
+Configure models → Create a Dataset → Upload a document → Start chatting
-To add and configure an LLM:
+Before you begin, log in to RAGFlow and prepare:
+
+- Access to a Chat model and an Embedding model, including any credentials required by your model provider.
+- A small TXT, Markdown, or text-based PDF document containing information you want to ask about.
+
+Document parsing and response times depend on the file size, model, and available resources.
+
+### Configure Models {#configure-llms}
+
+The **Chat model** generates answers. The **Embedding model** makes document content searchable. If both models are already available in your account, skip to [Create Your First Dataset](#create-your-first-dataset). Otherwise, configure them as follows:
1. Open **User settings** from your avatar, then select **Model providers**.
-2. In **Available models**, select a provider and create a provider instance.
-3. Enter the instance name and required connection information, such as **API Key** and **Base URL**. Select or add the models you need, verify them, and save the instance.
-4. Under **Set default models**, select a Chat model and an Embedding model. Configure other model types as needed.
+2. Under **Available models**, select your provider and create a provider instance.
+3. Enter the required connection details, such as **API Key** and **Base URL**.
+4. Add or select the Chat and Embedding models you will use, verify them, and save the instance.
+5. Under **Set default models**, select your Chat model and Embedding model.
-See [Configure Model Providers](./guides/models/llm_api_key_setup.md) for provider-specific fields and screenshots.
+If your Chat and Embedding models use different providers, configure an instance for each provider.
-## Create your first dataset
+For provider-specific instructions, see [Configure Model Providers](./guides/models/llm_api_key_setup.md). For locally hosted models, see [Deploy Local Models](./guides/models/deploy_local_llm.mdx).
-You can upload files to a dataset in RAGFlow and parse them into chunks. A dataset is a collection of documents. Question answering in RAGFlow can be based on one or more datasets. Supported file formats include documents (PDF, DOC, DOCX, TXT, MD, MDX), tables (CSV, XLSX, XLS), images (JPEG, JPG, PNG, TIF, GIF), and slides (PPT, PPTX).
+### Create Your First Dataset {#create-your-first-dataset}
-To create your first dataset:
+A Dataset holds the documents your Chat will search when answering questions.
-1. Select **Datasets** in the navigation bar, then click **Create dataset**.
-2. Enter **Name**, select **Embedding model**, then choose a built-in template or a saved ingestion pipeline from **Parse mode**. For a first dataset, use **General**.
-3. Click **Save**, open the dataset, and review its **Configuration** before uploading files.
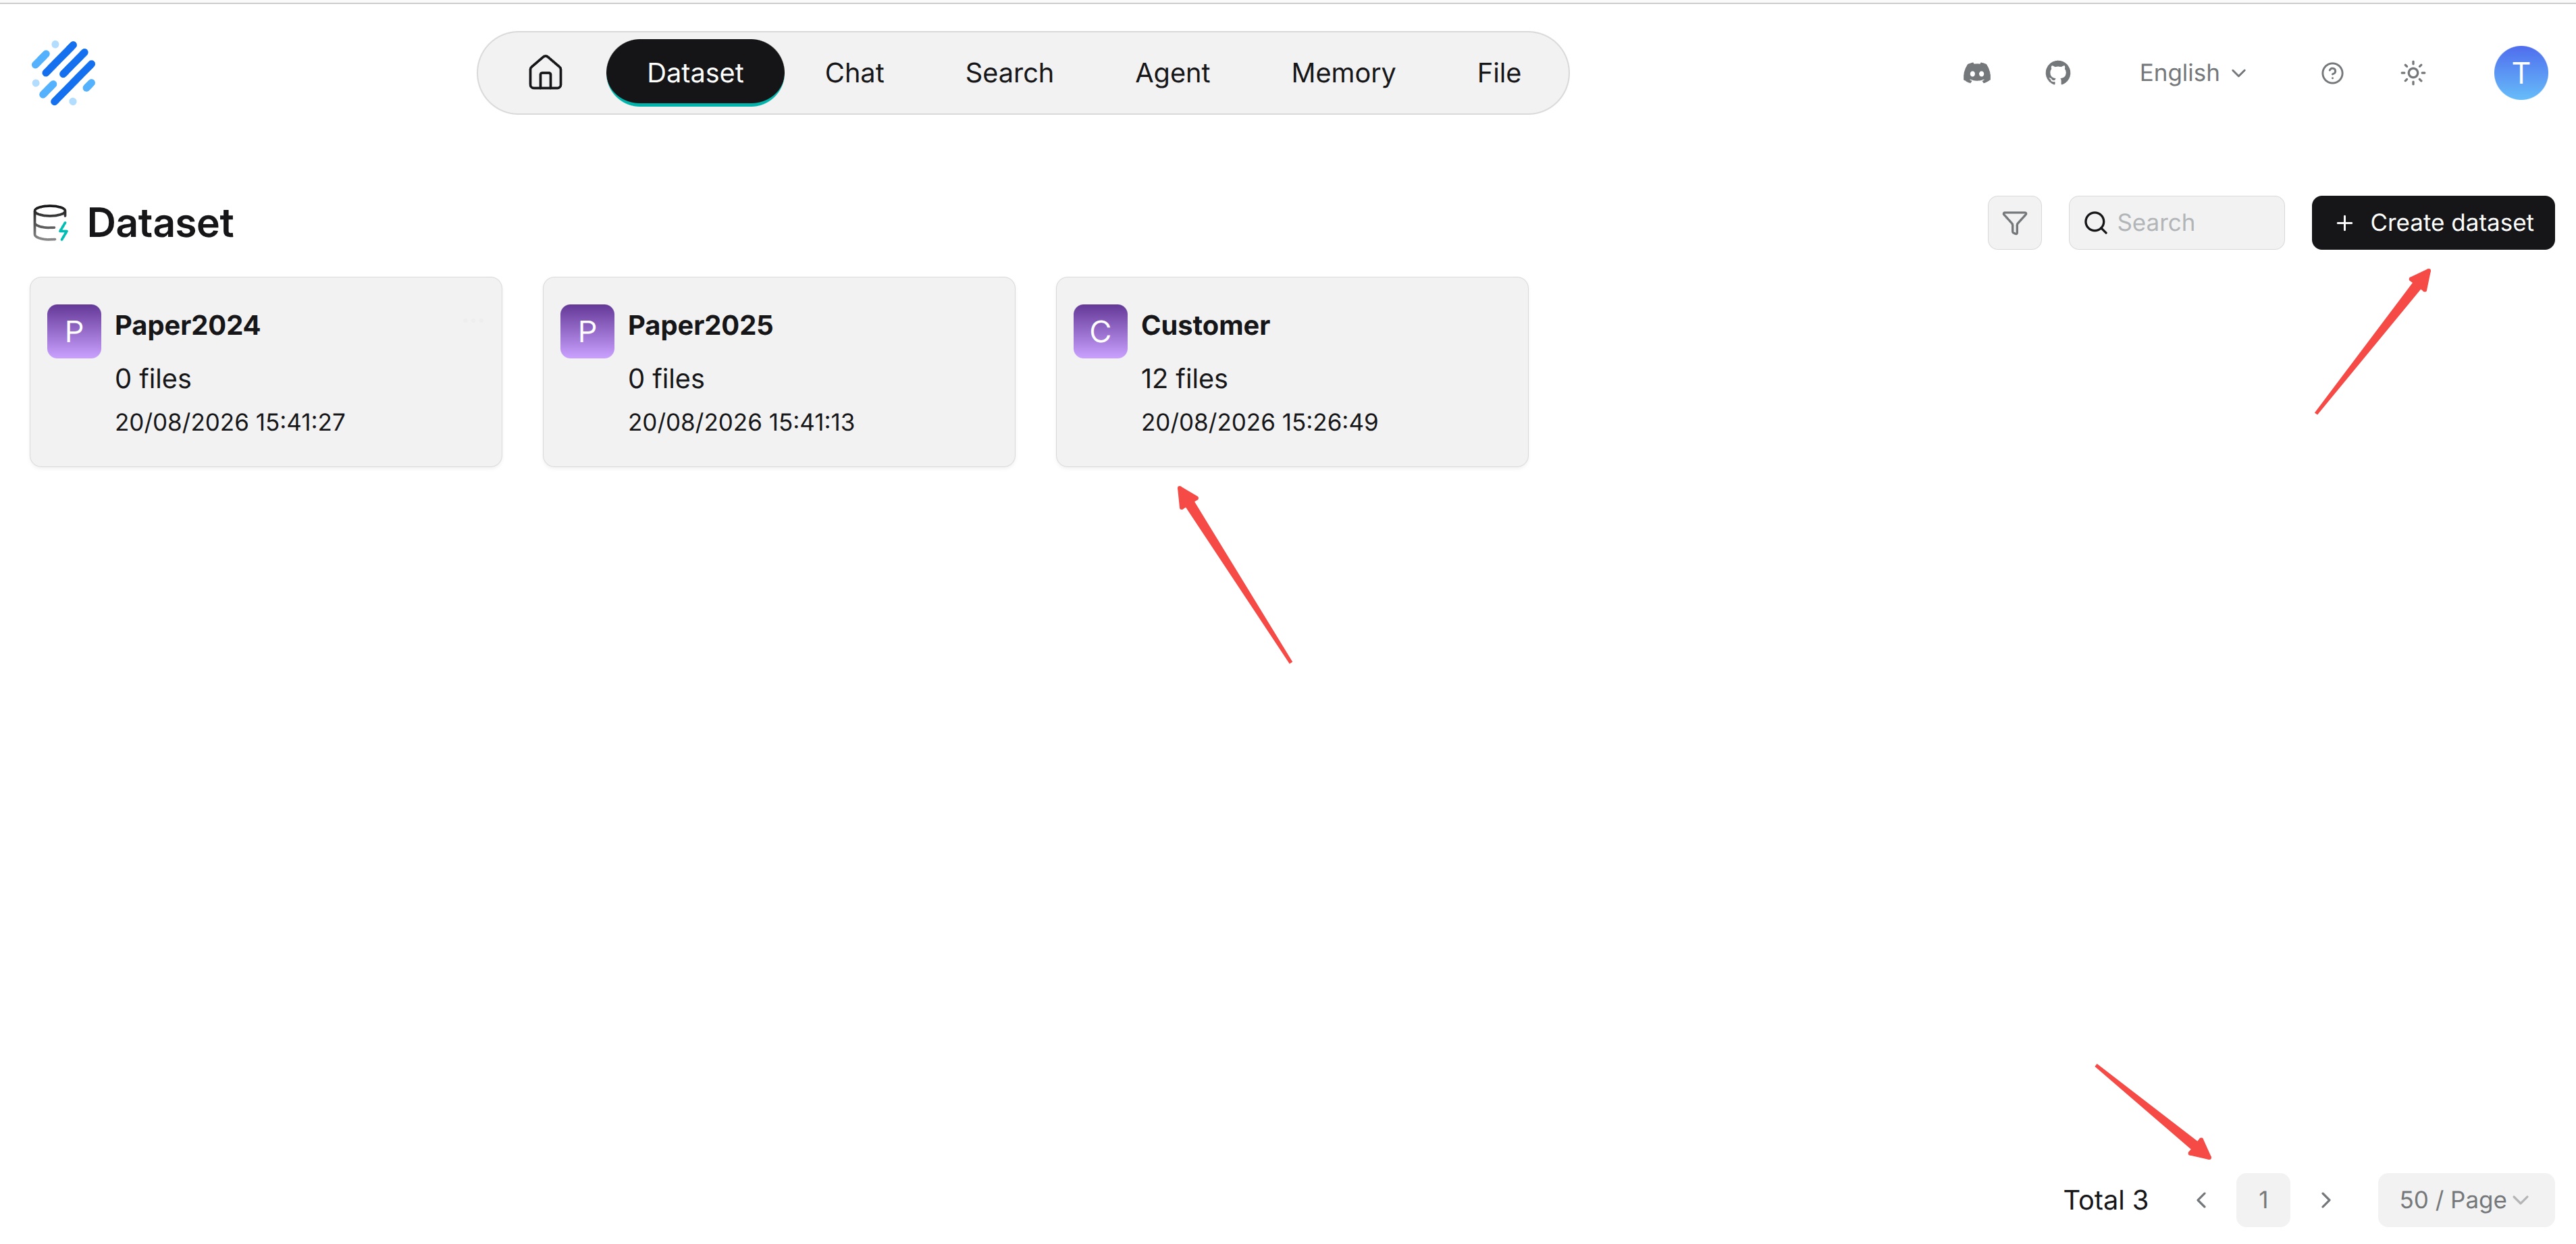
+1. Select **Dataset** in the navigation bar, then click **Create dataset**.
- See [Dataset List and Creation](./guides/dataset/dataset_list_and_creation.md) and [Dataset Configuration](./guides/dataset/configuration.md) for details.
+  - :::caution IMPORTANT
- Choose the embedding model before parsing files. Before the dataset contains chunks, you can change the model directly. Once chunks exist, selecting a different model on the configuration page triggers a compatibility check against sampled existing vectors. The vector dimensions must match, and the average cosine similarity must be at least 0.9. If the check fails, the previous selection is restored. Saving a model change does not automatically re-embed existing chunks.
- :::
+2. Enter a **Name**, such as `My first Dataset`.
+3. Select the **Embedding model** configured above.
+4. In **Parsing mode**, select **General** and click **Save**.
-4. Open the dataset's **Files** page. Click **Add file > Upload file**, select local files, and confirm the upload. Enable **Parse on creation** to start parsing automatically.
-5. If parsing was not started during upload, select the uploaded documents and click **Run**. Wait for parsing to complete before using them in Chat.
+Your new Dataset opens. Keep the default configuration for this tutorial and use the **Files** page to add your document.
- See [Files: Dataset Document Management](./guides/dataset/files_dataset_document_management.md) for upload and parsing options. If parsing stalls, check the document's **Logs** and the `ragflow-cpu` service logs for ingestion errors.
+Choose your Embedding model before parsing documents. For other parsing methods and model changes, see [Dataset Configuration](./guides/dataset/configuration.md).
-## Intervene with file parsing
+### Upload and Parse a Document
-RAGFlow features visibility and explainability, allowing you to view the chunking results and intervene where necessary. To do so:
+Parsing converts your document into smaller sections, called chunks, that RAGFlow can retrieve when answering a question.
-1. Click on the file that completes file parsing to view the chunking results:
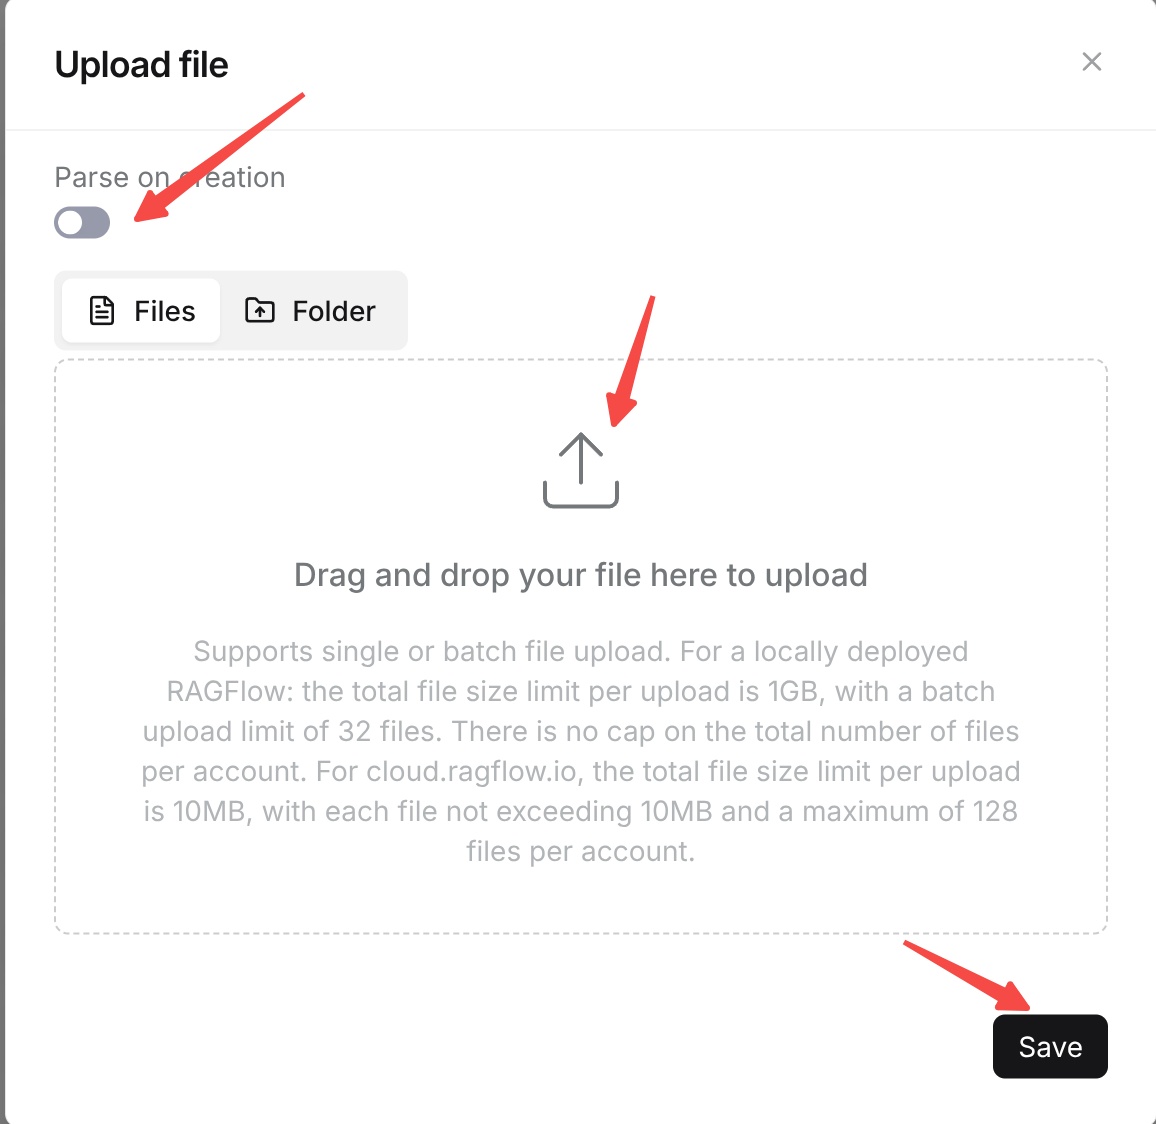
+1. On the Dataset's **Files** page, click **Add file > Upload file**.
+2. Select your document, enable **Parse on creation**, and click **Save**.
- _You are taken to the **Chunk** page:_
+
 - 
+3. Wait for parsing to complete. If you uploaded without enabling **Parse on creation**, select the document and click **Run** to start parsing.
+4. Check that parsing completed successfully and the document has chunks before continuing.
-2. Hover over each snapshot for a quick view of each chunk.
+If parsing fails, open the document's **Logs** to view the error. See [Dataset Document Management](./guides/dataset/files_dataset_document_management.md) for parsing and troubleshooting instructions.
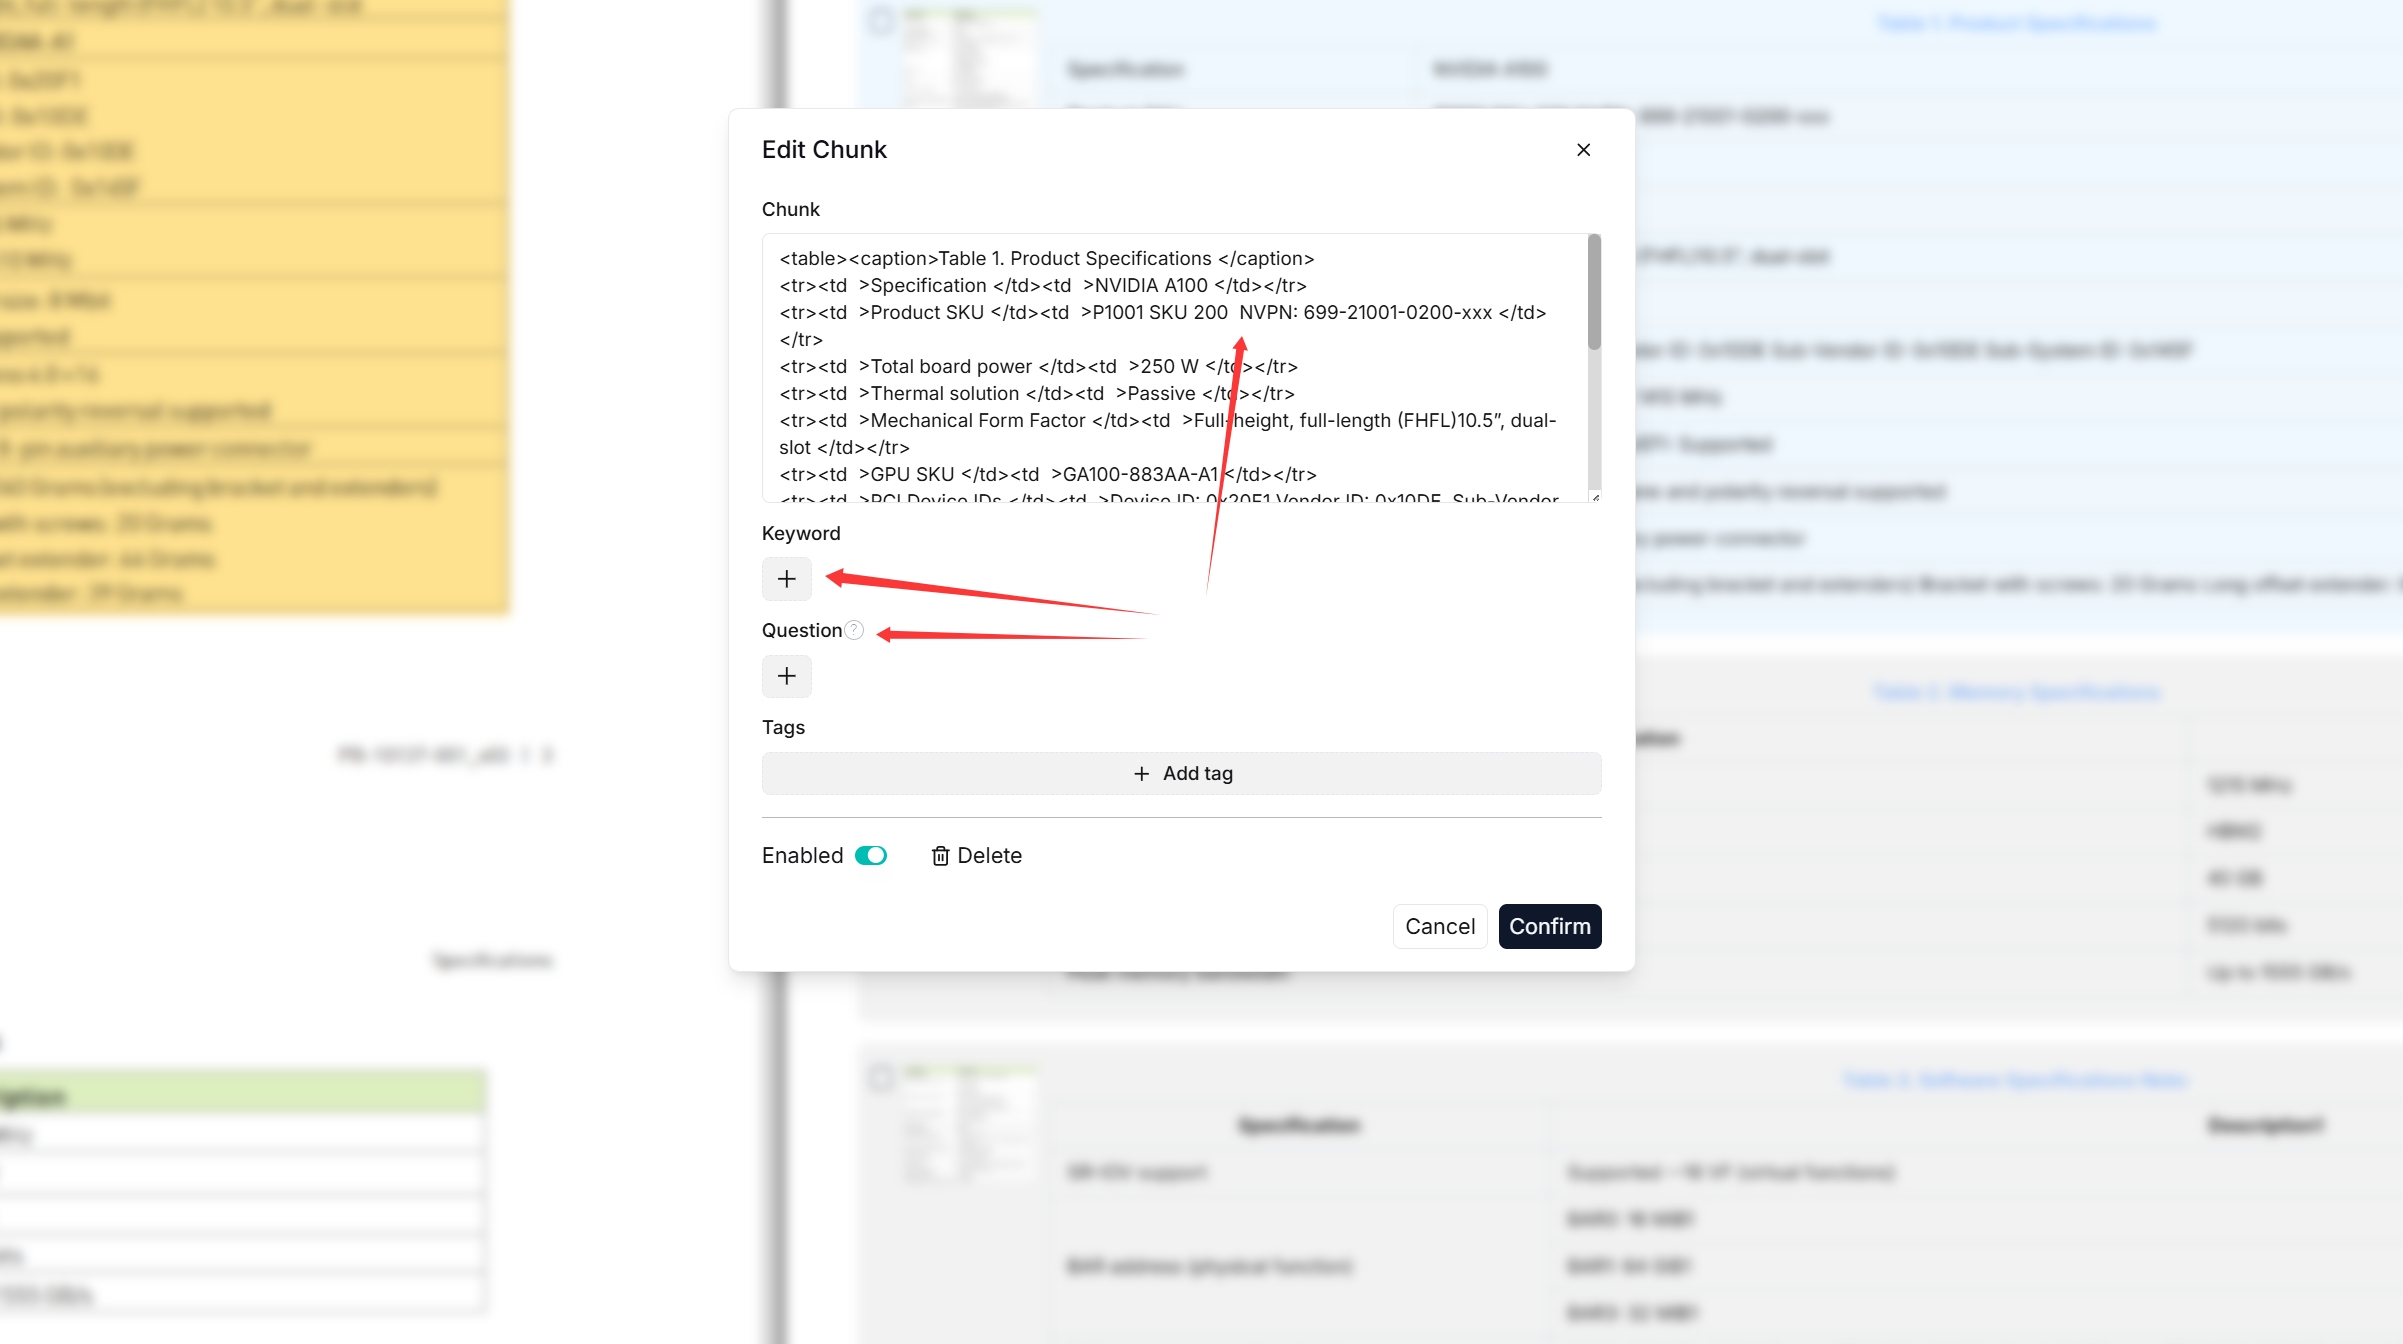
-3. Double click the chunked texts to add keywords or make *manual* changes where necessary:
+### Create a Chat and Ask a Question {#set-up-an-ai-chat}
- 
+1. Select **Chat** in the navigation bar and click **Create chat**.
+2. Enter a name, such as `My first Chat`, and confirm creation.
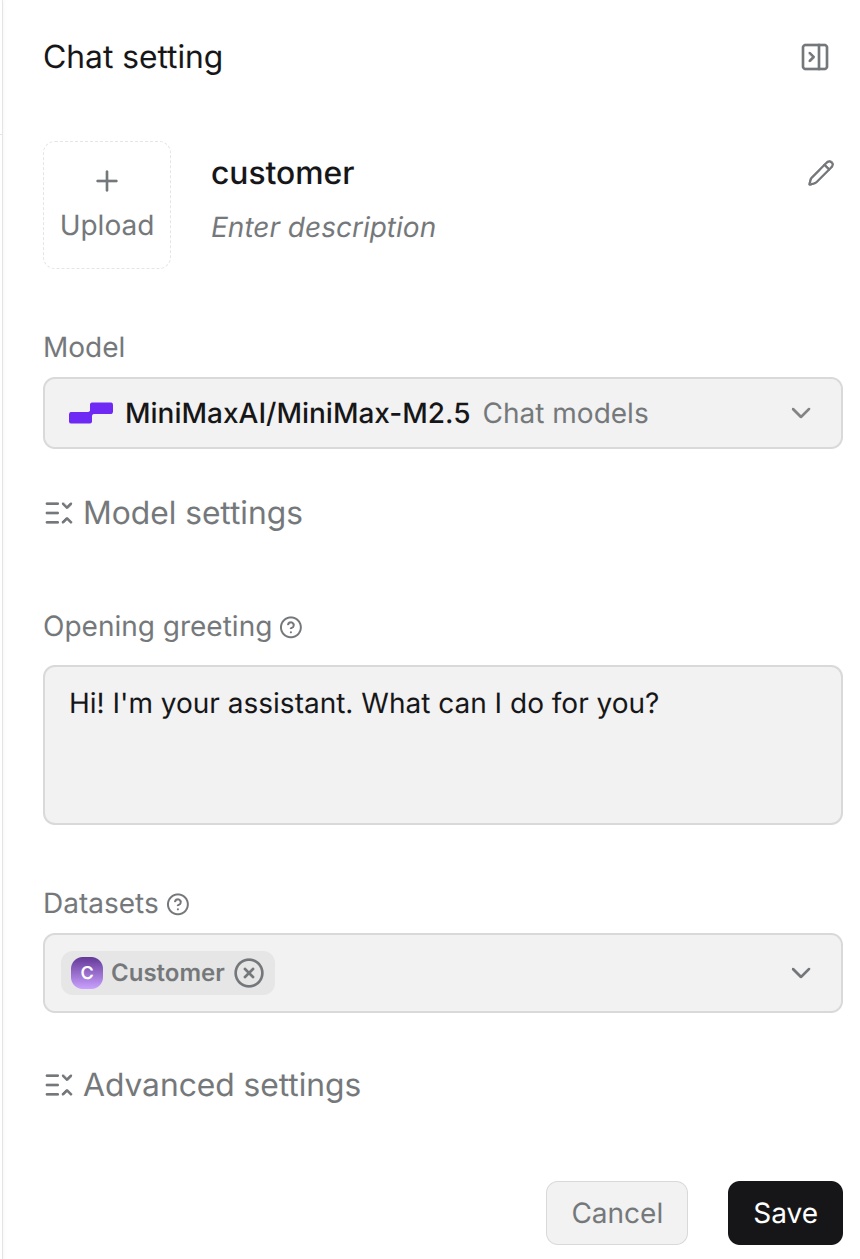
+3. Click the gear icon to open **Chat setting**. In **Model**, select your Chat model. In **Datasets**, select the Dataset you just prepared.
- :::caution NOTE
- You can add keywords or questions to a file chunk to improve its ranking for queries containing those keywords. This action increases its keyword weight and can improve its position in search list.
- :::
+
 -4. In Retrieval testing, ask a quick question in **Test text** to double check if your configurations work:
+4. Expand **Advanced settings** and enable **Show citations**. Keep the other settings at their defaults and click **Save**.
+5. In the chat window, select **Naive** beside the message box and ask a question whose answer is in your document.
+6. Read the answer and open its citations to check the supporting document content.
+Check that the answer contains information from your document and that opening a citation shows the supporting source content. You can then continue asking questions about the same document.
-## Set up an AI chat
+For additional settings, see [Chat Configuration](./guides/chat/chat_configuration.md).
-Conversations in RAGFlow are based on a particular dataset or multiple datasets. Once you have created your dataset and finished file parsing, you can go ahead and start an AI conversation.
+### Optional: Check Retrieval Results {#intervene-with-file-parsing}
-1. Select **Chat** in the navigation bar, then click **Create chat**.
-2. Enter a name and confirm creation.
-3. Open **Chat setting**, select the dataset you parsed, and choose a chat model. You can configure model defaults under **User settings > Model providers > Set default models**.
-4. Review the **System prompt** and retrieval settings. Set **Empty response** to the message you want returned when no answer can be found, or leave it blank to allow the model to generate a response without matching dataset content.
-5. Save the settings, open the chat window, and ask a question about your documents. Select **Naive** for straightforward questions or **Agentic** for questions requiring deeper investigation.
+Use this optional check to inspect the document content or investigate answers that do not match your expectations.
-See [Feature Overview and Creation](./guides/chat/feature_overview_and_creation.md) for Chat creation screenshots and [Chat Configuration](./guides/chat/chat_configuration.md) for the available settings.
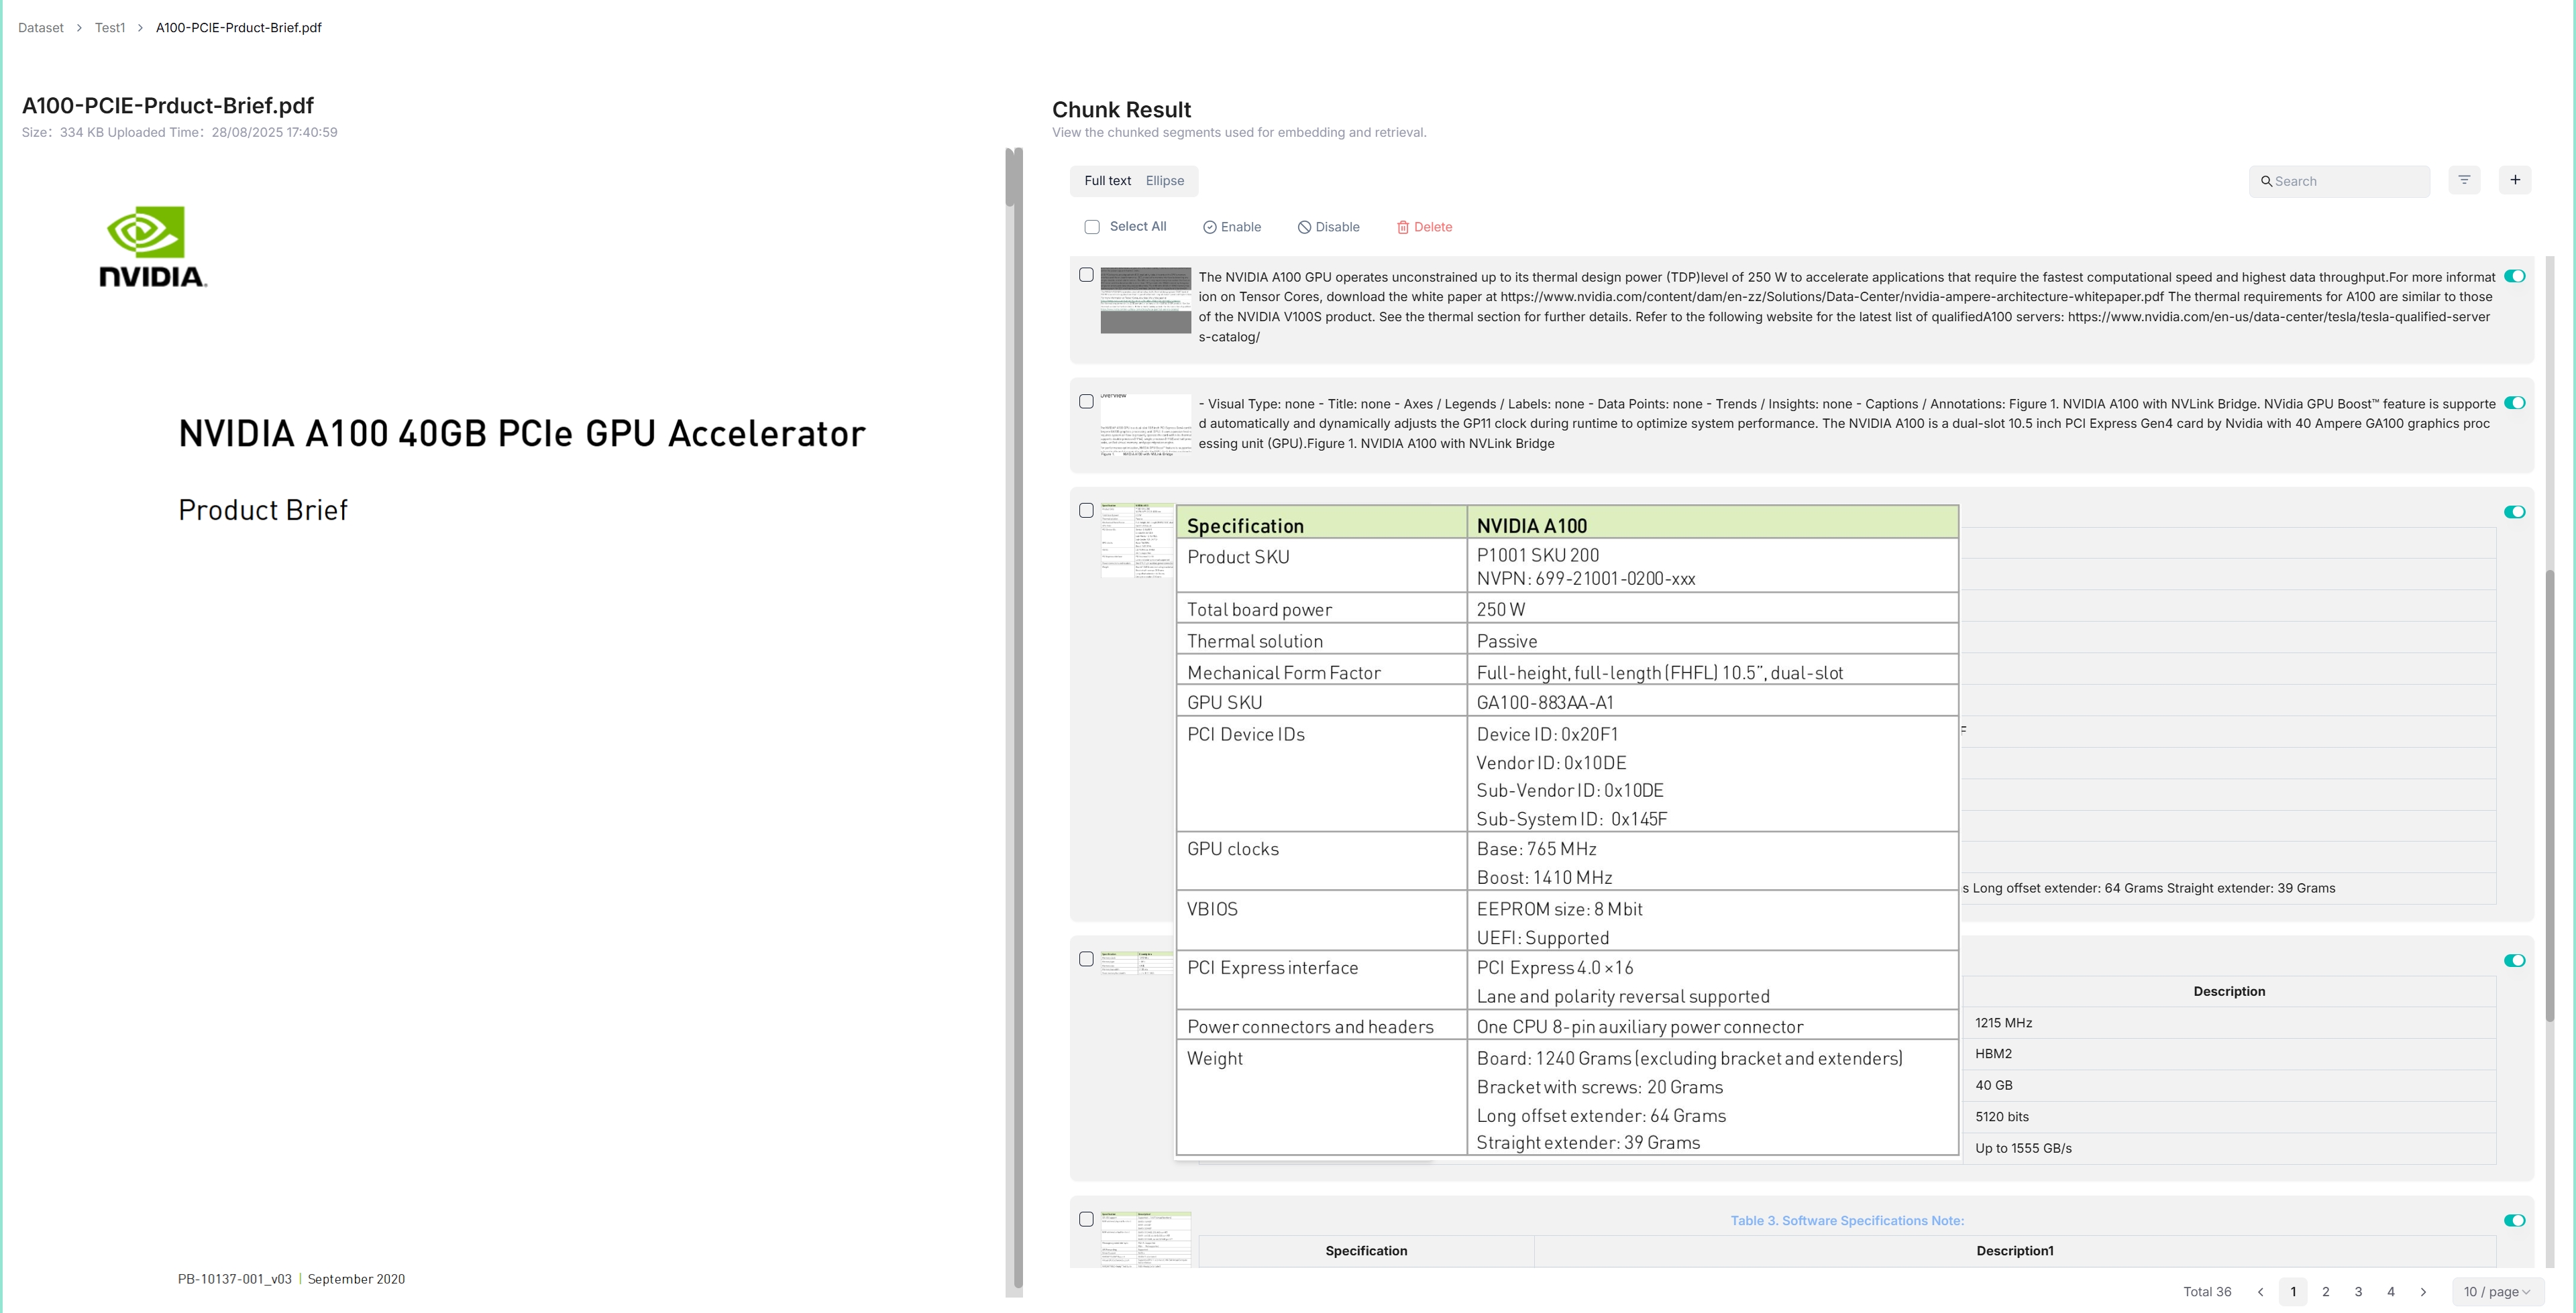
+1. Click the parsed document's name to view its chunks. Check that the text you expect is present and readable.
-:::tip NOTE
-RAGFlow also offers an HTTP API for integrating its capabilities into your applications:
+
 -- [Acquire a RAGFlow API key](./develop/acquire_ragflow_api_key.md)
-- [HTTP API reference](./references/http_api_reference.md)
-:::
+2. Return to the Dataset and open **Retrieval testing**.
+3. Enter a question whose answer is in the document in **Test text**, then run the test.
+4. Check that the results contain content that answers your question.
+
+### If You Need Help
+
+- **A model is not available for selection**: Check that it has been added and verified under **User settings > Model providers**. See [Configure Model Providers](./guides/models/llm_api_key_setup.md#verify-models).
+- **Document parsing fails**: Open the document's **Logs** to view the error, then follow [View Parsing Status](./guides/dataset/files_dataset_document_management.md#view-parsing-status).
+- **The answer has no citations**: Check that **Show citations** is enabled and that your Dataset contains parsed, enabled documents. Use [Retrieval testing](#intervene-with-file-parsing) to check whether your question finds supporting content.
+
+### Next Steps
+
+- **Sync external content**: [Connect a data source](./guides/data_source/overview_and_page_management.md) to keep your Dataset updated with less manual uploading.
+- **Collaborate with your team**: [Invite team members](./guides/team/index.md) to manage and use shared Datasets together.
+- **Make your Chat available on your website**: [Embed your Chat](./guides/chat/using_chat_sessions.md#embed-into-a-website) so visitors can ask questions about your content.
+
+For more features and detailed instructions, see the [User Guides](./category/user-guides).