mirror of
https://github.com/infiniflow/ragflow.git
synced 2026-11-10 21:32:43 +08:00
docs: Aligning field names, configuration paths, and operating steps, and documenting pending image updates (#21759)
This commit is contained in:
 YanZhang authored and
 GitHub committed
1 parent
293936c4f5
commit
cc0600c85e
50 files changed
+743
-568
No files matched your search
@@ -8,14 +8,12 @@ title: Check System Status
|
||||
|
||||
## Check Whether Services Are Running Normally
|
||||
|
||||
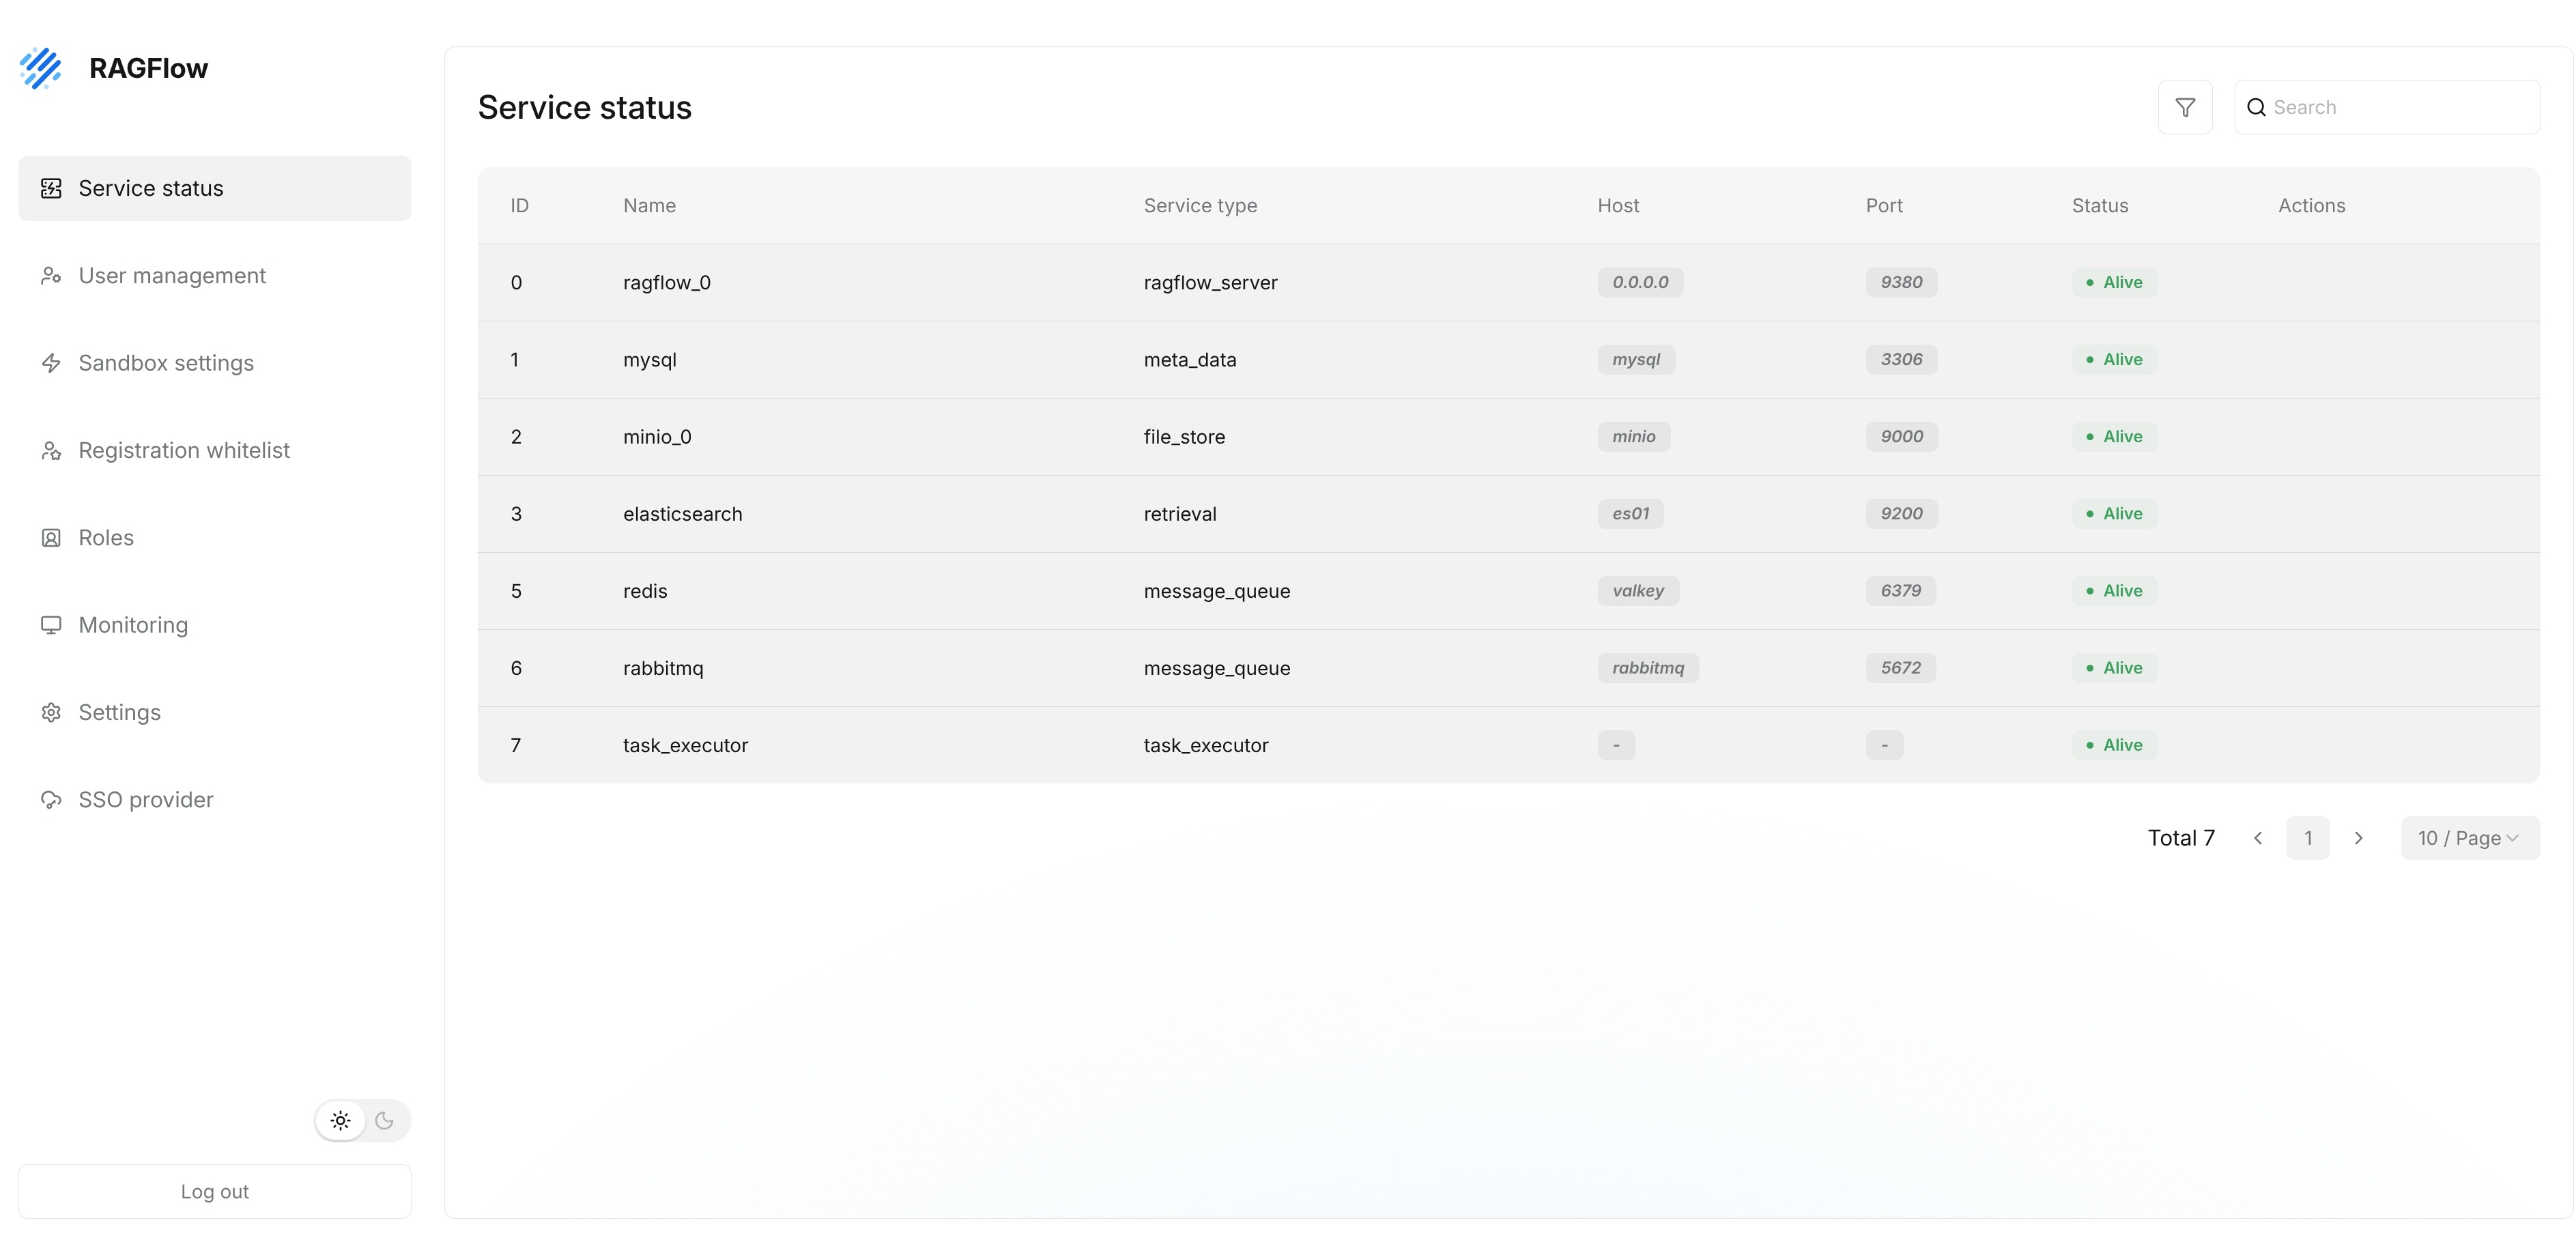
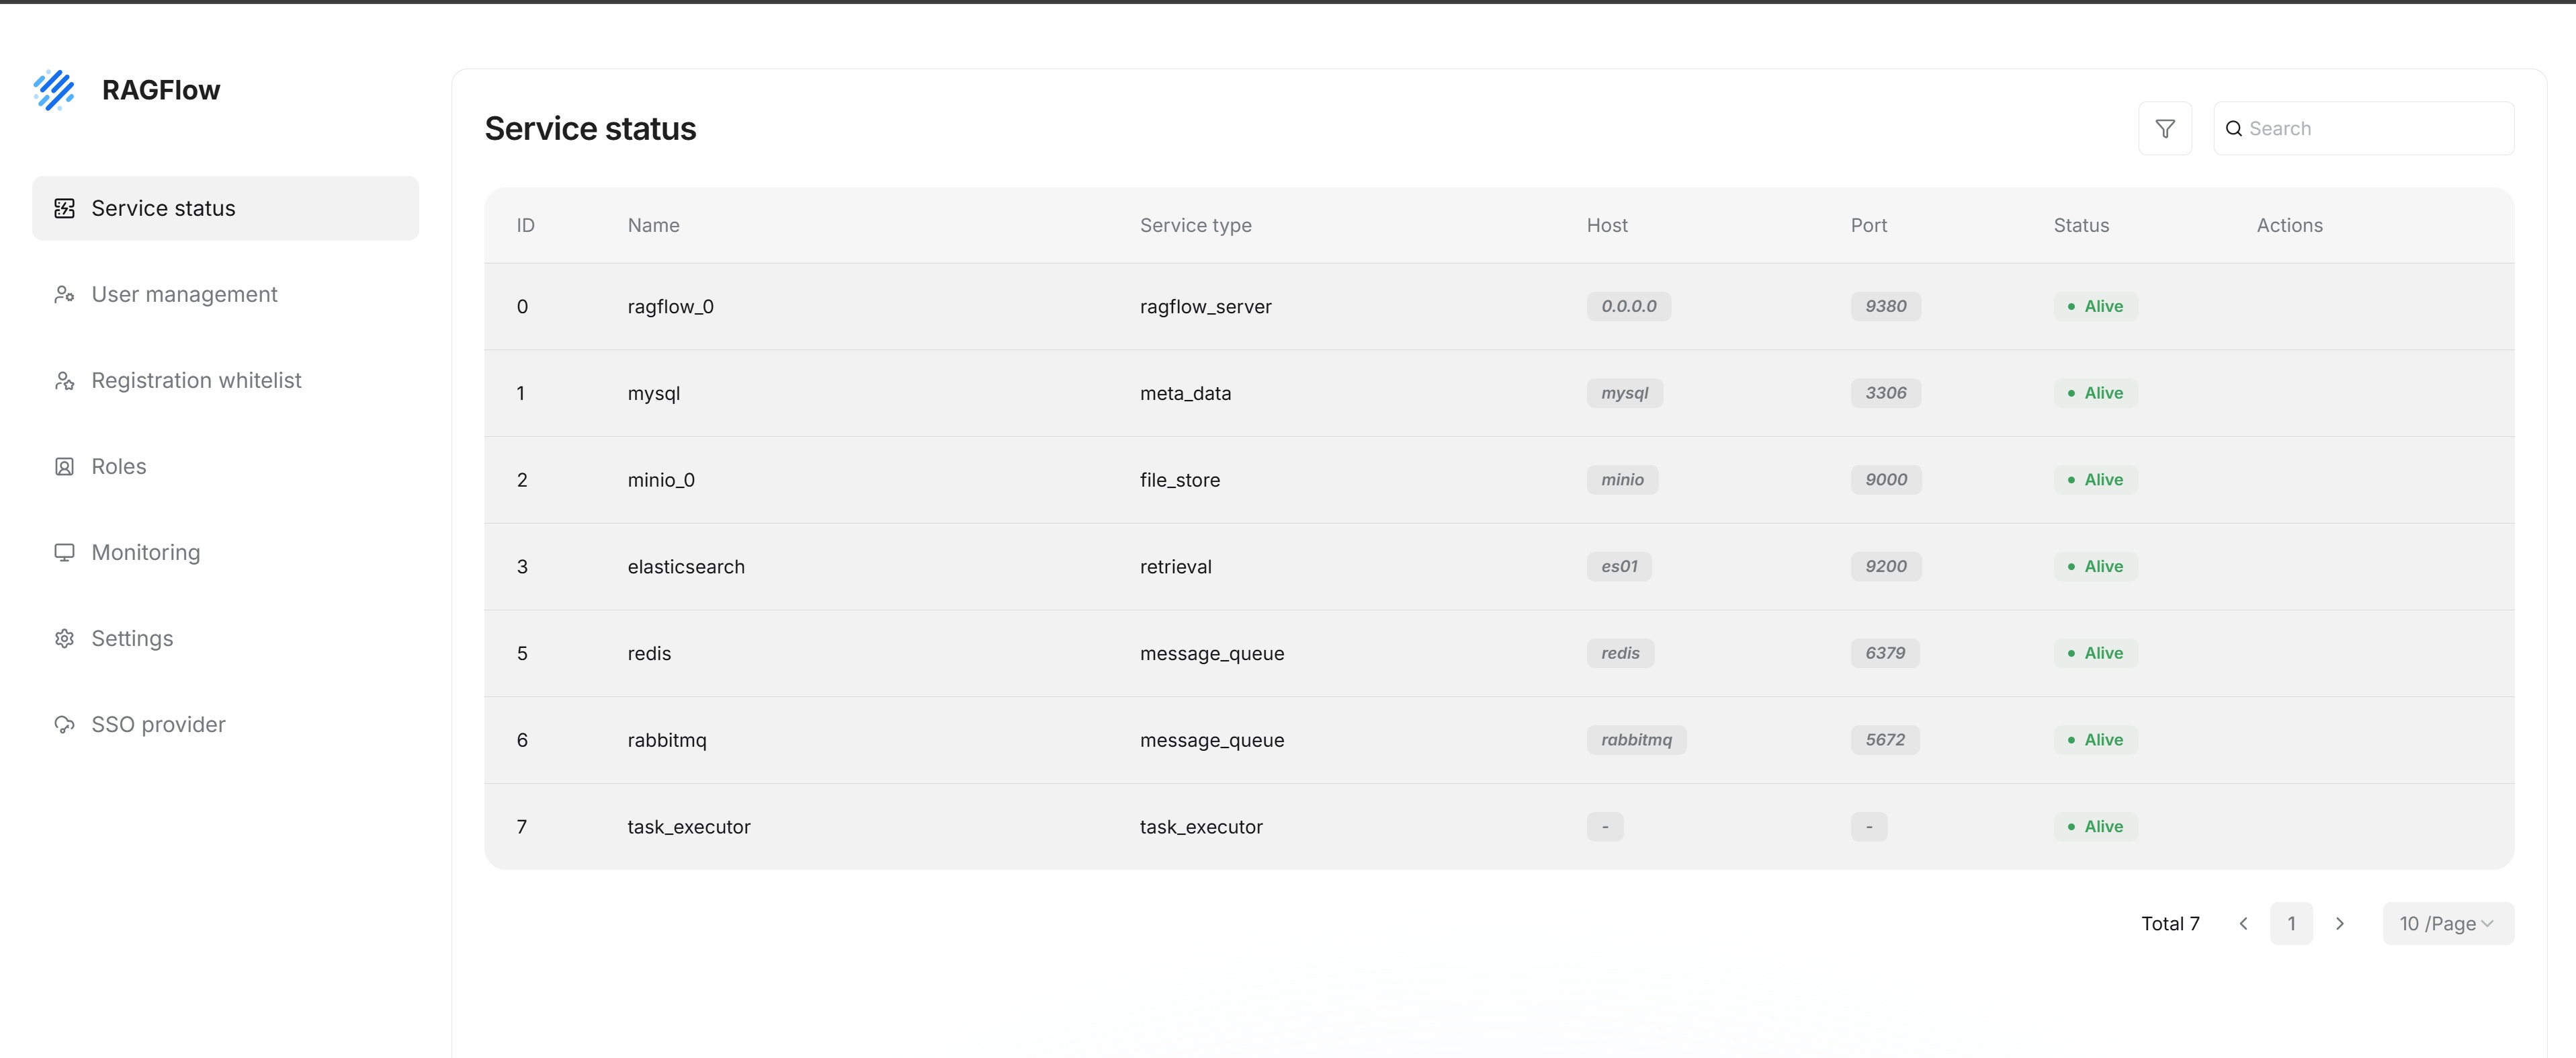
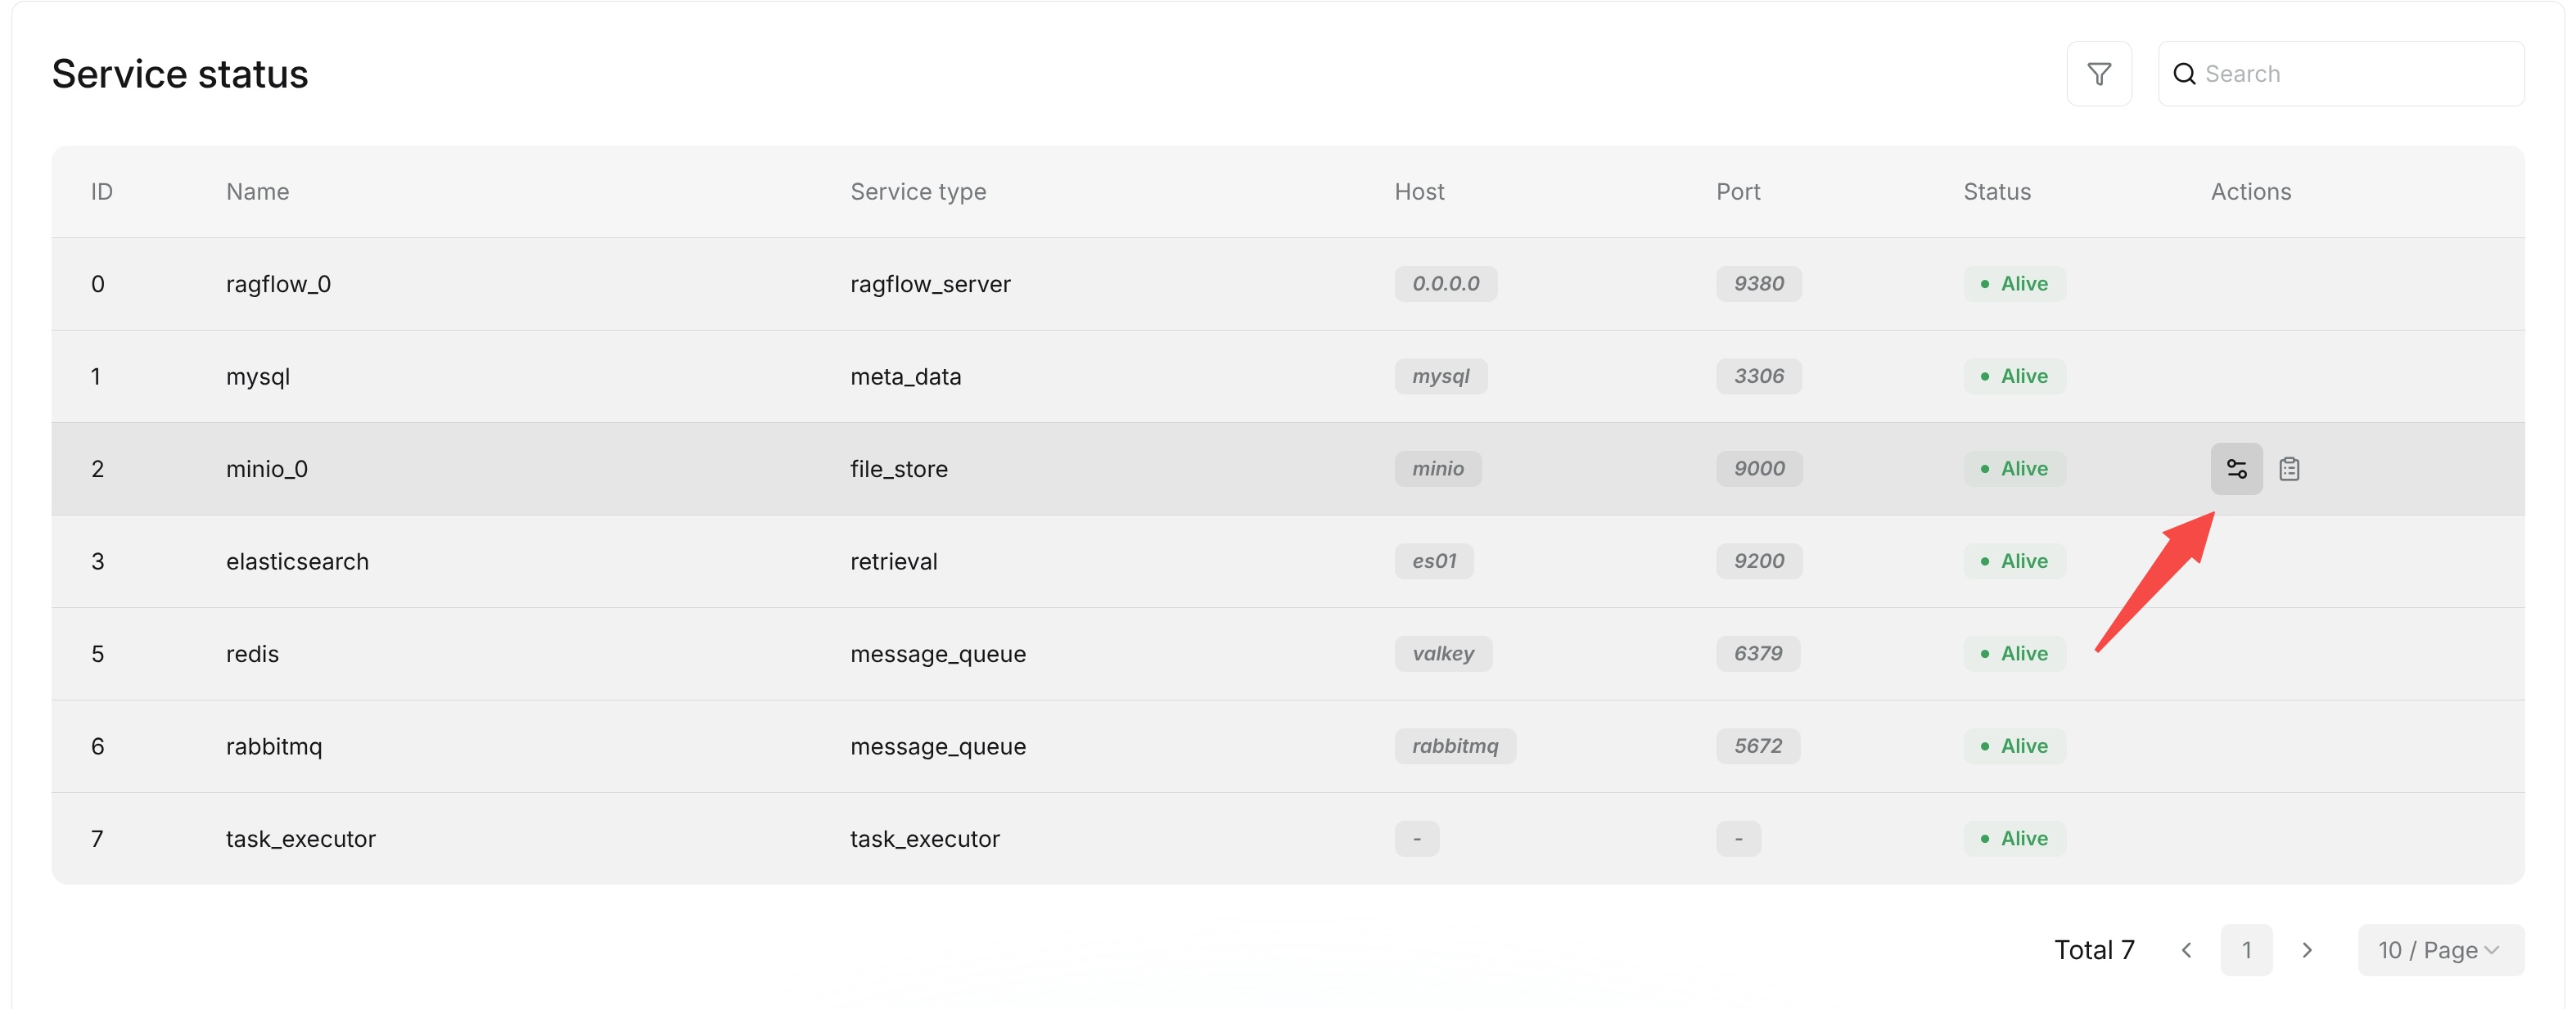
After entering the Admin UI, open the **Service status** page to view the status reported by the Go services and their configured dependencies. Each row displays the service `Name`, `Service type`, `Host`, `Port`, and `Status`. Use **Actions** to view the `elapsed` diagnostic value and any status message.
|
||||
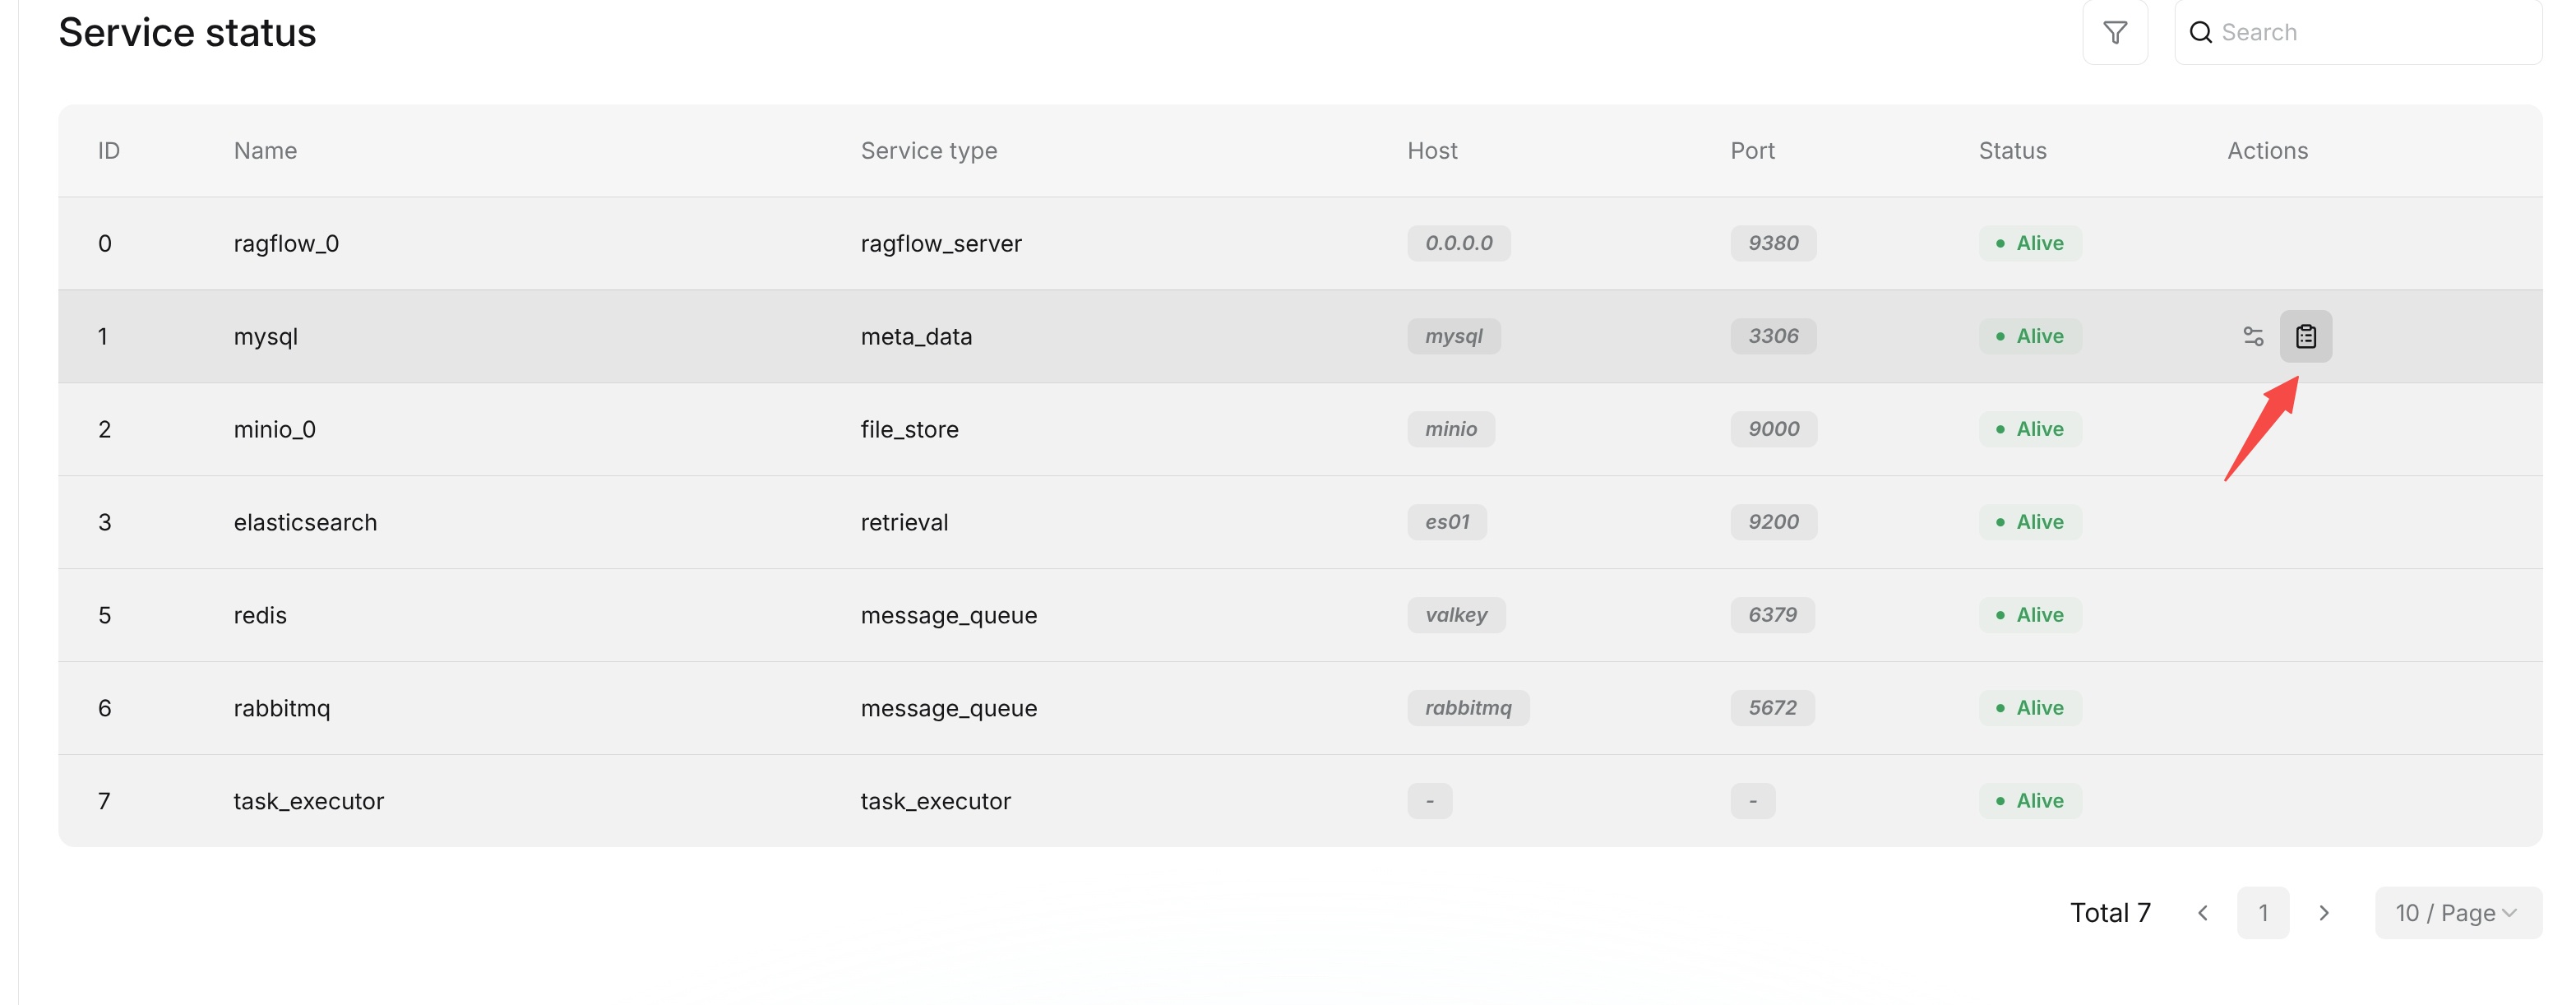
The Admin UI sidebar contains **Services**, **Users**, and **Sandbox**. Open **Services** to view the status reported by the Go services and their configured dependencies. Each row displays the service `Name`, `Service type`, `Host`, `Port`, and `Status`. The table does not display an ID column. Hover over a row to show its **Actions**: use the sliders icon for **Extra information**, or the clipboard icon to open service details.
|
||||
|
||||
|
||||
|
||||
For dependencies, `alive` means that the corresponding health check succeeded. `timeout`, `not available`, or another status indicates that the check failed or that the configured implementation is unavailable. For Go server processes, `alive` means that Admin received a heartbeat during the preceding 45 seconds; otherwise the status is `timeout`.
|
||||
|
||||
|
||||
|
||||
The open-source Go deployment reports the following entries:
|
||||
|
||||
| Service type | Entry | How the status is determined |
|
||||
@@ -25,23 +23,28 @@ The open-source Go deployment reports the following entries:
|
||||
| `storage_engine` | The configured object storage, such as MinIO | The server calls the active storage implementation's health check. |
|
||||
| `cache` | Kvrocks | The server checks the configured Kvrocks connection. |
|
||||
| `message_queue` | NATS | The server reads the status of the active message queue implementation. |
|
||||
| `api_server` | Each reporting API process | Admin evaluates the process heartbeat. |
|
||||
| `api` | Each reporting API process | Admin evaluates the process heartbeat. |
|
||||
| `ingestor` | Each reporting Ingestor process | Admin evaluates the process heartbeat. |
|
||||
| `file_syncer` | Each reporting Syncer process | Admin evaluates the process heartbeat. |
|
||||
| `syncer` | Each reporting Syncer process | Admin evaluates the process heartbeat. |
|
||||
|
||||
Only processes that have reported a heartbeat to Admin appear in the process portion of the list. For dependency rows, `elapsed` records timing information from the corresponding status check; for API, Ingestor, and Syncer rows, it records the time since the latest heartbeat. The host is shown as `-` and the port as `0` when the configured document engine or storage implementation does not provide an endpoint for the status row.
|
||||
|
||||
## View Service Details
|
||||
|
||||
On the **Service status** page, administrators can view the service `Name`, `Service type`, `Host`, `Port`, and `Status`.
|
||||
On the **Services** page, administrators can view the service `Name`, `Service type`, `Host`, `Port`, and `Status`.
|
||||
|
||||
Opening a service from **Actions** displays the status record returned by the Go Admin service. Depending on the entry, it can include the service name, type, host, port, status, elapsed health-check time, and an error or status message. Use the database or container administration tools provided by your deployment environment when you need database process lists or container operations.
|
||||
1. Find the service on **Services**. Use the search box to filter by service name or type if needed.
|
||||
2. Hover over the service row and click the clipboard icon in **Actions**.
|
||||
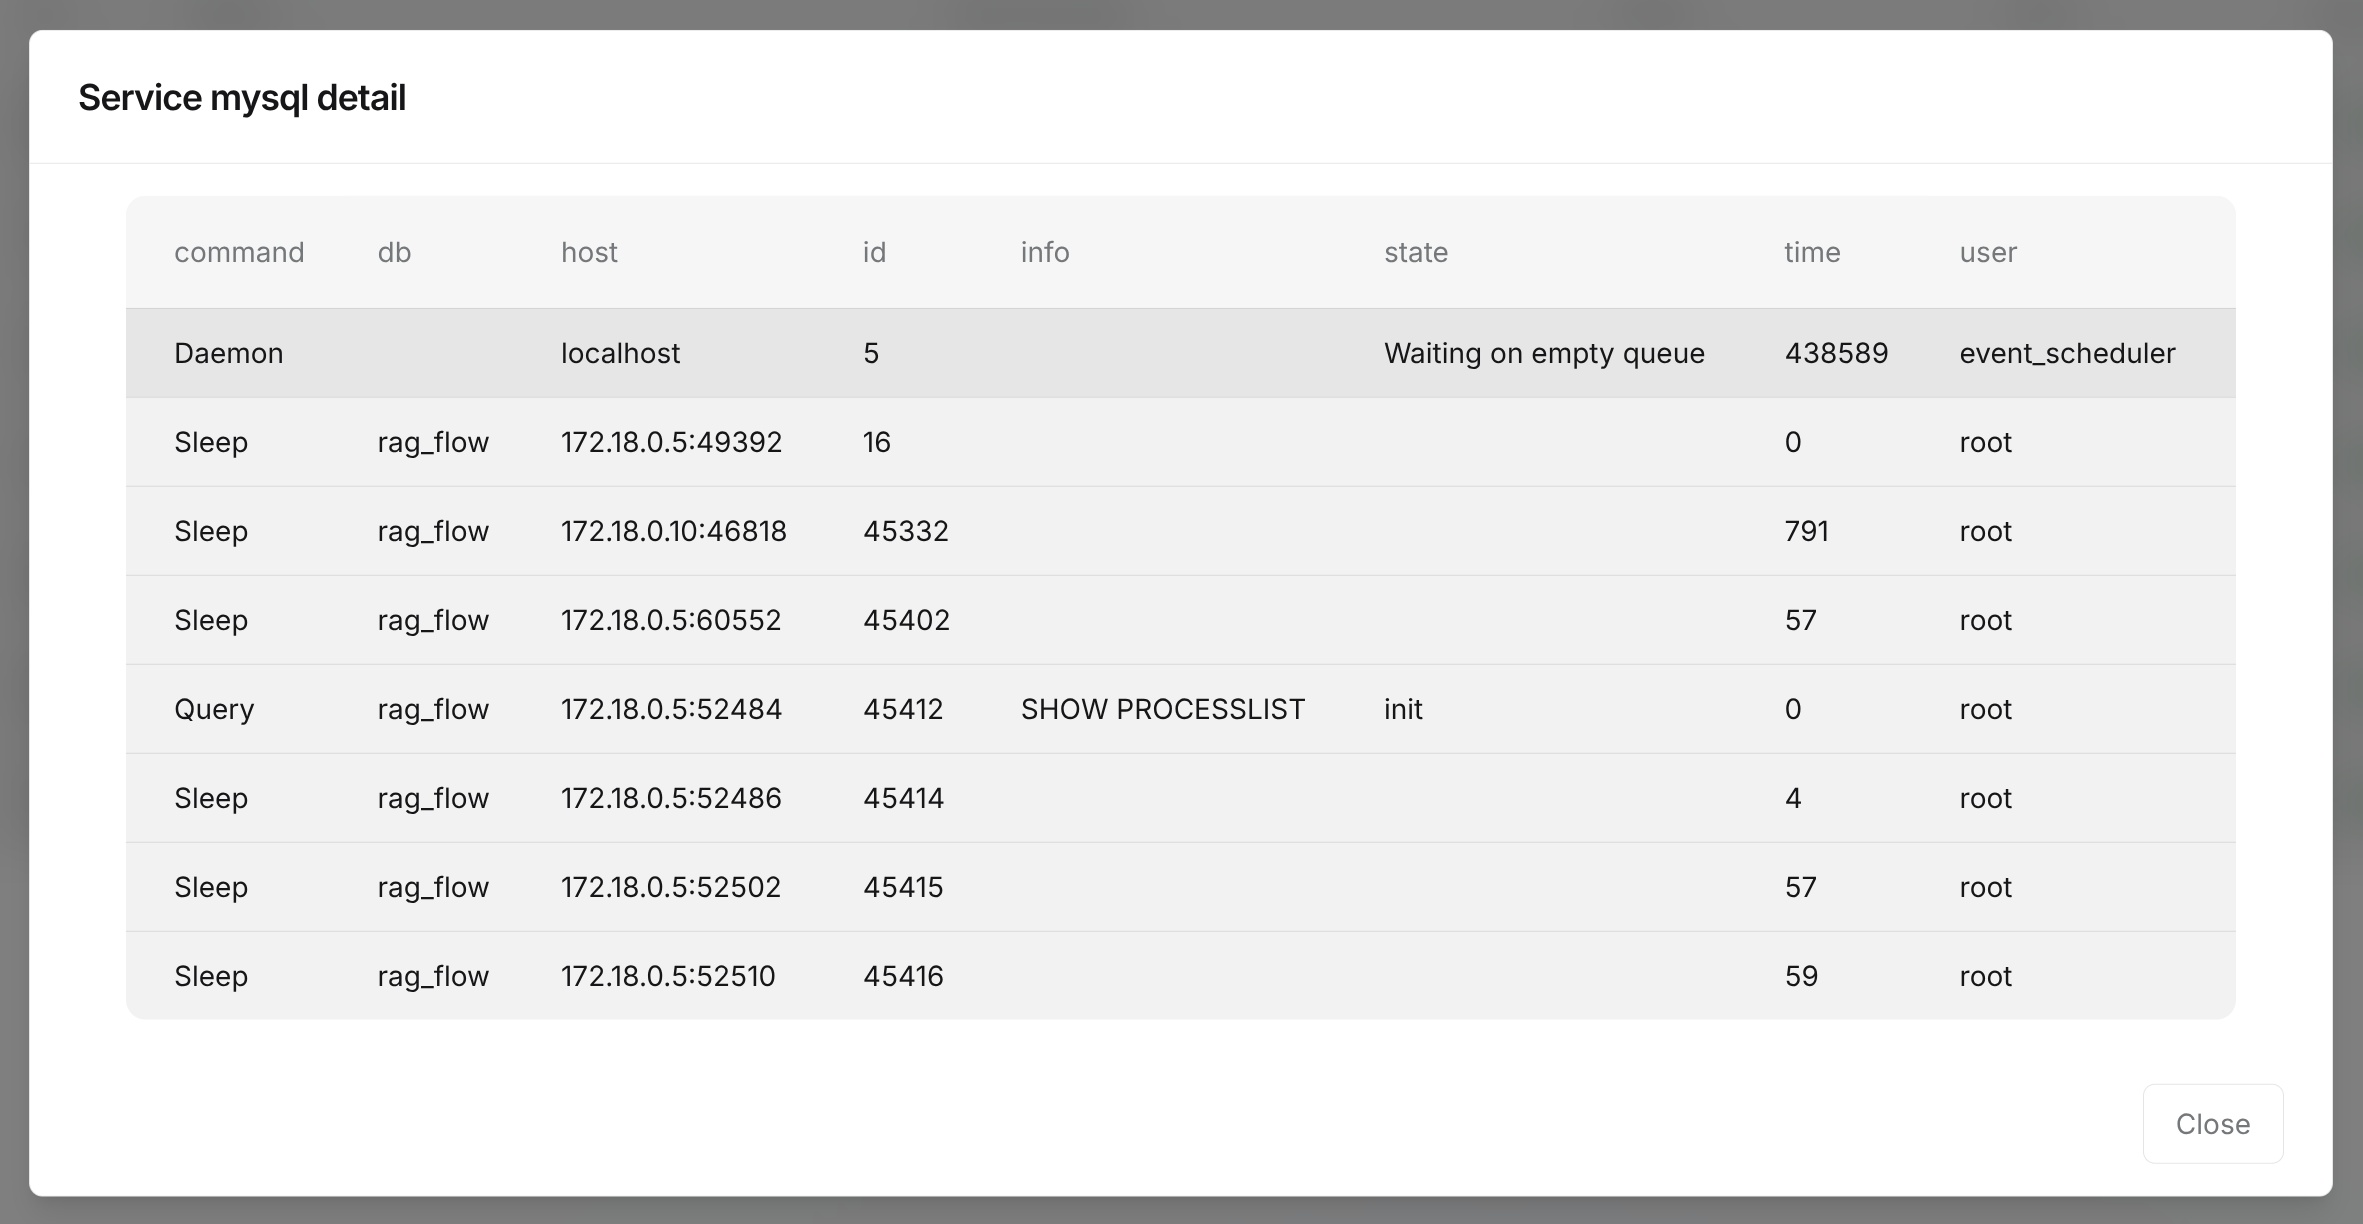
3. Read the properties in the **Service … detail** dialog. For example, the MySQL detail shows `type`, `name`, `host`, `port`, `status`, `elapsed`, and `message` as a property list.
|
||||
4. Click **Close** to return to the list.
|
||||
|
||||
The MySQL dialog displays the health-check record, not a database process list. Use your deployment's database administration tools if you need to inspect SQL sessions or processes.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
The **Extra information** dialog displays the elapsed value and message included in the same status record. A failed dependency check can place its error text in the message field.
|
||||
To view **Extra information**, hover over the service row and click the sliders icon in **Actions**. The dialog displays the elapsed value and message included in the status record. Click **Close** to return to the list. A failed dependency check can place its error text in the message field.
|
||||
|
||||
|
||||
|
||||
|
||||
@@ -6,7 +6,7 @@ title: Configure Code Execution Sandbox
|
||||
|
||||
# Configure Code Execution Sandbox
|
||||
|
||||
Administrators configure the active code execution provider in **Admin > Sandbox Settings**. For provider selection, deployment, security, and troubleshooting guidance, start with [Code Execution Sandbox](../../sandbox/overview.md).
|
||||
Administrators configure the active code execution provider in **Admin > Sandbox**. For provider selection, deployment, security, and troubleshooting guidance, start with [Code Execution Sandbox](../../sandbox/overview.md).
|
||||
|
||||
:::caution System-wide setting
|
||||
Saving a provider makes it active for subsequent Code component runs across this RAGFlow deployment. Test the configuration before replacing a provider that is already in use.
|
||||
@@ -14,11 +14,9 @@ Saving a provider makes it active for subsequent Code component runs across this
|
||||
|
||||
## Select a provider
|
||||
|
||||

|
||||
|
||||
The page supports:
|
||||
|
||||
| Provider | Detailed instructions |
|
||||
| Provider | Usage or detailed instructions |
|
||||
| --- | --- |
|
||||
| **Self-Managed** | [Quickstart with Self-Managed](../../sandbox/quickstart_with_self_managed.md) |
|
||||
| **SSH** | [Configure SSH](../../sandbox/configure_ssh_and_cloud_providers.md#configure-ssh) |
|
||||
@@ -26,6 +24,9 @@ The page supports:
|
||||
| **E2B** | [Configure E2B](../../sandbox/configure_ssh_and_cloud_providers.md#configure-e2b) |
|
||||
| **Tenki** | [Configure Tenki](../../sandbox/configure_ssh_and_cloud_providers.md#configure-tenki) |
|
||||
| **UCloud Agent Sandbox** | [Configure UCloud Agent Sandbox](../../sandbox/configure_ssh_and_cloud_providers.md#configure-ucloud-agent-sandbox) |
|
||||
| **Local** | Execute code directly on the current host process. |
|
||||
|
||||

|
||||
|
||||
## Test and save the configuration
|
||||
|
||||
|
||||
@@ -8,13 +8,13 @@ title: Manage User Accounts
|
||||
|
||||
## View and Search Users
|
||||
|
||||
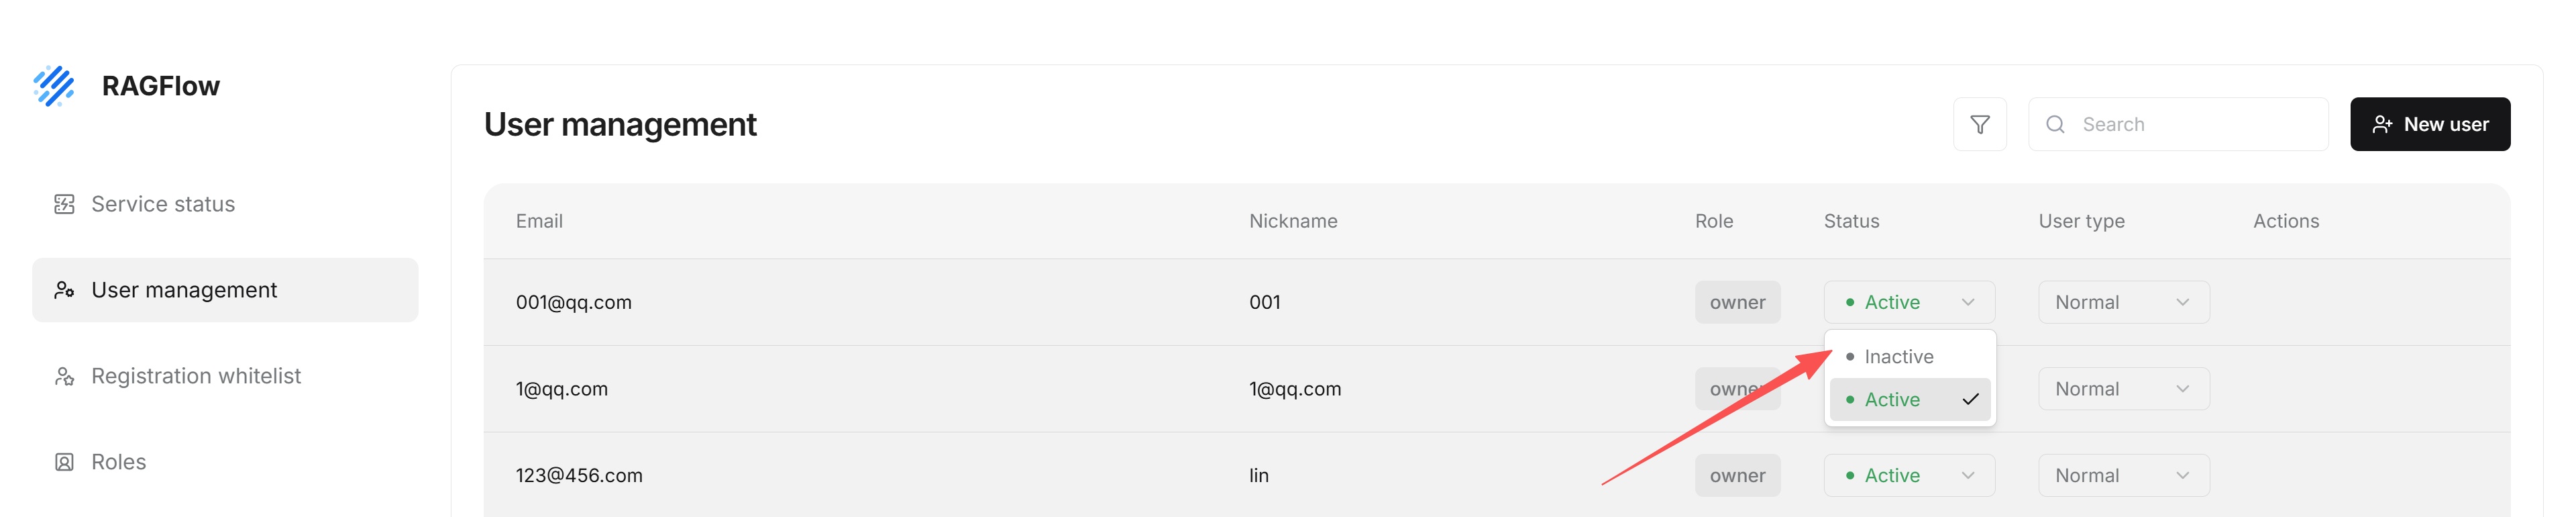
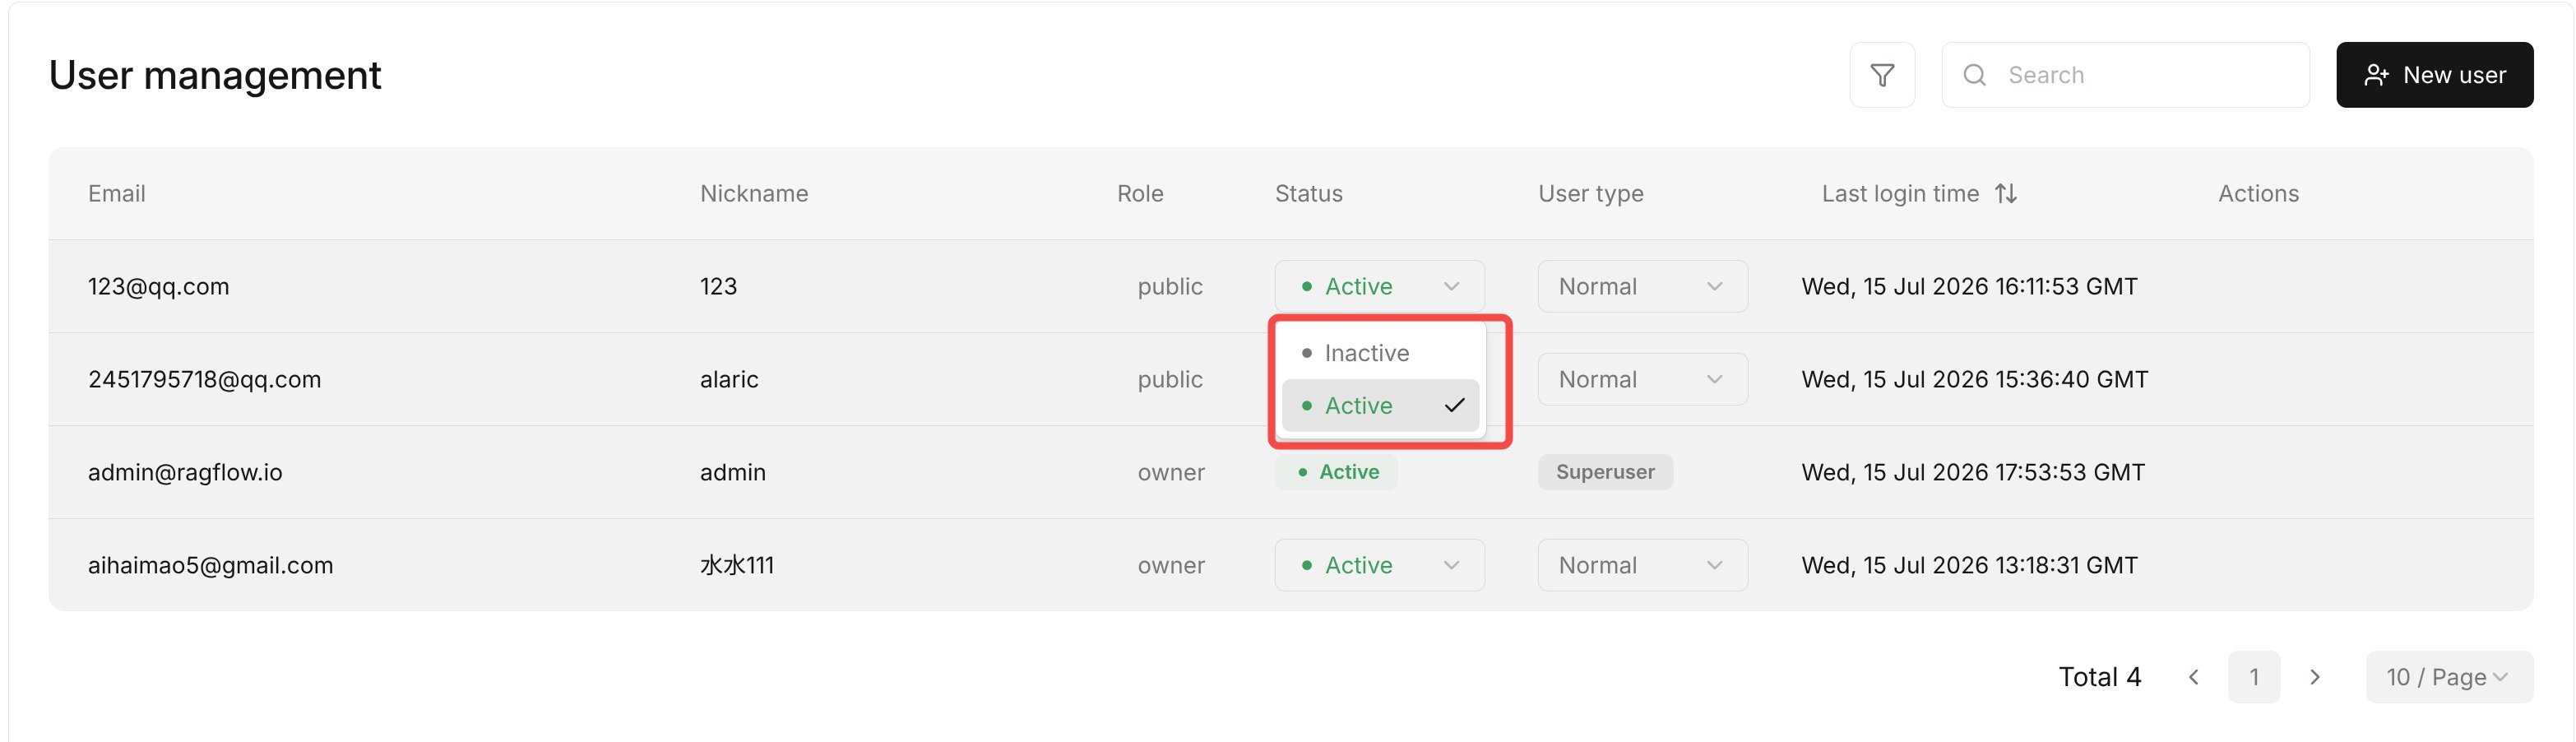
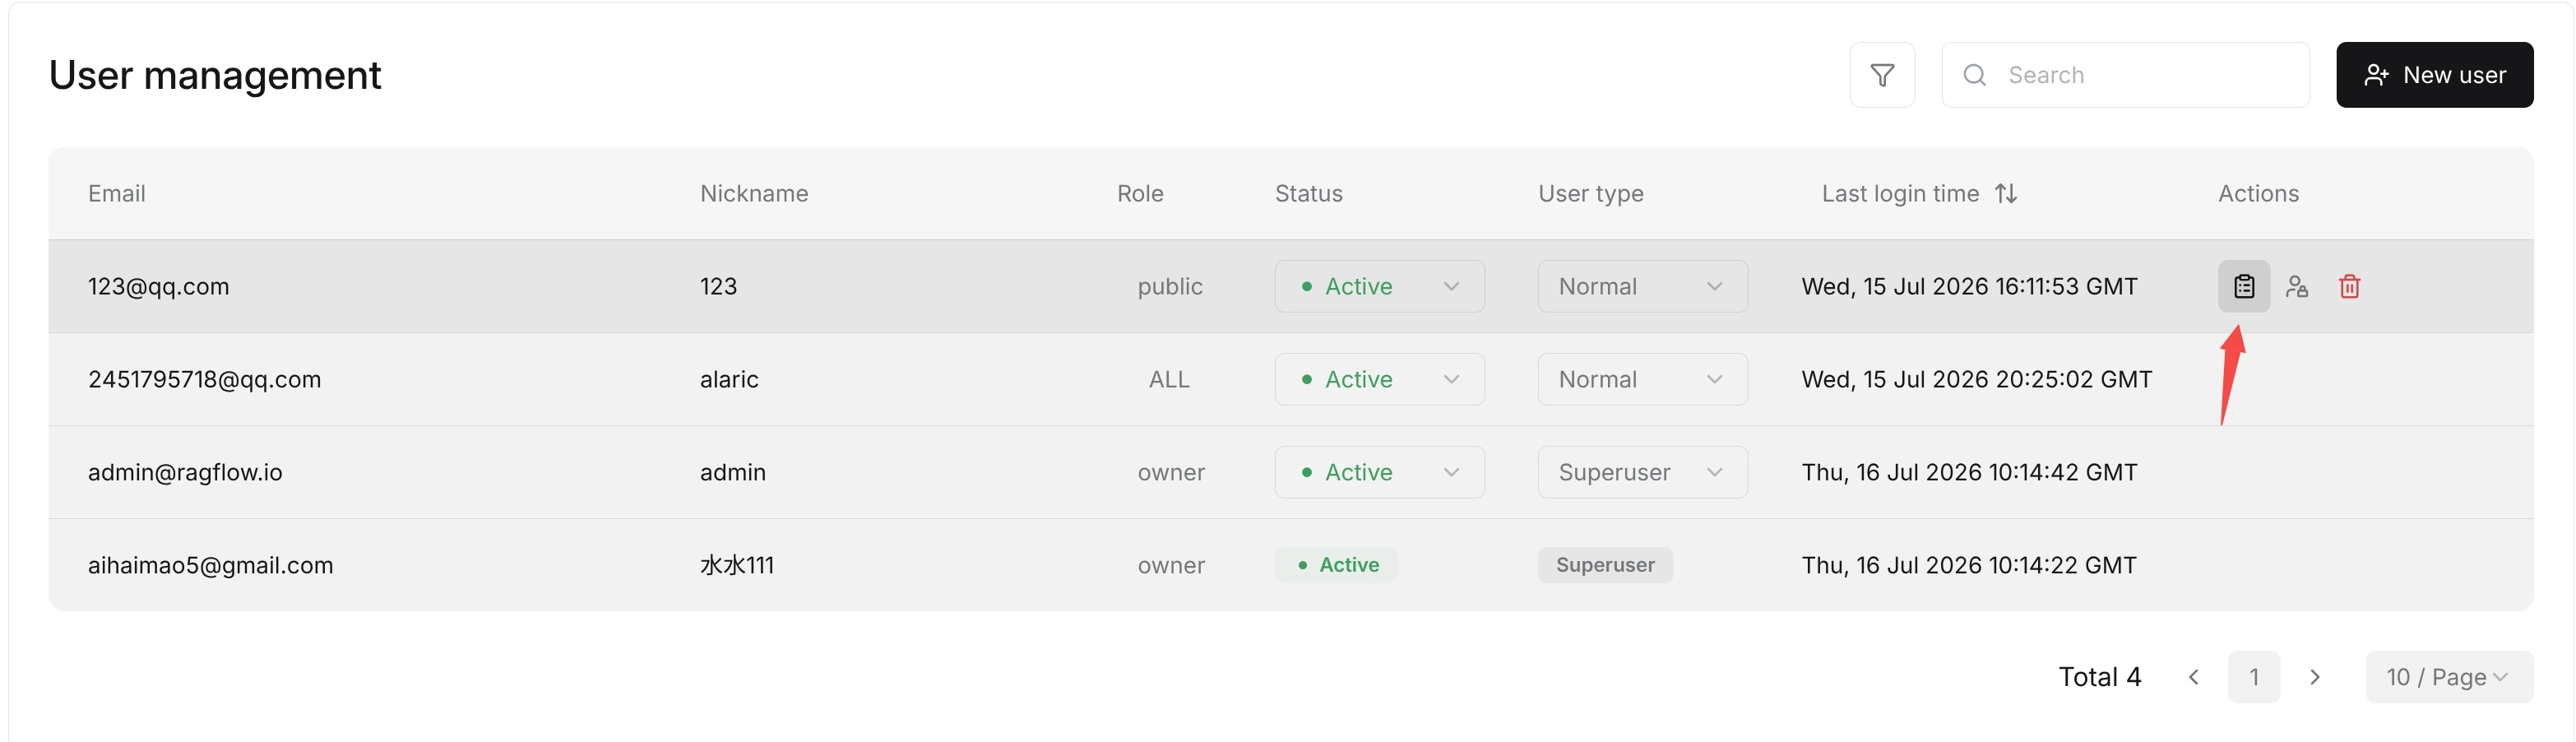
User accounts are managed on the **User management** page. Administrators can view the user list, including `Email`, `Nickname`, `Status`, and `User type`.
|
||||
User accounts are managed on the **Users** page. Administrators can view the user list, including `Email`, `Nickname`, `Status`, and `User type`.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
Use the search box in the upper-right corner to search users by `Email` or `Nickname`. You can also filter `Active` or `Inactive` users by `Status`.
|
||||
|
||||
@@ -24,19 +24,21 @@ Use the search box in the upper-right corner to search users by `Email` or `Nick
|
||||
|
||||
## Create a New User
|
||||
|
||||
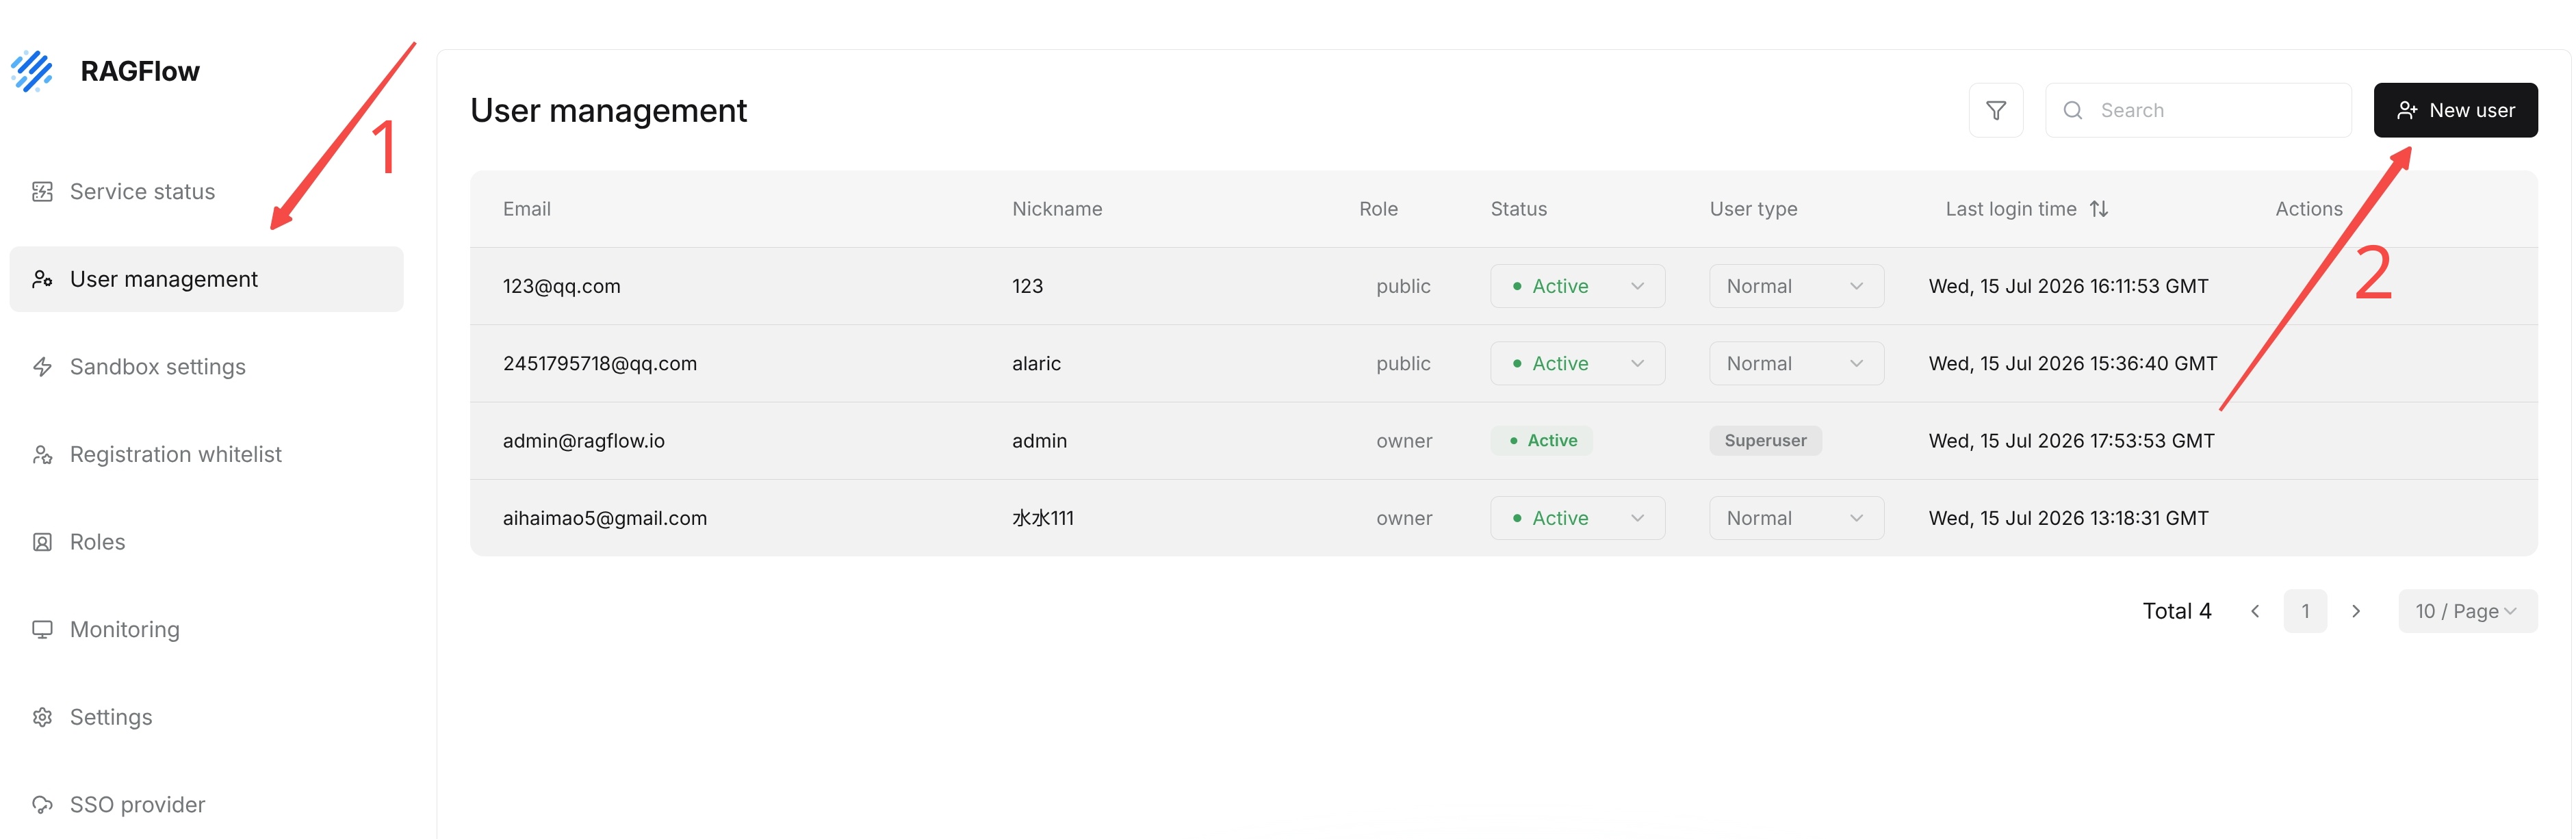
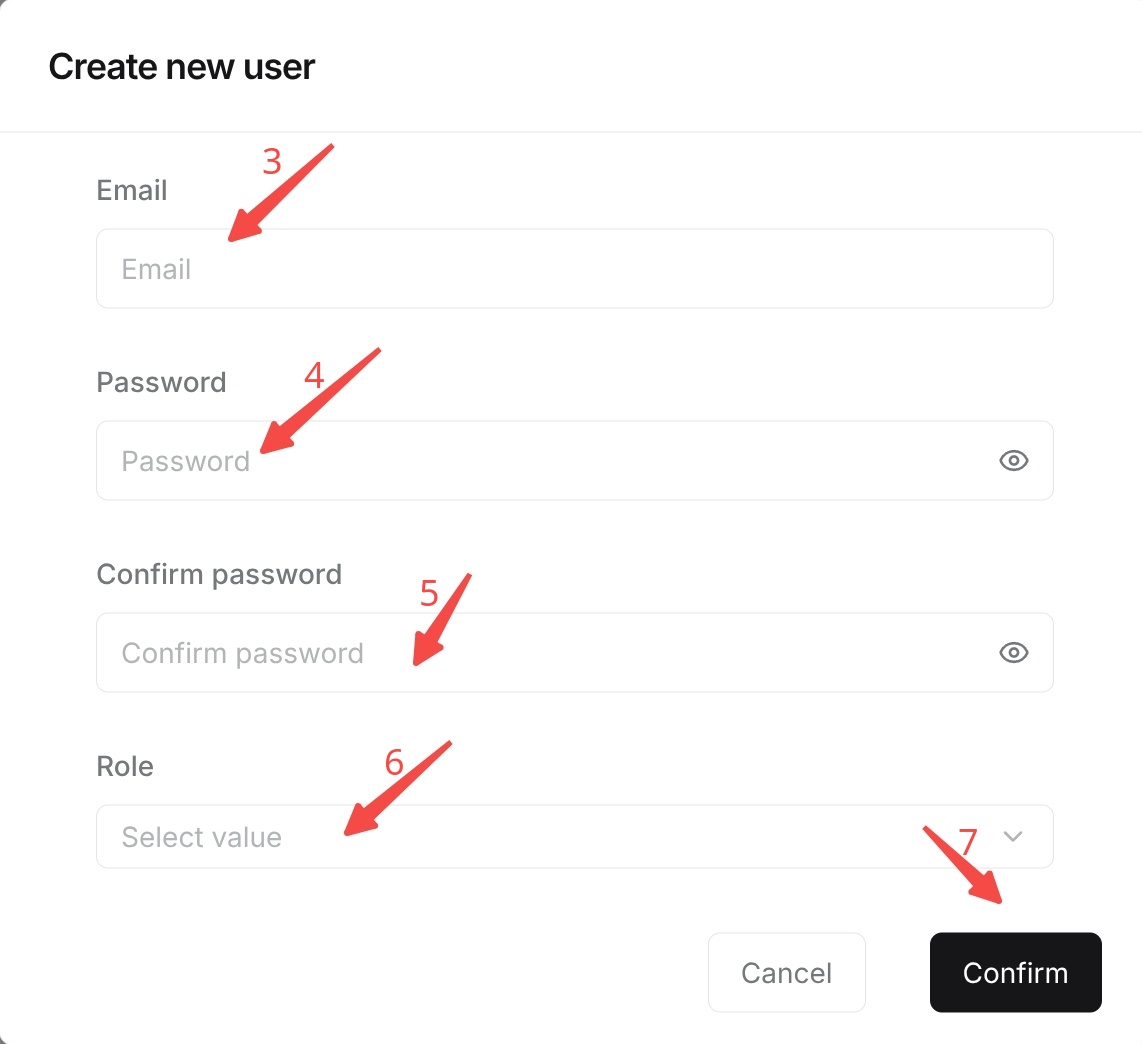
To create an account for a new member, go to **User management** and click **New user**. In the dialog, fill in `Email`, `Password`, and `Confirm password`.
|
||||
To create an account for a new member, go to **Users** and click **New user**. The **New user** dialog contains `Email`, `Password`, and `Confirm password`. It has no Role selector. Set the account type separately from the **User type** column after creation if needed; see [Set Backend Administrator Identity](#set-backend-administrator-identity).
|
||||
|
||||
1. Go to the **User management** page.
|
||||
1. Go to the **Users** page.
|
||||
2. Click **New user**.
|
||||
|
||||
|
||||
|
||||
3. Enter the user's `Email`.
|
||||
4. Enter the initial password.
|
||||
5. Enter the same password again in `Confirm password`.
|
||||
|
||||
|
||||
|
||||
6. Click **Confirm** to create the account.
|
||||
|
||||

|
||||
|
||||

|
||||
|
||||
After creation, return to the user list and confirm that the account appears and that its status matches expectations. Then send the login information to the user through a secure channel.
|
||||
|
||||
**Caution:** `Email` must use a valid email format. After email verification is enabled, users must complete email verification before they can use the account normally. If email verification is not enabled, the system only validates the email format.
|
||||
@@ -52,7 +54,7 @@ The `Status` field in the user list controls whether an account can log in to th
|
||||
| `Active` | The account is enabled and can log in and use the system normally. |
|
||||
| `Inactive` | The account is disabled. The user cannot log in, but the account and related data are retained. |
|
||||
|
||||
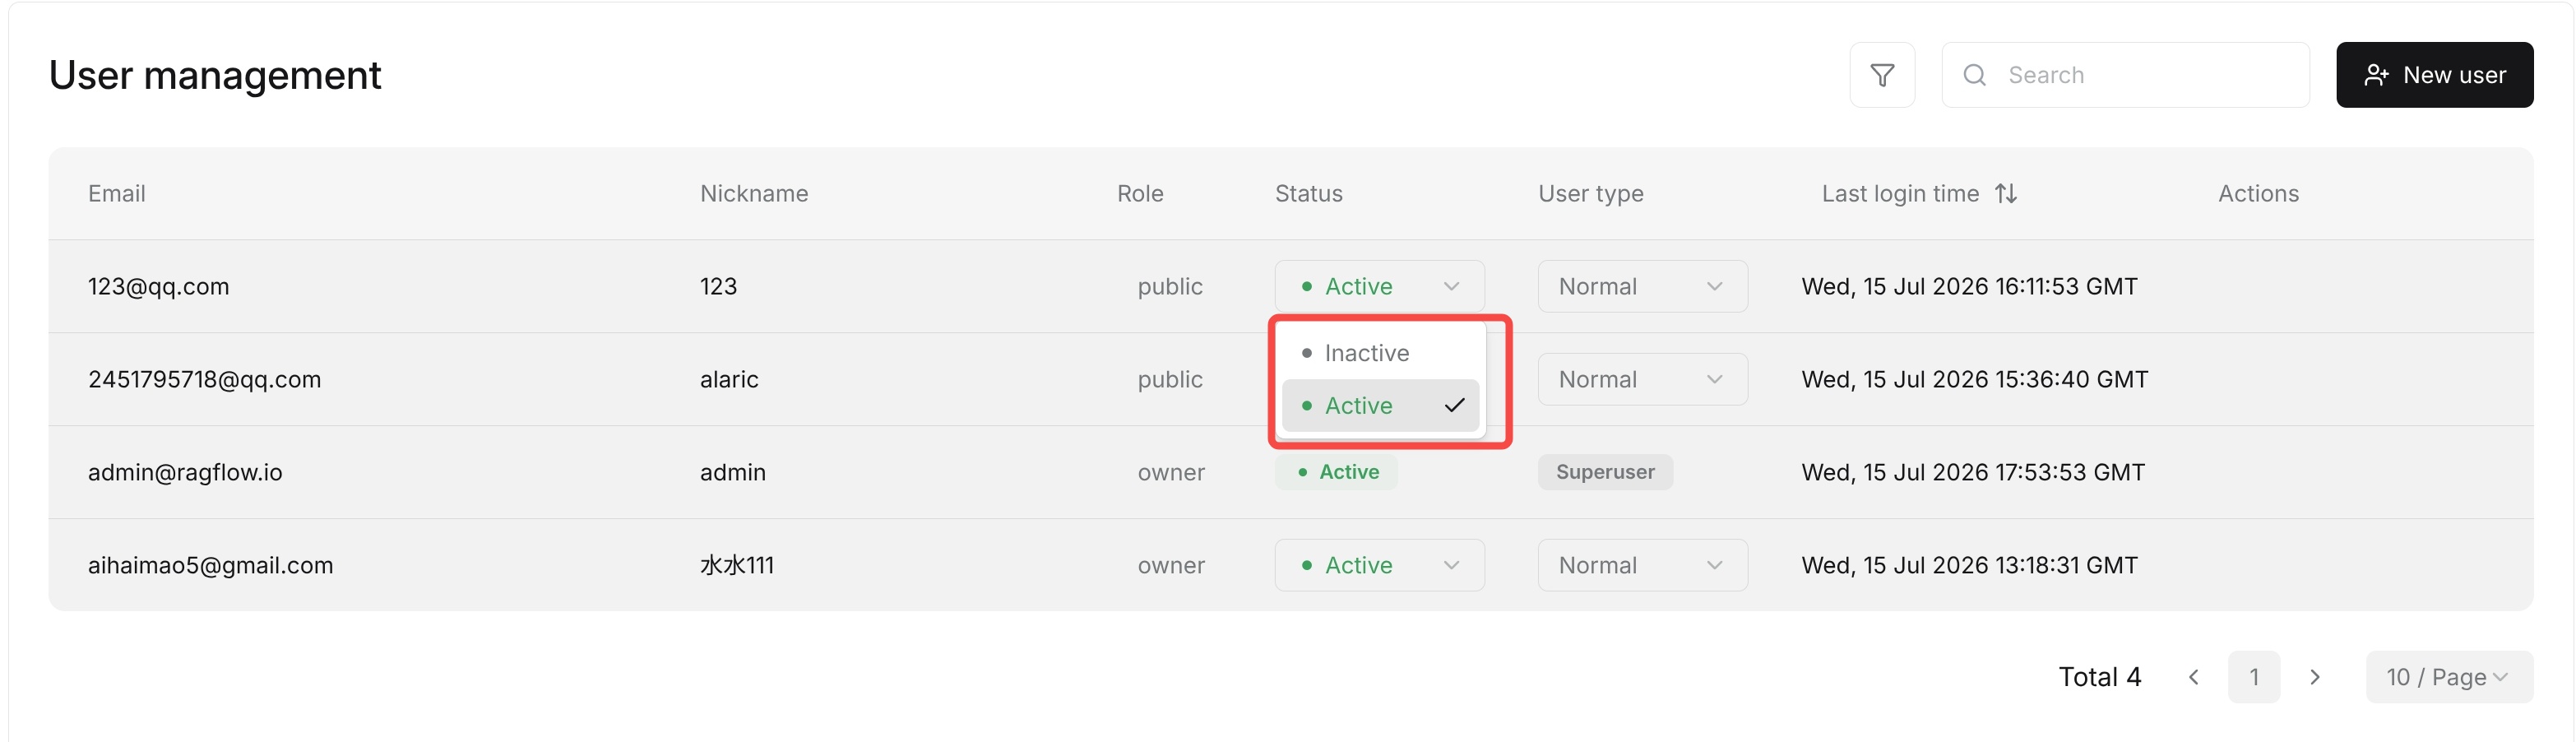
1. Go to the **User management** page and find the target user in the user list.
|
||||
1. Go to the **Users** page and find the target user in the user list.
|
||||
2. In the `Status` column of that user's row, click the current status dropdown and select `Active` or `Inactive` as needed.
|
||||
|
||||

|
||||
@@ -63,7 +65,7 @@ The `Status` field in the user list controls whether an account can log in to th
|
||||
|
||||
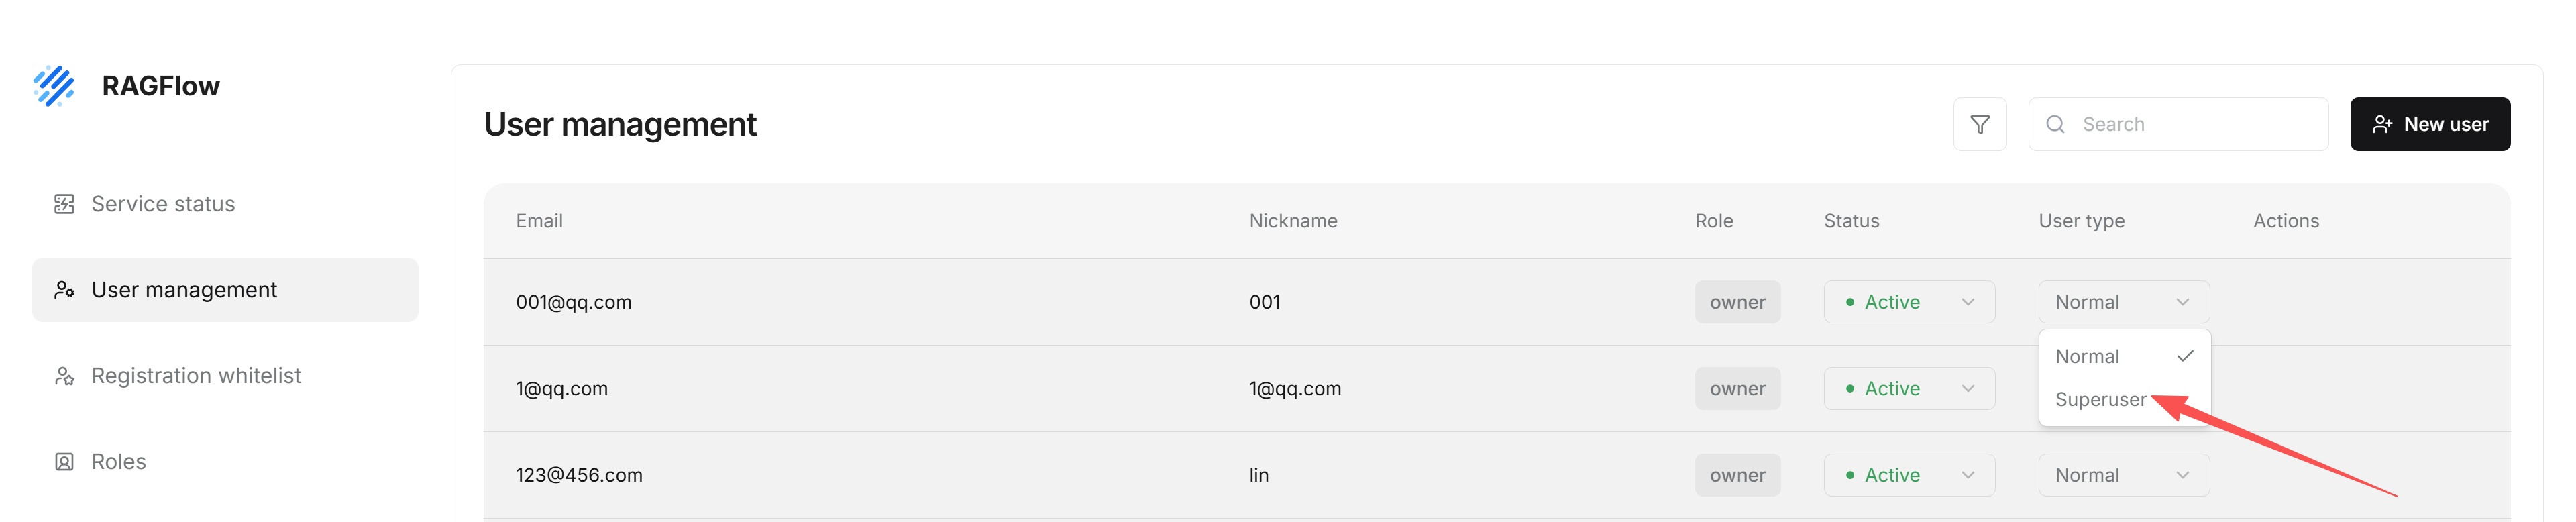
`User type` distinguishes `Normal` from `Superuser`. `Normal` is a regular user type. `Superuser` can enter the Admin UI and perform system-level management operations.
|
||||
|
||||
1. Find the target user on the **User management** page.
|
||||
1. Find the target user on the **Users** page.
|
||||
2. Open the selector in the `User type` column.
|
||||
3. Select `Normal` or `Superuser`.
|
||||
4. Wait for the system to submit the change and refresh the user list.
|
||||
@@ -76,7 +78,7 @@ The `Status` field in the user list controls whether an account can log in to th
|
||||
|
||||
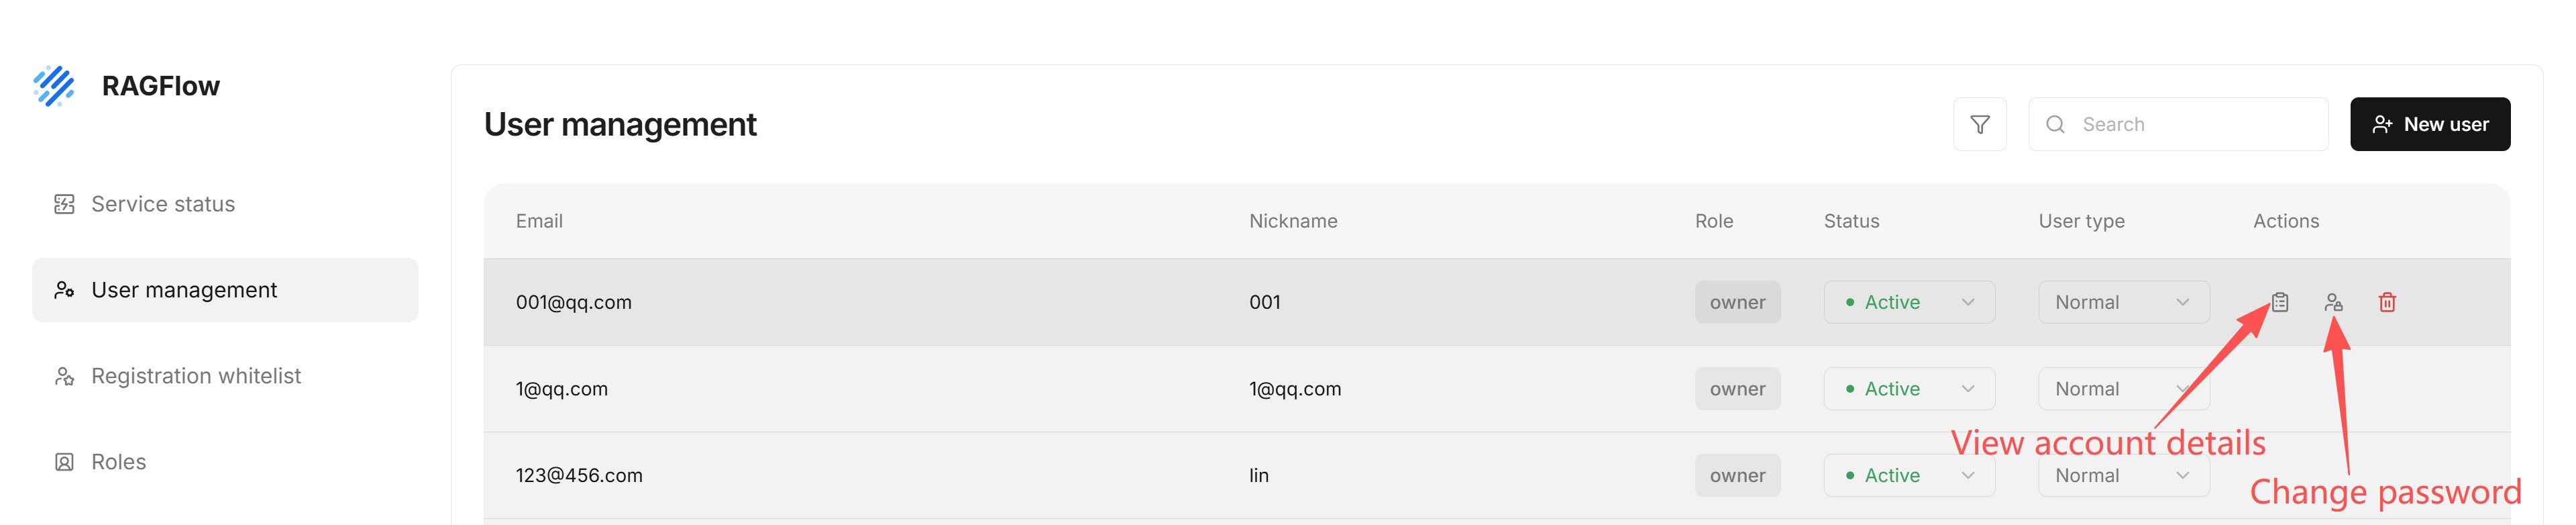
When a user forgets their password or must be forced to change it, administrators can reset another user's password from **Actions** in the user list. After the reset-password dialog opens, the page displays the target user's `Email` and requires `New password` and `Confirm new password`.
|
||||
|
||||
1. Find the target user on the **User management** page. Hover over the user row to display **Actions**, then click the reset-password button.
|
||||
1. Find the target user on the **Users** page. Hover over the user row to display **Actions**, then click the reset-password button.
|
||||
2. Confirm that the `Email` in the dialog is the target user.
|
||||
3. Enter the new password and confirm it again.
|
||||
4. Click **Change password**.
|
||||
@@ -93,7 +95,7 @@ When a user no longer needs system access and related resources have been handed
|
||||
|
||||
Before deleting a user, set their account status to **Inactive**. If their user type is **Superuser**, change it to **Normal** first. The backend rejects deletion of active accounts and Superuser accounts.
|
||||
|
||||
1. Find the target user on the **User management** page and set **Status** to **Inactive**.
|
||||
1. Find the target user on the **Users** page and set **Status** to **Inactive**.
|
||||
2. If **User type** is **Superuser**, change it to **Normal**.
|
||||
3. Hover over the user row to display **Actions**, then click the delete button.
|
||||
4. Check the user's `Email` in the confirmation dialog.
|
||||
|
||||
@@ -18,7 +18,7 @@ Saving a provider configuration makes it the active code execution provider for
|
||||
Use the same workflow for every provider:
|
||||
|
||||
1. Prepare the remote host or cloud account, credentials, and network access.
|
||||
2. Open **Admin > Sandbox Settings**.
|
||||
2. Open **Admin > Sandbox**.
|
||||
3. Select the provider and complete its settings.
|
||||
4. Select **Test connection**.
|
||||
5. Confirm that the result shows `PASSED`, then select **Save**.
|
||||
@@ -53,7 +53,7 @@ Make sure that:
|
||||
|
||||
RAGFlow verifies the SSH server's host key before sending credentials or running code. Confirm the server's host-key fingerprint with the server administrator, then add the verified key to the `known_hosts` file used by RAGFlow.
|
||||
|
||||
For a server that listens on a non-default port, include the port when collecting the key. Replace `SSH_HOST` and `SSH_PORT` with the values configured in **Admin > Sandbox Settings**. For example, if the actual host is `sandbox.example.com` and the port is `2222`, use `[sandbox.example.com]:2222`.
|
||||
For a server that listens on a non-default port, include the port when collecting the key. Replace `SSH_HOST` and `SSH_PORT` with the values configured in **Admin > Sandbox**. For example, if the actual host is `sandbox.example.com` and the port is `2222`, use `[sandbox.example.com]:2222`.
|
||||
|
||||
The `[SSH_HOST]:SSH_PORT` format is for non-default ports. For port `22`, use `SSH_HOST` without brackets or a port in the `ssh-keygen -F` and `ssh-keygen -R` commands.
|
||||
|
||||
@@ -137,7 +137,7 @@ In **SSH known_hosts File**, enter the path that is visible to the RAGFlow proce
|
||||
|
||||
### Configure the connection
|
||||
|
||||
In **Admin > Sandbox Settings**, select **SSH** and configure:
|
||||
In **Admin > Sandbox**, select **SSH** and configure:
|
||||
|
||||
| Setting | Required | Value |
|
||||
| --- | --- | --- |
|
||||
@@ -177,7 +177,7 @@ Select **Test connection**. Confirm that the result shows `PASSED`, then select
|
||||
|
||||
## Configure Aliyun Code Interpreter
|
||||
|
||||
Prepare a RAM user with Code Interpreter permissions and [create an Alibaba Cloud AccessKey pair](https://help.aliyun.com/en/ram/user-guide/create-an-accesskey-pair). Then select **Aliyun Code Interpreter** in **Admin > Sandbox Settings** and configure:
|
||||
Prepare a RAM user with Code Interpreter permissions and [create an Alibaba Cloud AccessKey pair](https://help.aliyun.com/en/ram/user-guide/create-an-accesskey-pair). Then select **Aliyun Code Interpreter** in **Admin > Sandbox** and configure:
|
||||
|
||||
| Setting | Required | Default | Description |
|
||||
| --- | --- | --- | --- |
|
||||
@@ -190,7 +190,7 @@ Prepare a RAM user with Code Interpreter permissions and [create an Alibaba Clou
|
||||
|
||||
## Configure E2B
|
||||
|
||||
Create an API key in the [E2B dashboard](https://e2b.dev/dashboard). Then select **E2B** in **Admin > Sandbox Settings** and configure:
|
||||
Create an API key in the [E2B dashboard](https://e2b.dev/dashboard). Then select **E2B** in **Admin > Sandbox** and configure:
|
||||
|
||||
| Setting | Required | Default | Description |
|
||||
| --- | --- | --- | --- |
|
||||
@@ -209,7 +209,7 @@ For source deployments, set `E2B_DOMAIN` in the RAGFlow process environment and
|
||||
|
||||
## Configure Tenki
|
||||
|
||||
Create an API key in the [Tenki console](https://app.tenki.cloud). For provider setup, see the [Tenki Sandbox Quickstart](https://tenki.cloud/docs/sandbox/quickstart). Then select **Tenki** in **Admin > Sandbox Settings** and configure:
|
||||
Create an API key in the [Tenki console](https://app.tenki.cloud). For provider setup, see the [Tenki Sandbox Quickstart](https://tenki.cloud/docs/sandbox/quickstart). Then select **Tenki** in **Admin > Sandbox** and configure:
|
||||
|
||||
| Setting | Required | Default | Description |
|
||||
| --- | --- | --- | --- |
|
||||
@@ -230,7 +230,7 @@ Keep outbound networking disabled unless executed code requires it.
|
||||
|
||||
## Configure UCloud Agent Sandbox
|
||||
|
||||
Obtain an API key from [UCloud ModelVerse API Keys](https://astraflow.ucloud.cn/modelverse/api-keys). Then select **UCloud Agent Sandbox** in **Admin > Sandbox Settings** and configure:
|
||||
Obtain an API key from [UCloud ModelVerse API Keys](https://astraflow.ucloud.cn/modelverse/api-keys). Then select **UCloud Agent Sandbox** in **Admin > Sandbox** and configure:
|
||||
|
||||
| Setting | Required | Default | Description |
|
||||
| --- | --- | --- | --- |
|
||||
|
||||
@@ -31,7 +31,7 @@ If the service is not `healthy`, inspect its logs:
|
||||
docker compose logs --tail=200 sandbox-executor-manager
|
||||
```
|
||||
|
||||
The `/healthz` endpoint only confirms that Executor Manager is responding. To verify that it can create a Runner and execute code, open **Admin > Sandbox Settings**, select **Self-Managed**, and run **Test connection**. A successful test displays `PASSED`.
|
||||
The `/healthz` endpoint only confirms that Executor Manager is responding. To verify that it can create a Runner and execute code, open **Admin > Sandbox**, select **Self-Managed**, and run **Test connection**. A successful test displays `PASSED`.
|
||||
|
||||
After deployment changes, also run a Code component to verify the complete path from RAGFlow through Executor Manager to the Runner.
|
||||
|
||||
@@ -72,7 +72,7 @@ The supplied RAGFlow Compose service publishes port `9385` on `127.0.0.1` only,
|
||||
curl -f https://sandbox.example.com/healthz
|
||||
```
|
||||
|
||||
5. Open **Admin > Sandbox Settings** and select **Self-Managed**.
|
||||
5. Open **Admin > Sandbox** and select **Self-Managed**.
|
||||
6. Enter the remote URL in **Executor Manager Endpoint** and the matching token in **Executor Manager API Token**.
|
||||
7. Run **Test connection**, confirm `PASSED`, and save the configuration.
|
||||
|
||||
@@ -193,7 +193,7 @@ The Compose service accepts one configured token. Requests can fail between rest
|
||||
docker compose up -d sandbox-executor-manager
|
||||
```
|
||||
|
||||
4. In **Admin > Sandbox Settings**, enter the new token under **Self-Managed**.
|
||||
4. In **Admin > Sandbox**, enter the new token under **Self-Managed**.
|
||||
5. Run **Test connection**, confirm `PASSED`, and select **Save**.
|
||||
6. Run a Code component and confirm that execution succeeds.
|
||||
|
||||
|
||||
@@ -29,11 +29,14 @@ Choose the provider that matches where you want code to run and who should manag
|
||||
| [**E2B**](./configure_ssh_and_cloud_providers.md#configure-e2b) | E2B cloud sandboxes | You want an externally managed cloud sandbox without operating local Runner containers. |
|
||||
| [**Tenki**](./configure_ssh_and_cloud_providers.md#configure-tenki) | A disposable Tenki microVM created for each execution | You want each run to use an isolated, short-lived cloud microVM. |
|
||||
| [**UCloud Agent Sandbox**](./configure_ssh_and_cloud_providers.md#configure-ucloud-agent-sandbox) | A disposable UCloud Agent Sandbox | You want a managed cloud sandbox in a supported UCloud region. |
|
||||
| **Local** | Directly on the current host process | You want to execute code on the RAGFlow host rather than through a remote service or Runner container. |
|
||||
|
||||
:::note Before choosing a cloud provider
|
||||
Confirm that your RAGFlow deployment can reach the provider's API, and that your account has valid credentials, sufficient quota, and access to the required region.
|
||||
:::
|
||||
|
||||
To select **Local**, open **Admin > Sandbox**, choose the **Local** card, review its displayed settings, and click **Save** to make it active. Code executes on the current host; this option does not provide the container or microVM separation offered by other providers.
|
||||
|
||||
## Recommended path for private deployments
|
||||
|
||||
For most private or on-premises deployments, start with **Self-Managed**. In the standard deployment:
|
||||
|
||||
@@ -16,7 +16,7 @@ You need:
|
||||
- A Linux host with Docker and Docker Compose.
|
||||
- Permission to run Docker containers. The deployment must allow privileged containers and Docker socket access.
|
||||
- A running RAGFlow deployment or a working RAGFlow source environment.
|
||||
- Access to **Admin > Sandbox Settings**.
|
||||
- Access to **Admin > Sandbox**.
|
||||
- Network access to pull images from Docker Hub.
|
||||
|
||||
You do not need to install Python or Node.js on the RAGFlow host. They run in the Sandbox Runner containers.
|
||||
@@ -31,7 +31,7 @@ Continue only if this command displays Docker server information. If it returns
|
||||
|
||||
## 1. Determine the Sandbox endpoint
|
||||
|
||||
First, identify where RAGFlow and Sandbox Executor Manager are running. Their deployment locations determine the endpoint that you must enter later in **Admin > Sandbox Settings**.
|
||||
First, identify where RAGFlow and Sandbox Executor Manager are running. Their deployment locations determine the endpoint that you must enter later in **Admin > Sandbox**.
|
||||
|
||||
| Deployment scenario | Endpoint |
|
||||
| --- | --- |
|
||||
@@ -145,7 +145,7 @@ Check the startup logs for the active runtime. `falling back to runc` means exec
|
||||
|
||||
## 5. Configure Self-Managed in Admin
|
||||
|
||||
1. Open **Admin > Sandbox Settings**.
|
||||
1. Open **Admin > Sandbox**.
|
||||
2. Select **Self-Managed**.
|
||||
3. Complete the connection settings:
|
||||
|
||||
|
||||
+1
-3
@@ -33,9 +33,7 @@ RAGFlow provides an end-to-end RAG platform that goes beyond basic document chun
|
||||
|
||||
### Where can I find the RAGFlow version, and how do I interpret it?
|
||||
|
||||
You can find the RAGFlow version number on the **System** page of the UI:
|
||||
|
||||

|
||||
For self-hosted deployments, open **User settings** on a desktop-sized screen. The RAGFlow version number is displayed at the bottom-left of the settings page. It is hidden on narrow screens and is not displayed in RAGFlow Cloud (`cloud.ragflow.io`).
|
||||
|
||||
If you build RAGFlow from source, the Go admin and ingestor log their versions at startup. The server also prints its version with `bin/ragflow_server --api --version`.
|
||||
|
||||
|
||||
@@ -106,7 +106,7 @@ Configuration steps:
|
||||
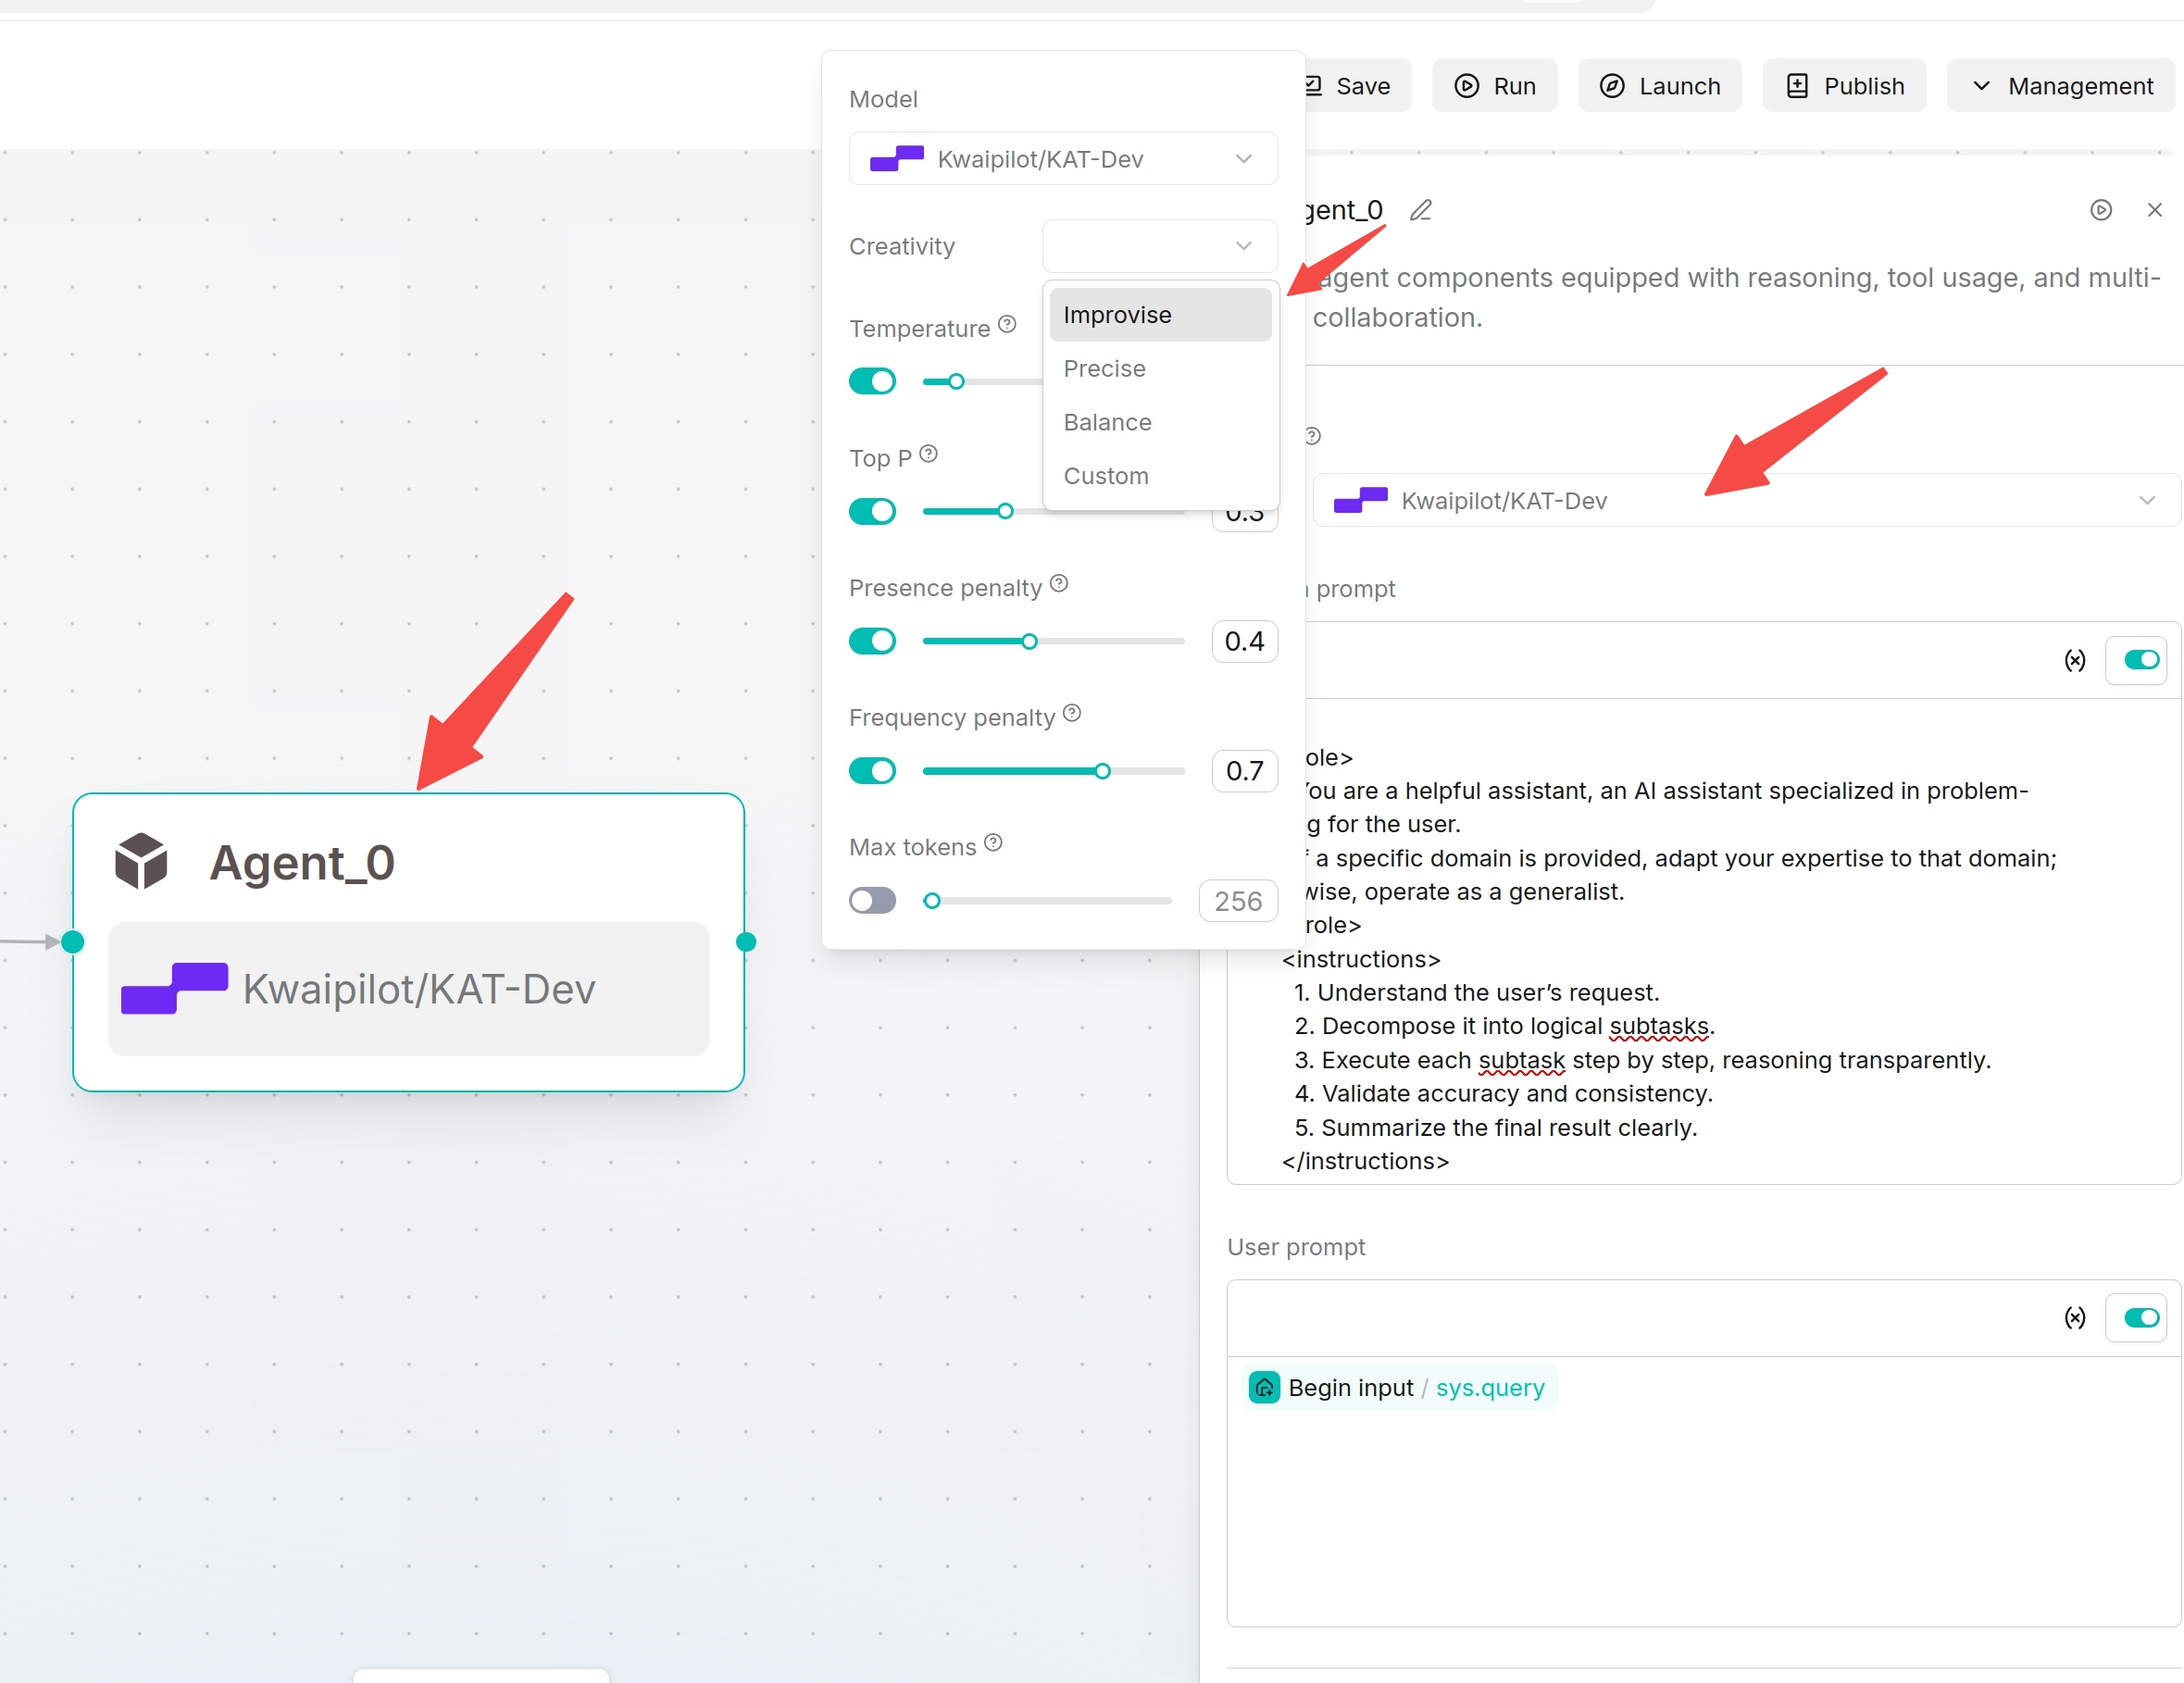
5. Write the task in **User prompt**, and insert variables by typing `/`.
|
||||
6. Add Retrieval, Execute SQL, or other tools offered by **Tools**, select MCP tools, or add sub-agents under **Agent**. For a fixed HTTP call, connect a separate **HTTP Request** workflow node.
|
||||
7. Review the `content` output, or enable structured output and configure its schema when needed.
|
||||
8. Click **Save**, then **Run** to check the result.
|
||||
8. Click **Save draft**, then **Run** to check the result.
|
||||
|
||||
|
||||
|
||||
@@ -187,7 +187,7 @@ Configuration steps:
|
||||
|
||||
**Rerank candidate count** controls the number of retrieval candidates available for reranking. The default shown in the panel is `64`. This is separate from **Top N**, which limits the results passed to downstream components.
|
||||
|
||||
The initial **Similarity threshold** is `0.2` (displayed as `20` in the percentage-based control), and the initial **Top N** is `8`. The recommendations below are tuning suggestions rather than defaults. **Meta data** filters can also constrain retrieval; check the selected datasets and filter conditions when relevant content is missing.
|
||||
The initial **Similarity threshold** displayed in the UI is `20`, meaning 20%, and the initial **Top N** is `8`. The recommendations below are tuning suggestions rather than defaults. **Meta data** filters can also constrain retrieval; check the selected datasets and filter conditions when relevant content is missing.
|
||||
|
||||
**Top N** specifies the number of chunks sent to subsequent components. Too few chunks may result in insufficient information, while too many chunks may increase response time and context pressure.
|
||||
|
||||
@@ -196,7 +196,7 @@ Enabling a **Rerank model** usually improves the sorting of knowledge retrieval
|
||||
|
||||
### Configuration Suggestions
|
||||
|
||||
The following values are only initial configuration references. Actual results are affected by the embedding model, document quality, chunking method, and business questions. Adjust them based on knowledge retrieval test results.
|
||||
Similarity threshold values below use the UI percentage scale: enter `20`, `50`, or `80` for 20%, 50%, or 80%. The following values are only initial configuration references. Actual results are affected by the embedding model, document quality, chunking method, and business questions. Adjust them based on knowledge retrieval test results.
|
||||
|
||||
Retrieval parameters directly affect answer coverage, accuracy, and response time. You can start with the settings in the following table, and then optimize them based on real questions.
|
||||
|
||||
@@ -205,6 +205,6 @@ Retrieval parameters directly affect answer coverage, accuracy, and response tim
|
||||
| Top N | 3-5 | FAQ and short knowledge entries | Faster responses for clear answers. |
|
||||
| Top N | 5-10 | Product documentation and help centers | A suggested range to test with representative questions. |
|
||||
| Top N | 10-20 | Legal contracts and long document analysis | More context with higher token consumption. |
|
||||
| Similarity threshold | 0.2 | Loose recall | Questions with diverse expressions. |
|
||||
| Similarity threshold | 0.5 | General Q&A | A stricter tuning example; the initial value is 0.2. |
|
||||
| Similarity threshold | 0.8 | Strict precise matching | Scenarios that require exact terminology matching. |
|
||||
| Similarity threshold | 20 | Loose recall | Questions with diverse expressions. |
|
||||
| Similarity threshold | 50 | General Q&A | A stricter tuning example; the initial UI value is 20 (20%). |
|
||||
| Similarity threshold | 80 | Strict precise matching | Scenarios that require exact terminology matching. |
|
||||
@@ -12,7 +12,7 @@ sidebar_custom_props: {
|
||||
## Code Component
|
||||
The Code component executes Python or JavaScript code for complex data processing, format conversion, calculation, file generation and custom logic.
|
||||
|
||||
Prerequisite: An administrator must configure a provider in **Admin > Sandbox Settings**. See [Code Execution Sandbox](../../../administrator/sandbox/overview.md). For a private deployment, follow [Quickstart with Self-Managed](../../../administrator/sandbox/quickstart_with_self_managed.md).
|
||||
Prerequisite: An administrator must configure a provider in **Admin > Sandbox**. See [Code Execution Sandbox](../../../administrator/sandbox/overview.md). For a private deployment, follow [Quickstart with Self-Managed](../../../administrator/sandbox/quickstart_with_self_managed.md).
|
||||
|
||||
Configuration:
|
||||
1. **Input**: Define parameters passed into code; variables can be directly referenced inside scripts.
|
||||
@@ -83,7 +83,7 @@ Configuration Steps:
|
||||
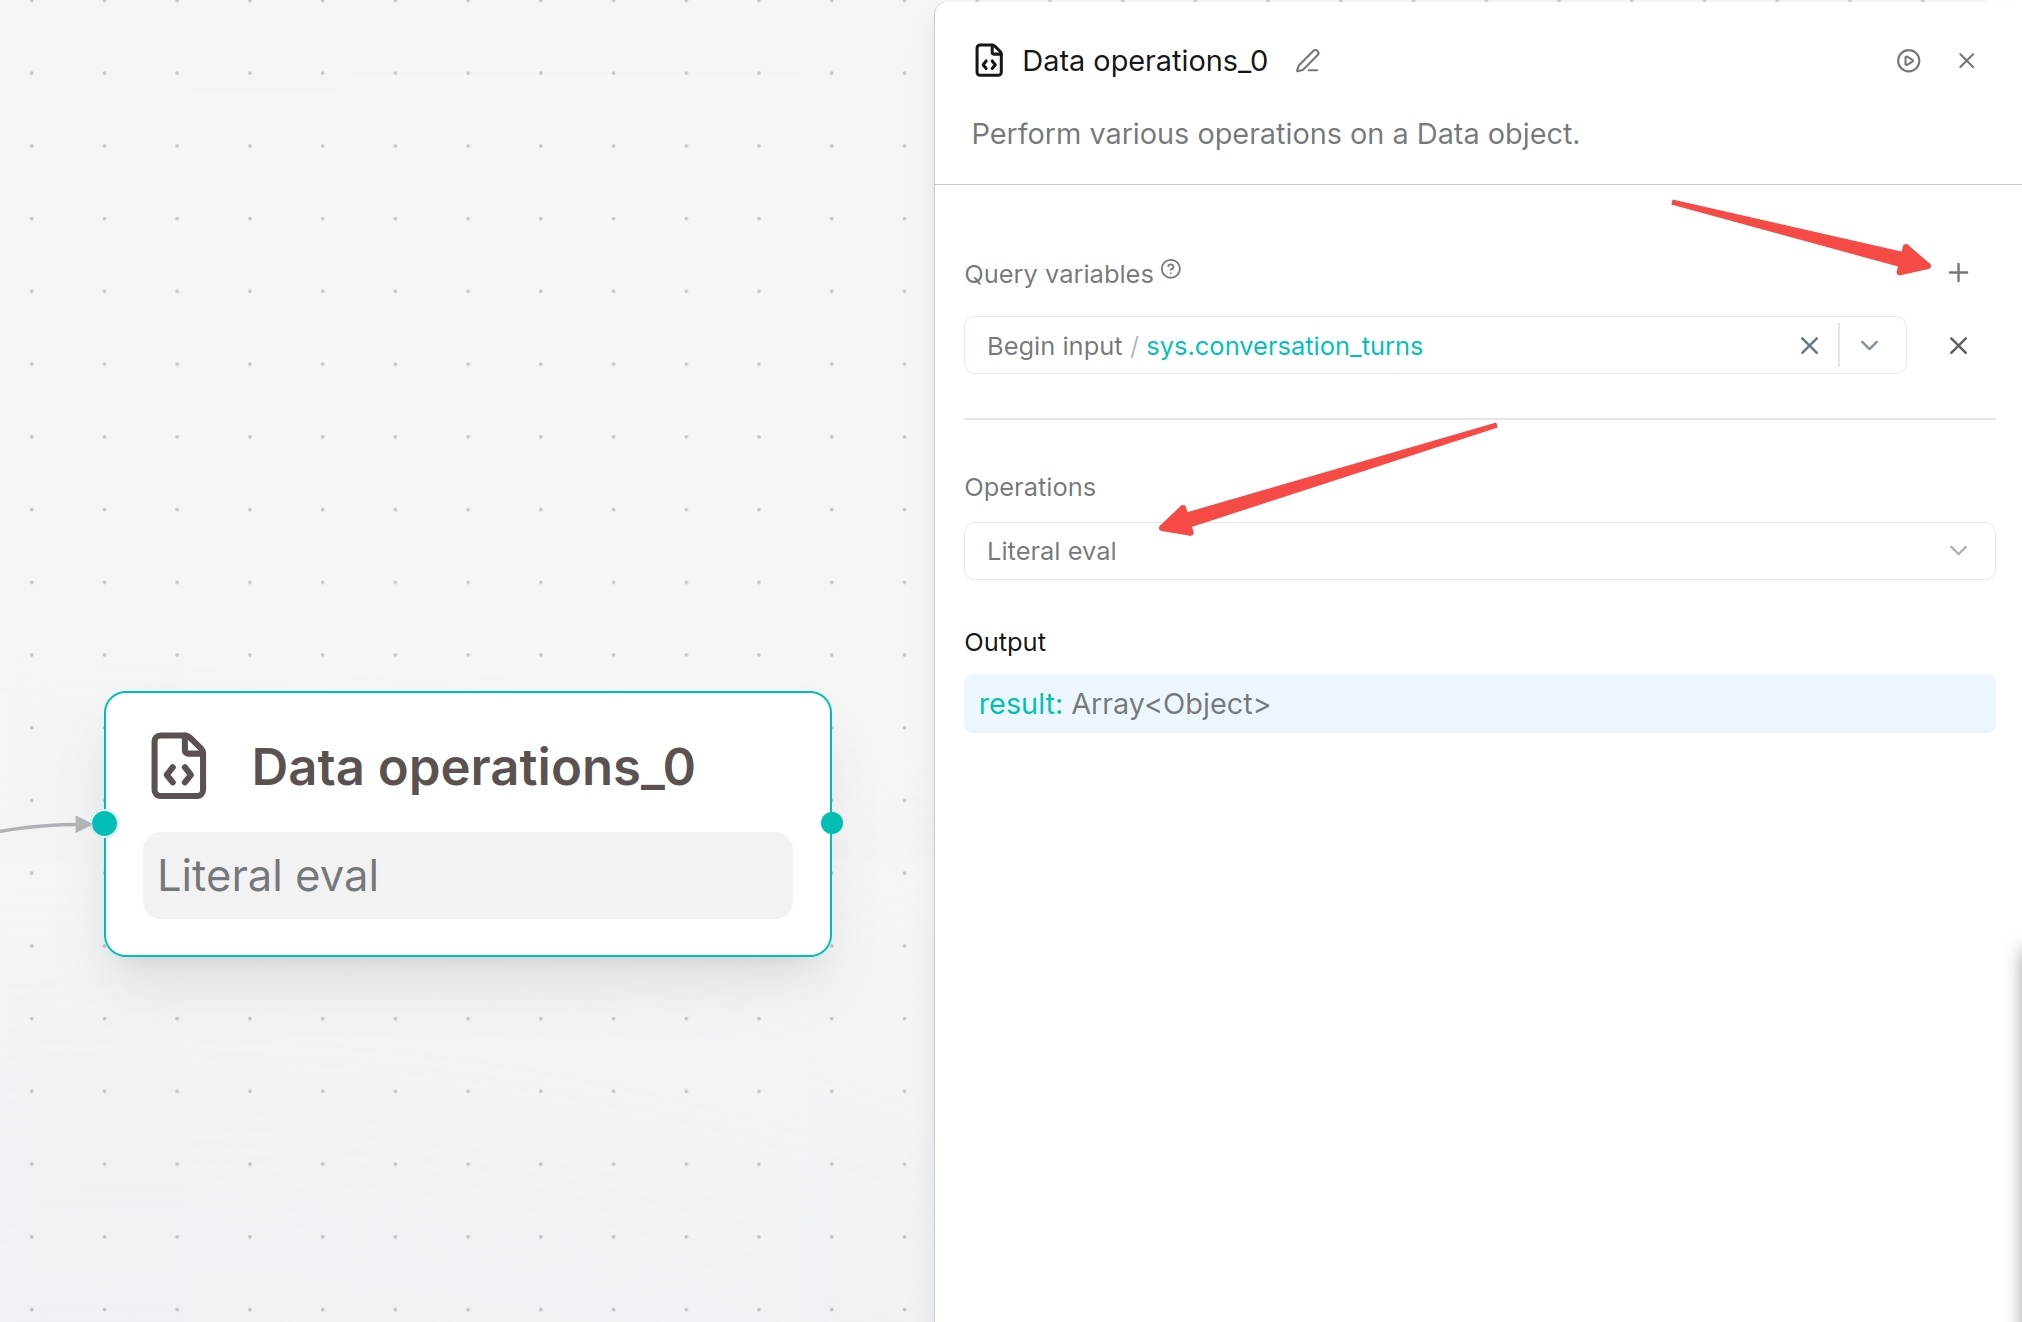
2. Select target data variables in Query variables.
|
||||
3. Click `+` to add multiple input variables. Query variables are mandatory.
|
||||
4. Select an operation under **Operations** and fill in the fields below.
|
||||
5. Click **Save**, then **Run** to check the result.
|
||||
5. Click **Save draft**, then **Run** to check the result.
|
||||
|
||||
|
||||
|
||||
|
||||
@@ -0,0 +1,56 @@
|
||||
---
|
||||
sidebar_position: 3
|
||||
title: Create and Manage Workflows
|
||||
sidebar_label: Create and Manage Workflows
|
||||
slug: /creation_and_management
|
||||
sidebar_custom_props: {
|
||||
categoryIcon: RagAiAgent
|
||||
}
|
||||
---
|
||||
|
||||
# Create and Manage Workflows
|
||||
|
||||
## Open the Workflow List
|
||||
|
||||
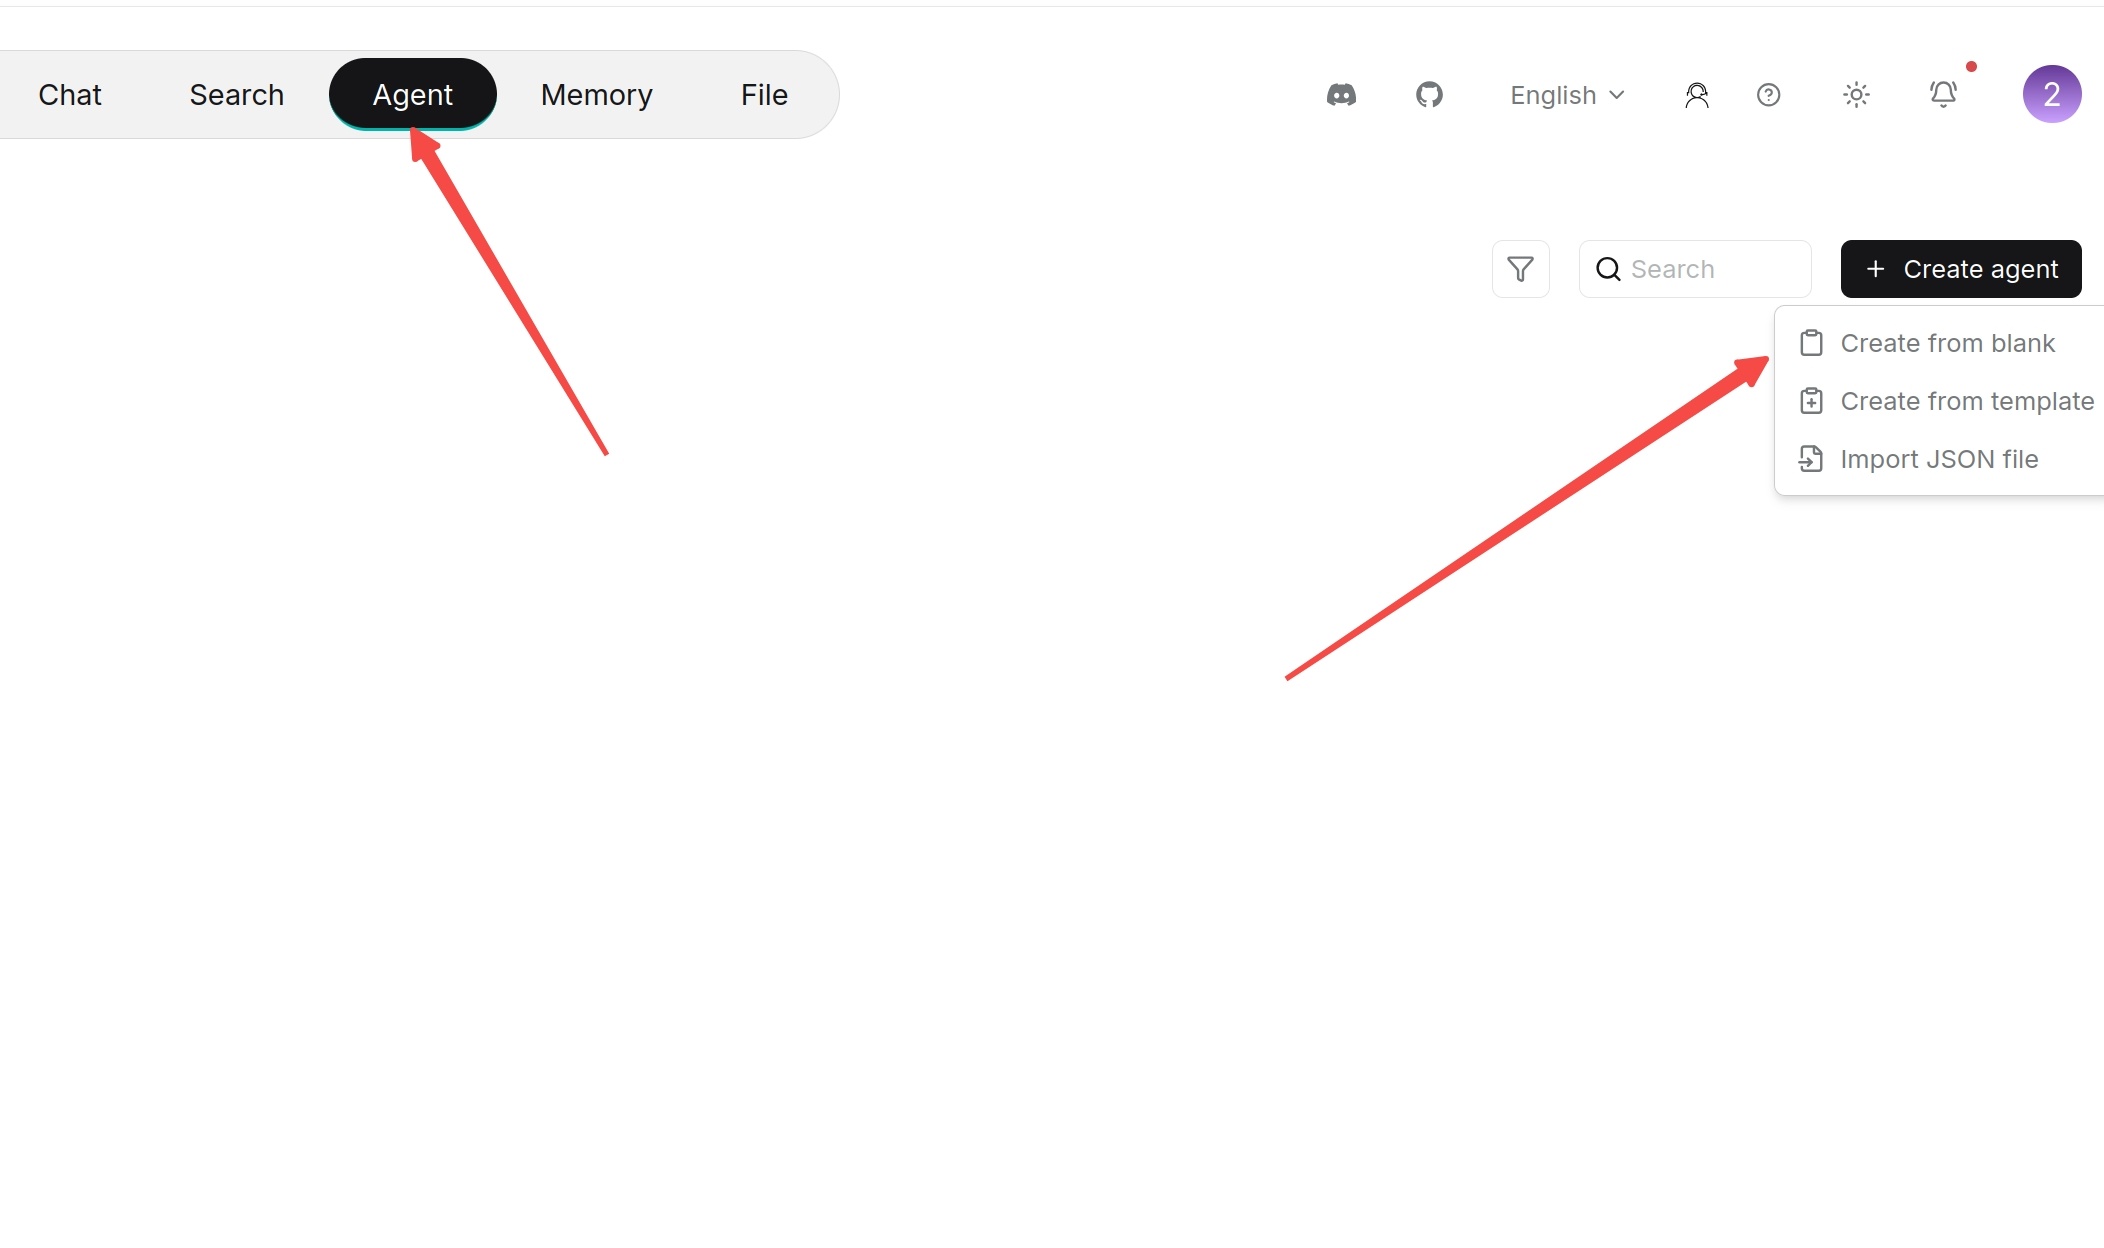
Click **Agent** in the top navigation bar, then select **Workflow**. Each card represents a workflow. Click a card to open its canvas and continue editing.
|
||||
|
||||
Select the category before creating an application. This chapter covers Workflow. For document processing, see [Create an Ingestion Pipeline](./ingestion_pipeline/create_ingestion_pipeline.md). For compilation templates, see [Knowledge Compilation](../knowledge_compilation/overview.md).
|
||||
|
||||
## Create from Blank Workflow
|
||||
|
||||
1. Open **Agent > Workflow**.
|
||||
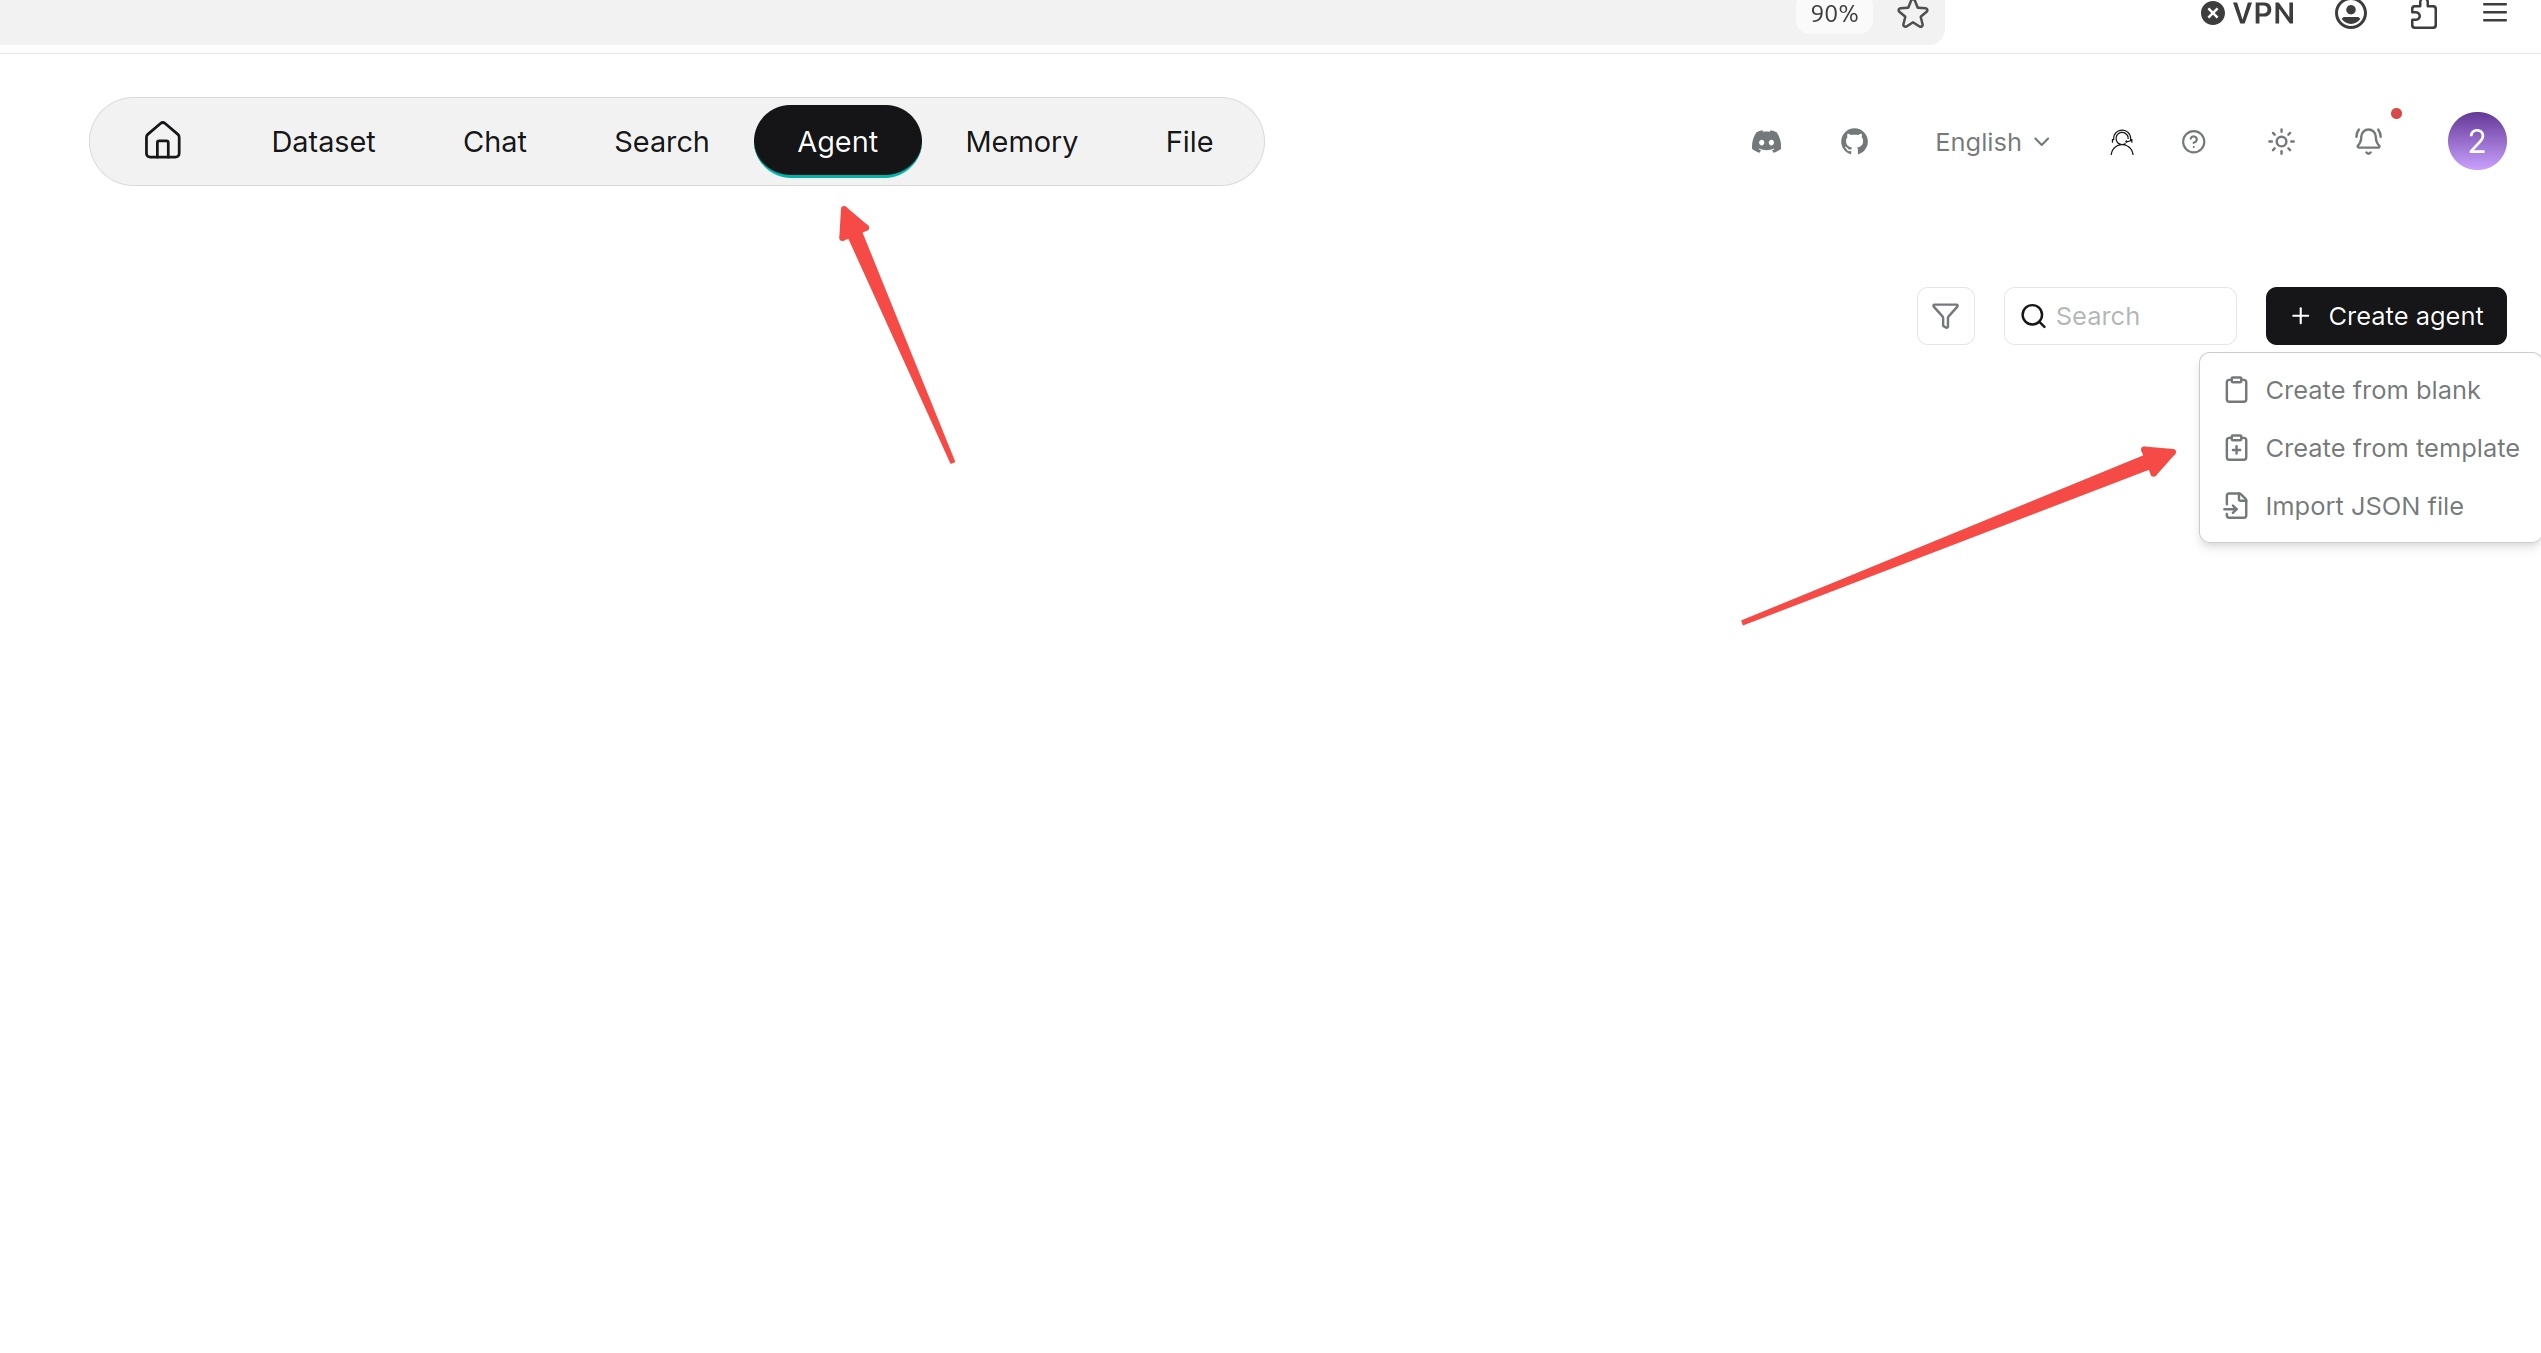
2. Open the **+** creation menu in the upper-right corner and choose **Create from blank**. On an empty list, you can use the **Create from blank** entry directly.
|
||||
|
||||
|
||||
|
||||
3. In **Create workflow**, enter **Name** and click **Confirm**.
|
||||
4. Open the workflow card. A blank workflow starts with **Begin**.
|
||||
5. Click **Begin** to configure its mode and inputs. Use its outgoing connection point to add the next component, then configure the component in the panel on the right.
|
||||
6. Connect the remaining steps and click **Save draft**. Use **Run** to test the workflow before publishing it.
|
||||
|
||||
Each workflow has one Begin component. Begin is the entry point and cannot be deleted.
|
||||
|
||||
## Create from Template
|
||||
|
||||
Templates provide components and connections for common tasks. Select one that is close to your task, then replace its models, datasets, prompts, and tool settings with resources available to your account.
|
||||
|
||||
1. Open **Agent > Workflow** and choose **Create from template** from the creation menu.
|
||||
|
||||
|
||||
|
||||
2. Browse the template categories and select a suitable template.
|
||||
3. Use the selected template and complete the name and confirmation prompts.
|
||||
4. Open the created workflow and check each component. In particular, reselect models, datasets, and tools that the template requires.
|
||||
5. Click **Save draft**, then **Run** and test with representative inputs.
|
||||
|
||||
## Search, Copy and Delete Workflow
|
||||
|
||||
- **Search**: Enter the workflow name in the list's search box.
|
||||
- **Copy**: Open the workflow, select **Management > Export**, then [import the JSON](./import_and_export_workflows.md#import-workflow) with a different name.
|
||||
- **Delete**: Open the card's **…** menu, select **Delete**, and complete the confirmation. Export a copy first if you need to keep the configuration.
|
||||
|
||||
## Save, Test and Publish
|
||||
|
||||
The canvas displays the latest **Autosaved** time. **Save draft** saves your current editing configuration; it does not create a published version. Use **Run** to check the workflow, then **Publish** when the configuration is ready for use.
|
||||
|
||||
See [Canvas Toolbar](./understand_workflow_canvas.md#canvas-toolbar) for the purpose of each upper-right button, publishing steps, and the entries in **Management**.
|
||||
@@ -1,81 +0,0 @@
|
||||
---
|
||||
sidebar_position: 3
|
||||
title: Creation and Management
|
||||
sidebar_label: Creation and Management
|
||||
slug: /creation_and_management
|
||||
sidebar_custom_props: {
|
||||
categoryIcon: RagAiAgent
|
||||
}
|
||||
---
|
||||
|
||||
# Creation and Management
|
||||
|
||||
## Access Agent Page
|
||||
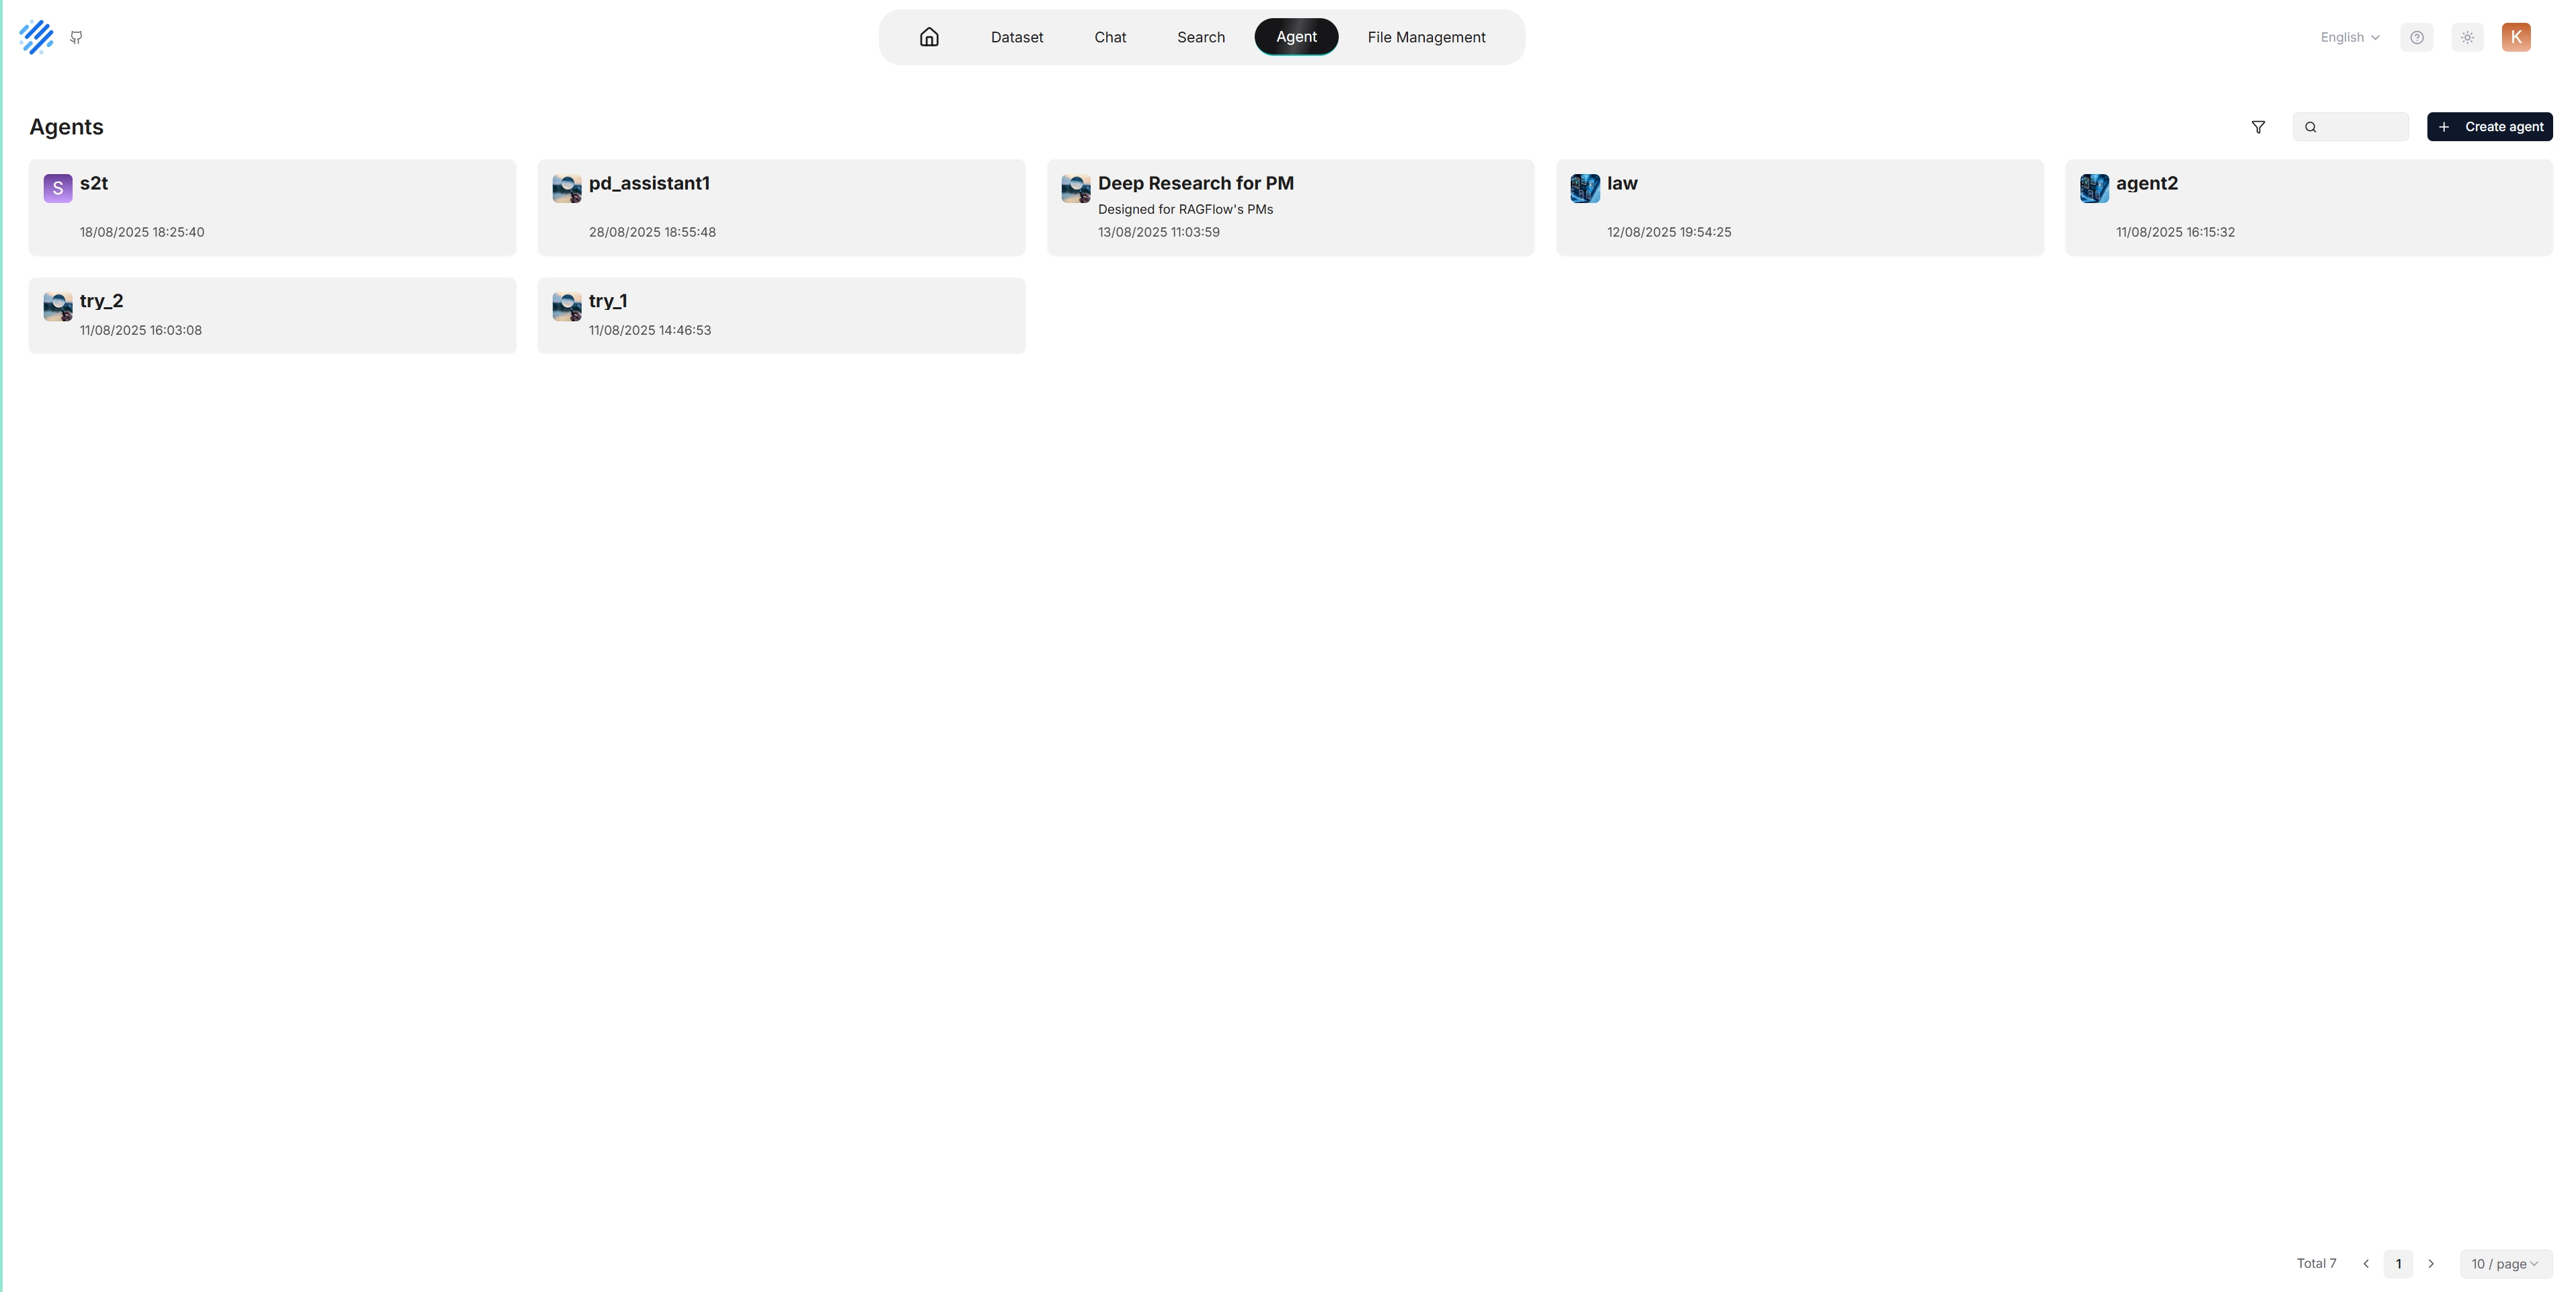
After logging into RAGFlow, click **Agent** in the top navigation bar to enter the Agent page. Created Agents are displayed as cards. Click an existing card to continue editing; click the creation entry to create a new Agent.
|
||||
|
||||
|
||||
|
||||
## Create from Template
|
||||
RAGFlow provides Agent templates for different business scenarios. When creating from a template, the system presets common components and connections. Users only need to modify models, knowledge bases, prompts, interface addresses or output content.
|
||||
|
||||
Steps:
|
||||
1. Enter the Agent page.
|
||||
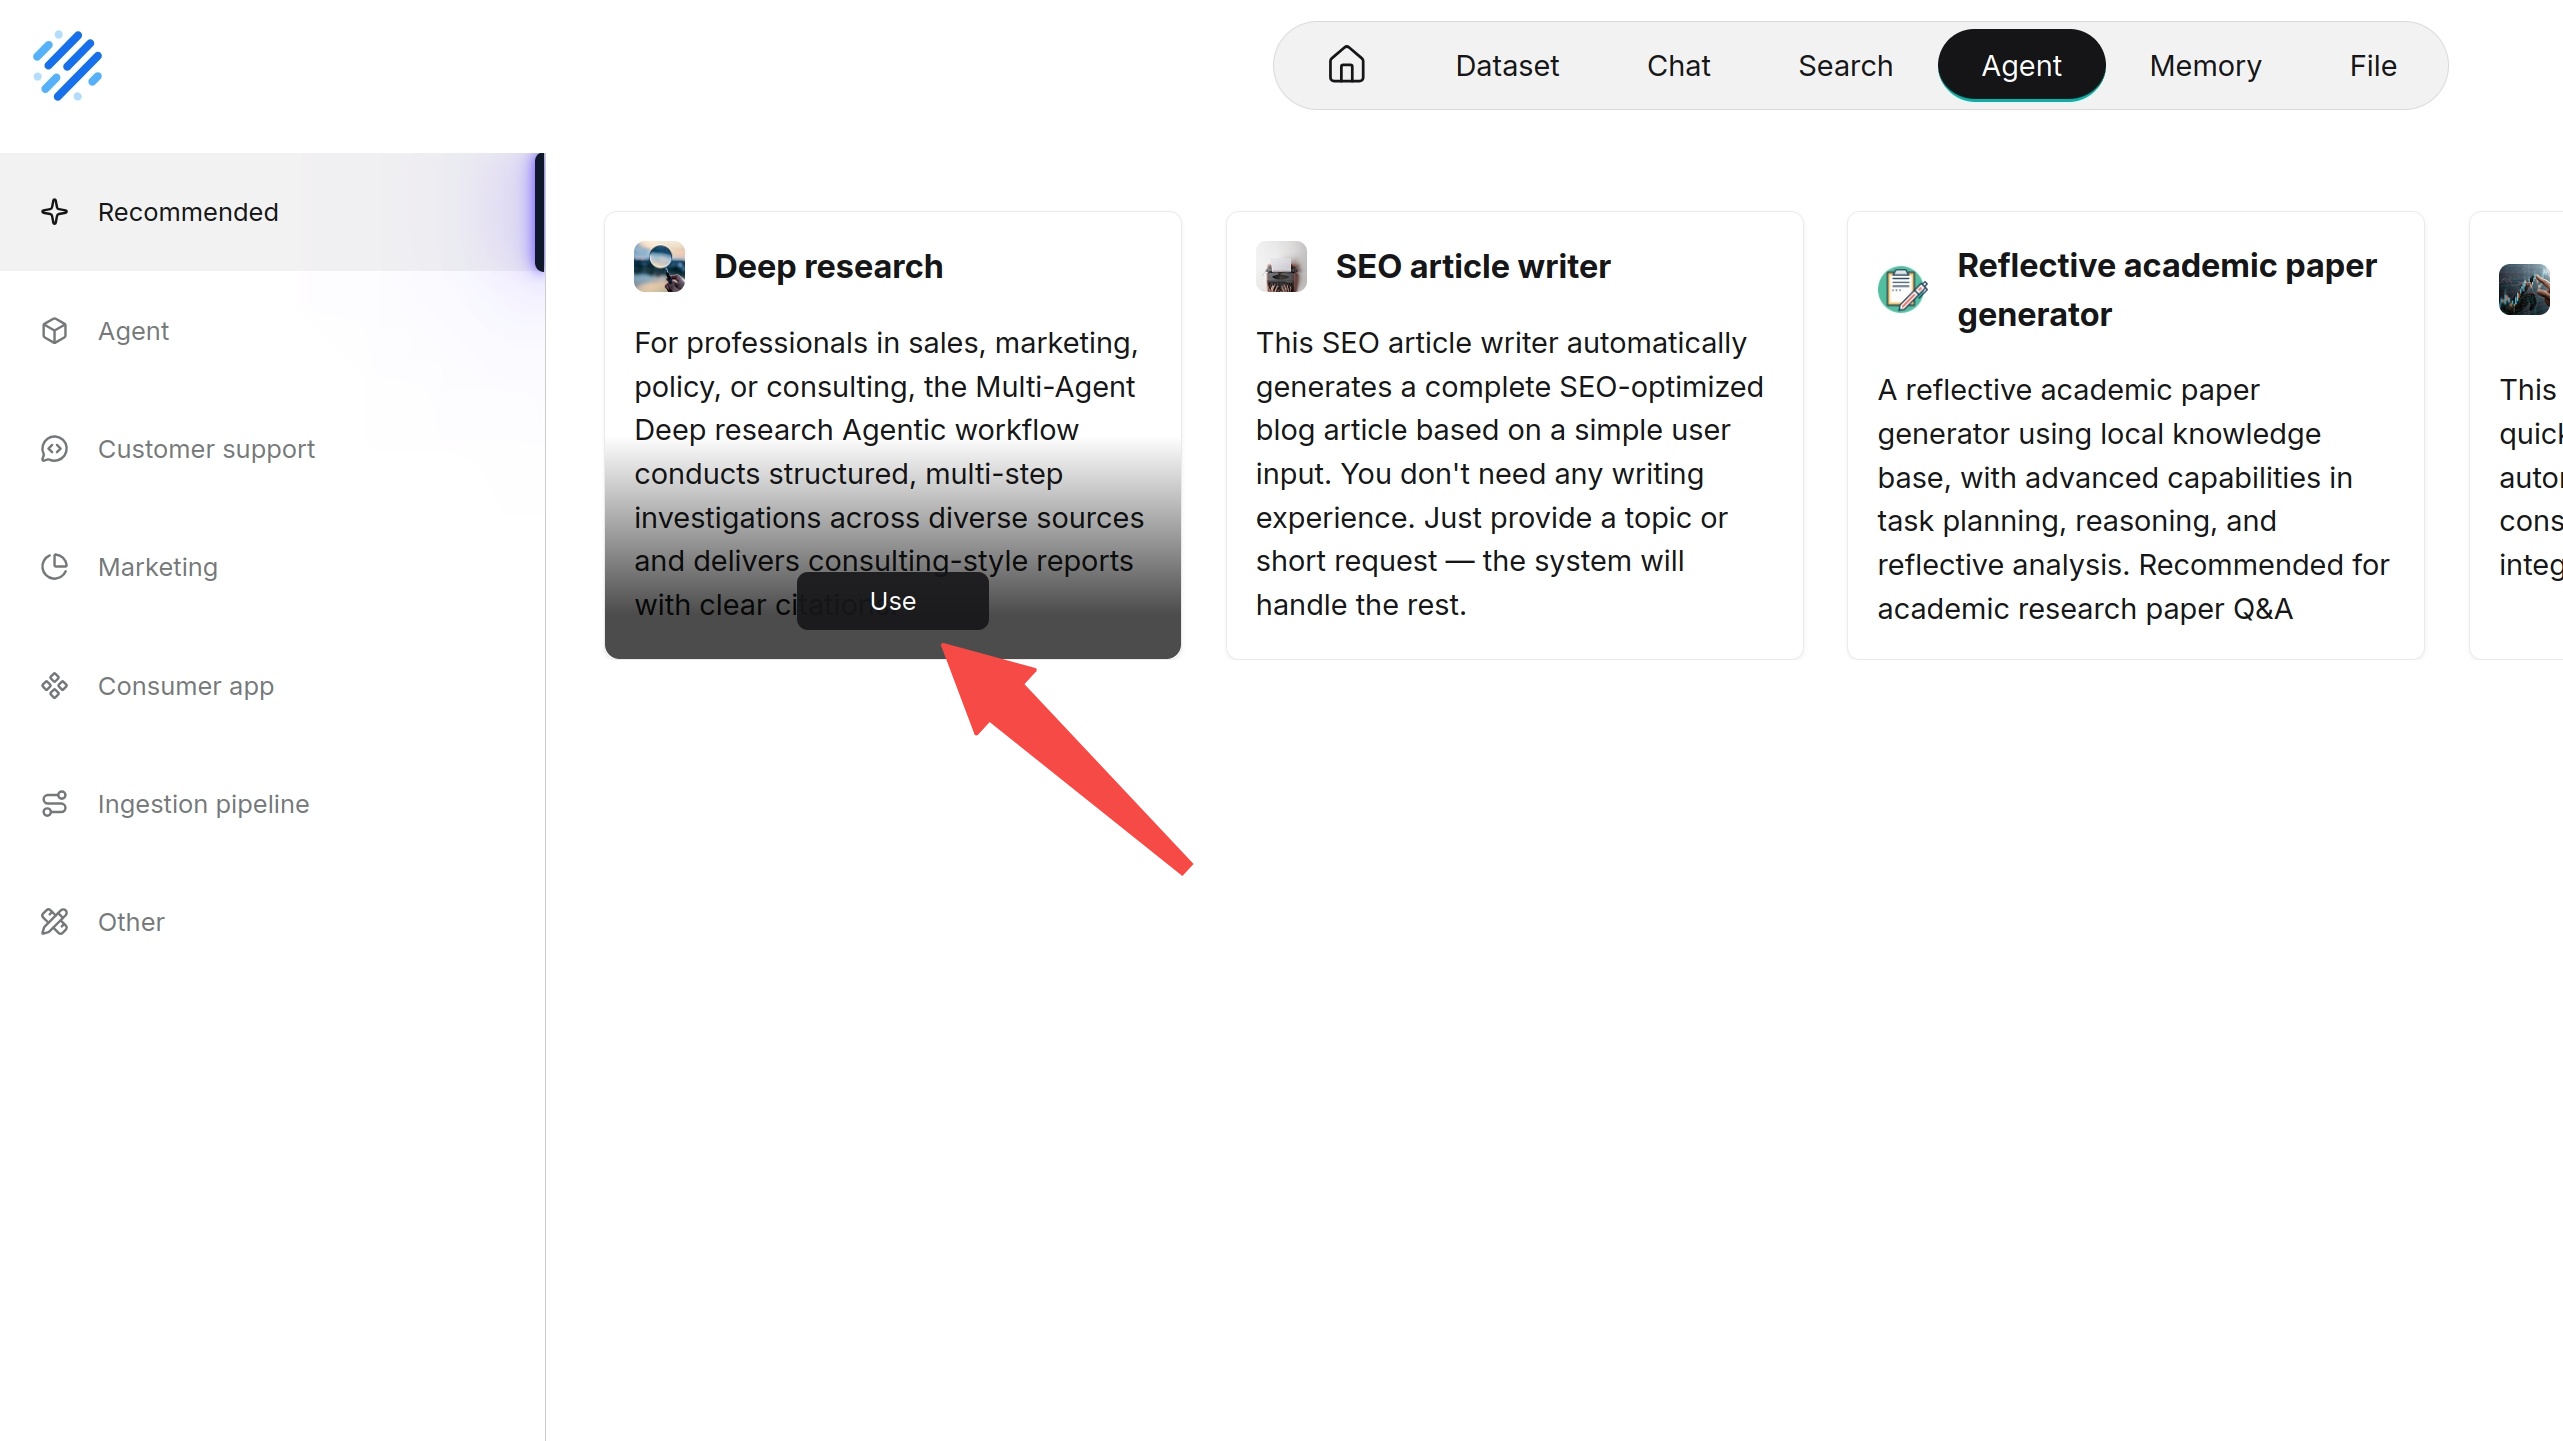
2. Open **Create agent > Create from template**.
|
||||
|
||||

|
||||
3. Select an appropriate template on the template page, such as Deep Research, Knowledge Base Q&A, Data Analysis or E-commerce Customer Service template.
|
||||
|
||||
|
||||
4. Enter the Agent name.
|
||||
5. Confirm the creation.
|
||||
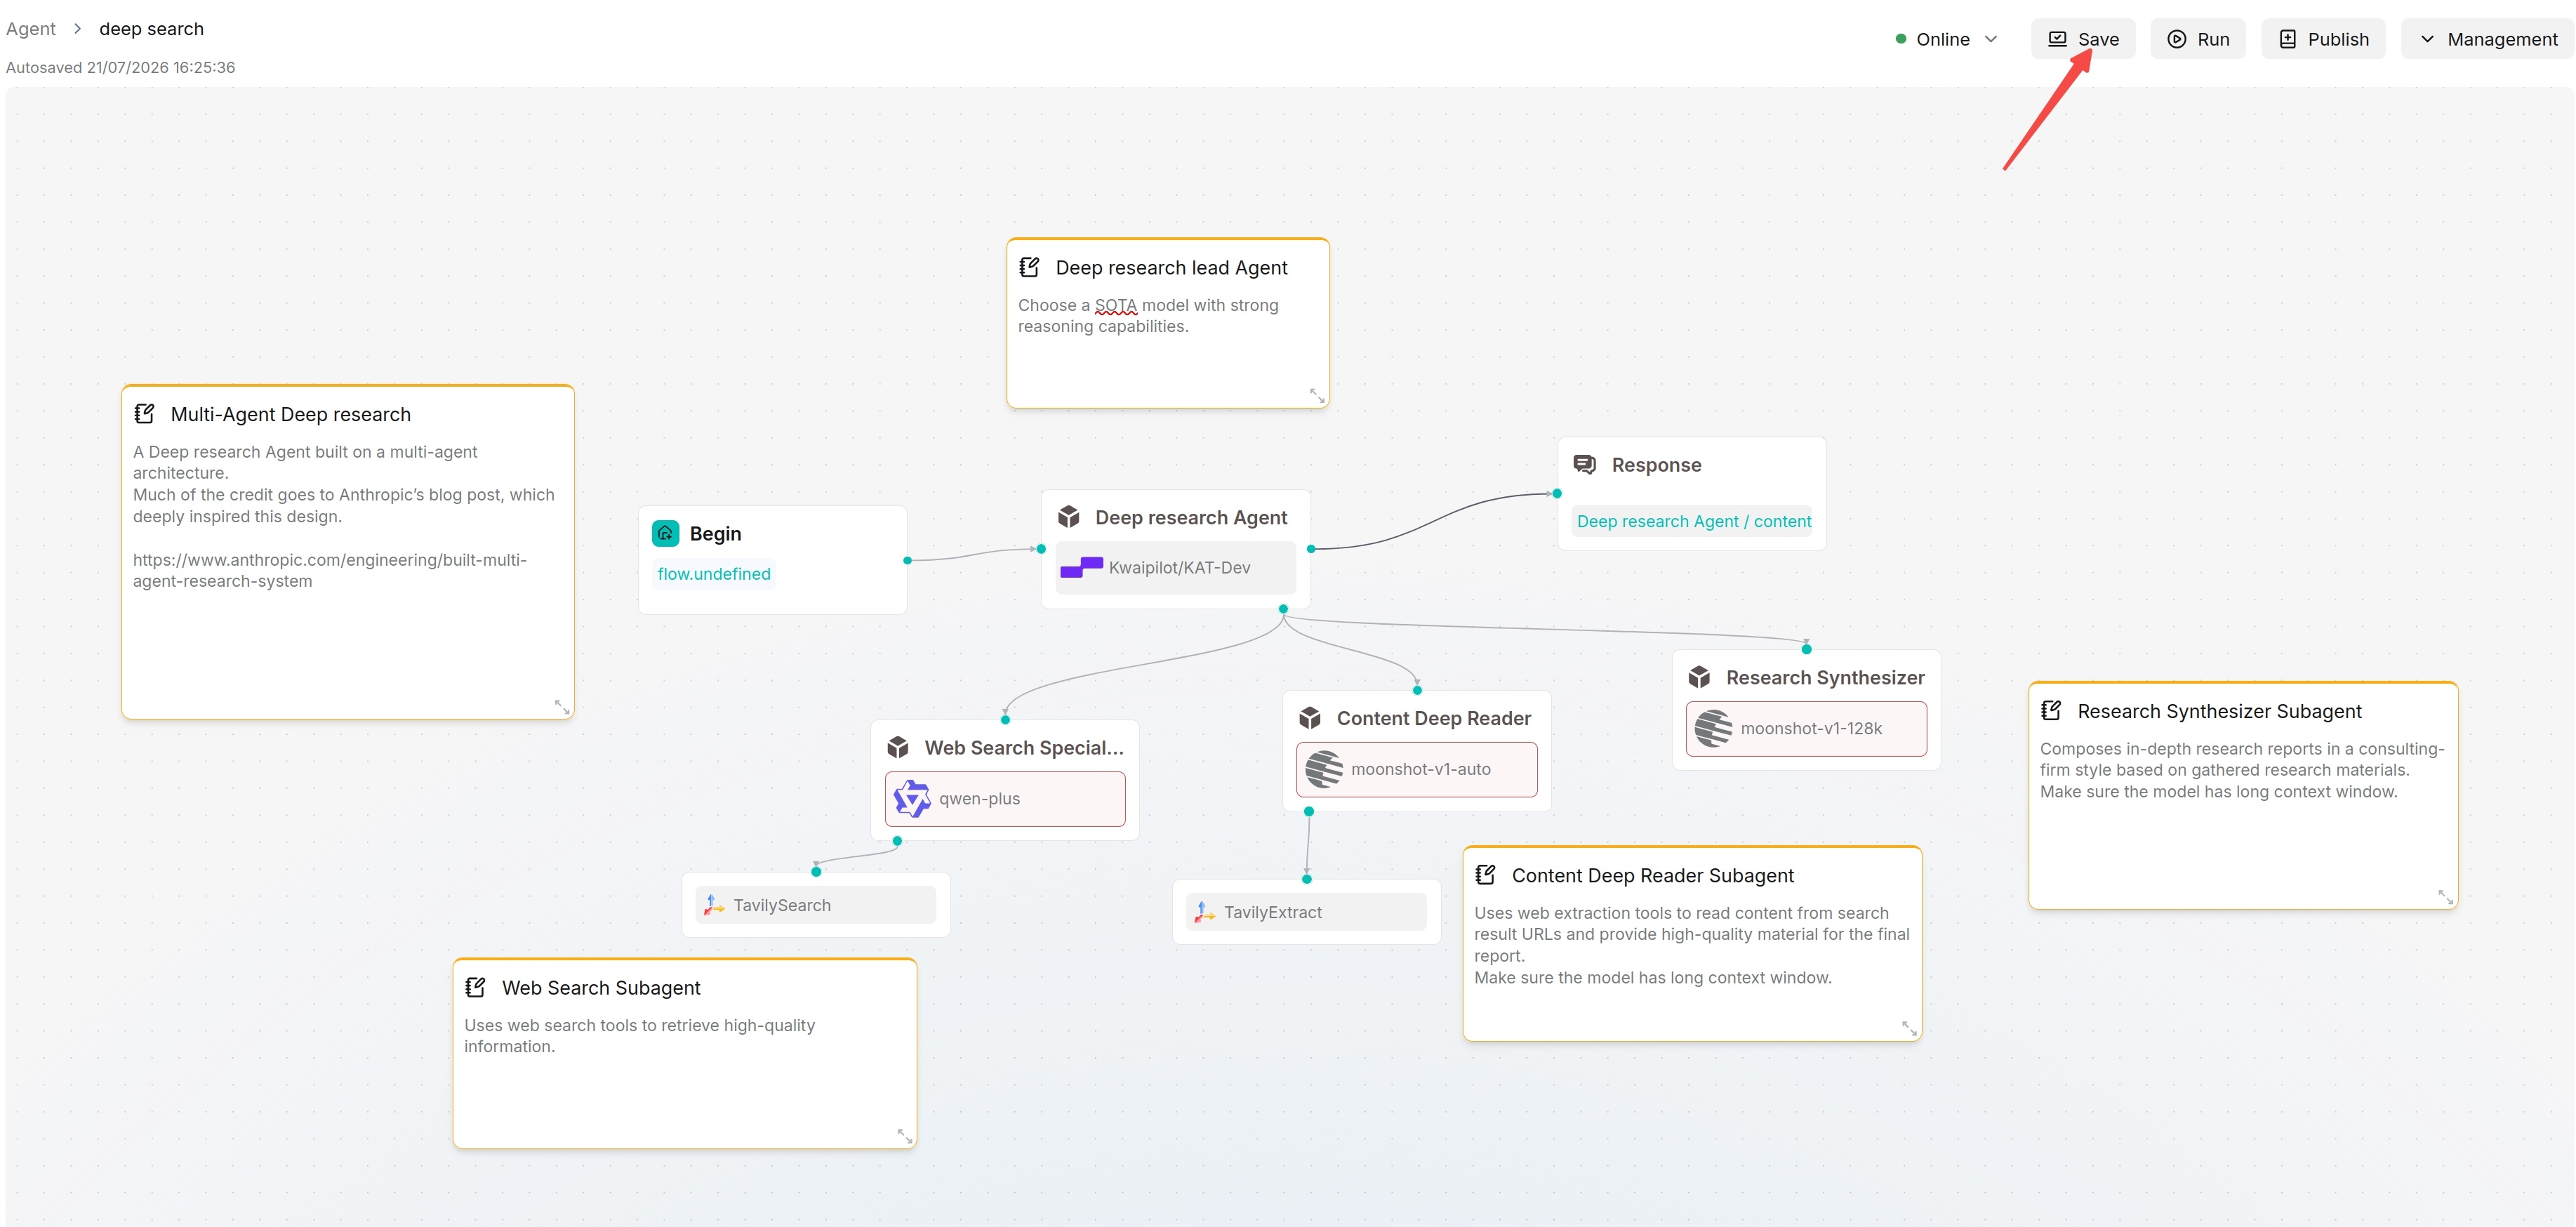
6. After entering the canvas, check the configuration of each component and save.
|
||||
|
||||
|
||||
## Create from Blank Agent
|
||||
A blank Workflow starts with **Begin**. Use a component's outgoing connection point to add downstream components. An Ingestion pipeline starts with **Begin → Parser**; see [Create an Ingestion Pipeline](./ingestion_pipeline/create_ingestion_pipeline.md) for its setup.
|
||||
|
||||
Steps:
|
||||
1. Enter the Agent page.
|
||||
2. Open **Create agent**.
|
||||
3. Select **Create from blank**.
|
||||
|
||||

|
||||
4. Select **Workflow**, **Ingestion pipeline**, or **Compilation operator**, enter **Name**, and click **Confirm**. Choose Workflow for a conversational Agent.
|
||||
5. Open the created card to enter its canvas. For **Compilation operator**, configure the template group and model as described in [Configure the Compiler Component](./ingestion_pipeline/understand_core_ingestion_pipeline_components.md#configure-the-compiler-component).
|
||||
6. For a Workflow, click the outgoing connection point on **Begin** and add the next component.
|
||||
|
||||
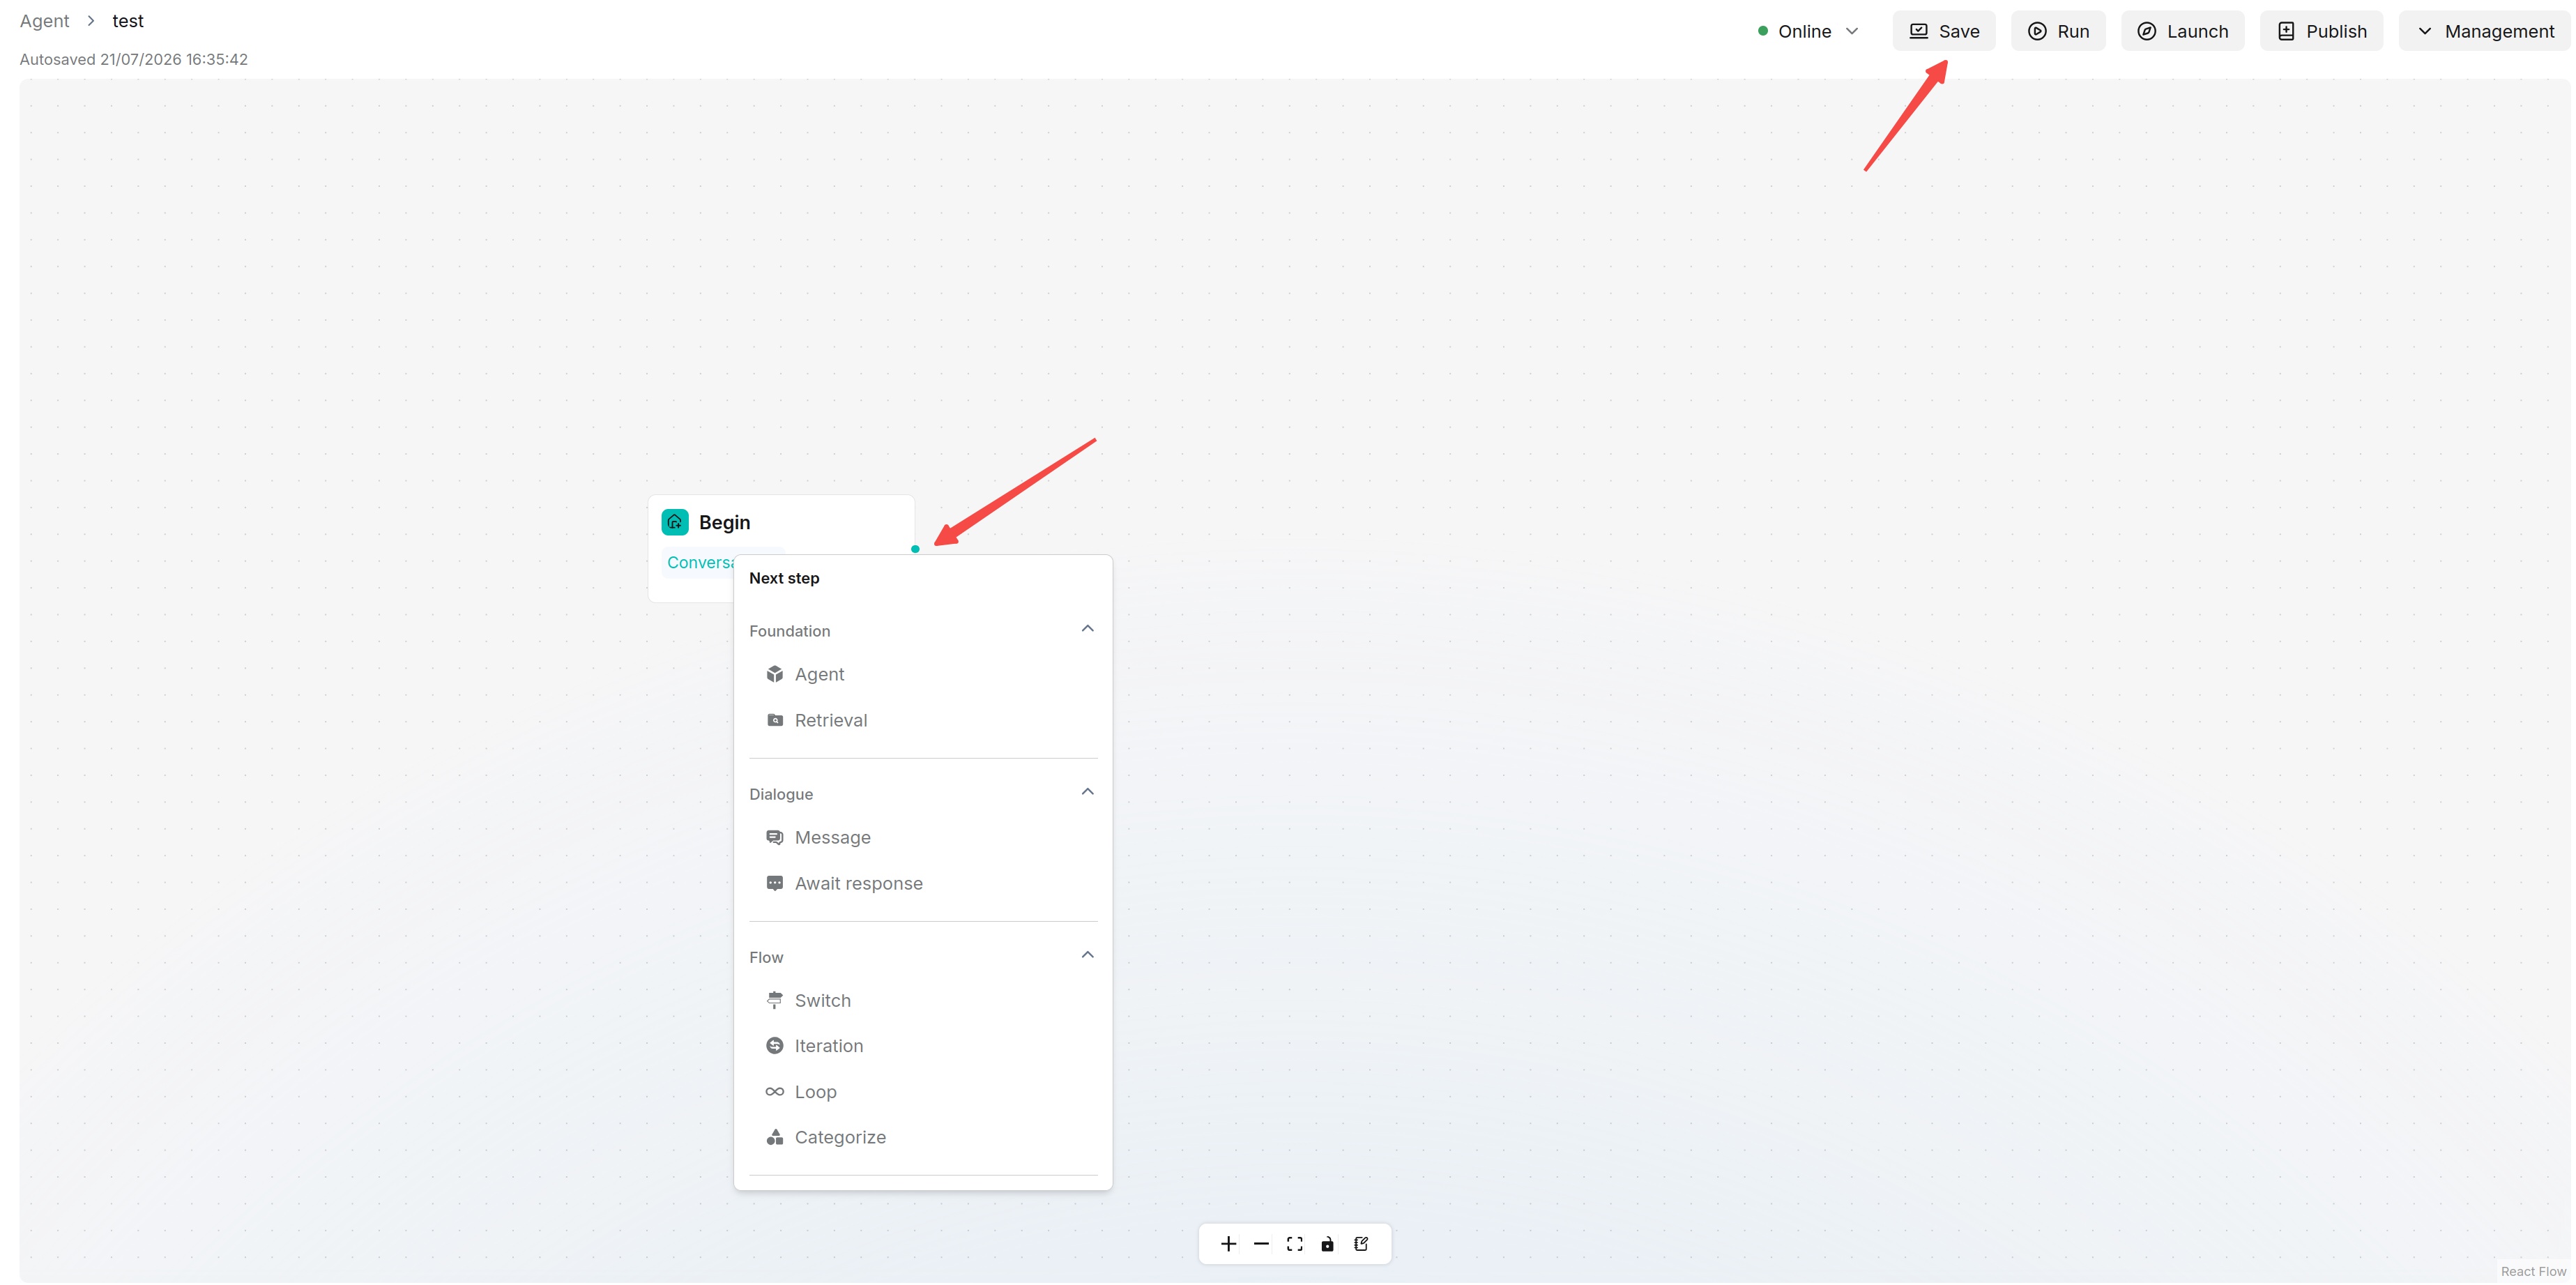
|
||||
7. Configure each component.
|
||||
8. Click **Save**.
|
||||
|
||||
:::tip NOTE
|
||||
The `Begin` component is the start of the workflow. Each Agent can only have one Begin component and it cannot be deleted. After creation, configure Begin first, then configure subsequent components.
|
||||
:::
|
||||
## Search, Copy and Delete Agent
|
||||
- **Search**: Enter the Agent name in the list's search box.
|
||||
- **Copy**: Open the Agent, choose **Management > Export**, then [import the JSON](./import_and_export_agents.md#import-agent) with a different name.
|
||||
- **Delete**: Open the card's **…** menu, select **Delete**, and confirm the Agent name. Deletion removes the Agent and its saved versions. Export a copy first if you need to keep its configuration.
|
||||
|
||||
## Save and Publish
|
||||
|
||||
The editor shows the latest autosave time.
|
||||
|
||||
- **Save**: Save the editing configuration.
|
||||
- **Run**: Test the workflow in the editor.
|
||||
- **Launch**: Open the conversation page in Conversational mode.
|
||||
- **Publish**: Create a published version after checking the test results.
|
||||
|
||||
## Management
|
||||
|
||||
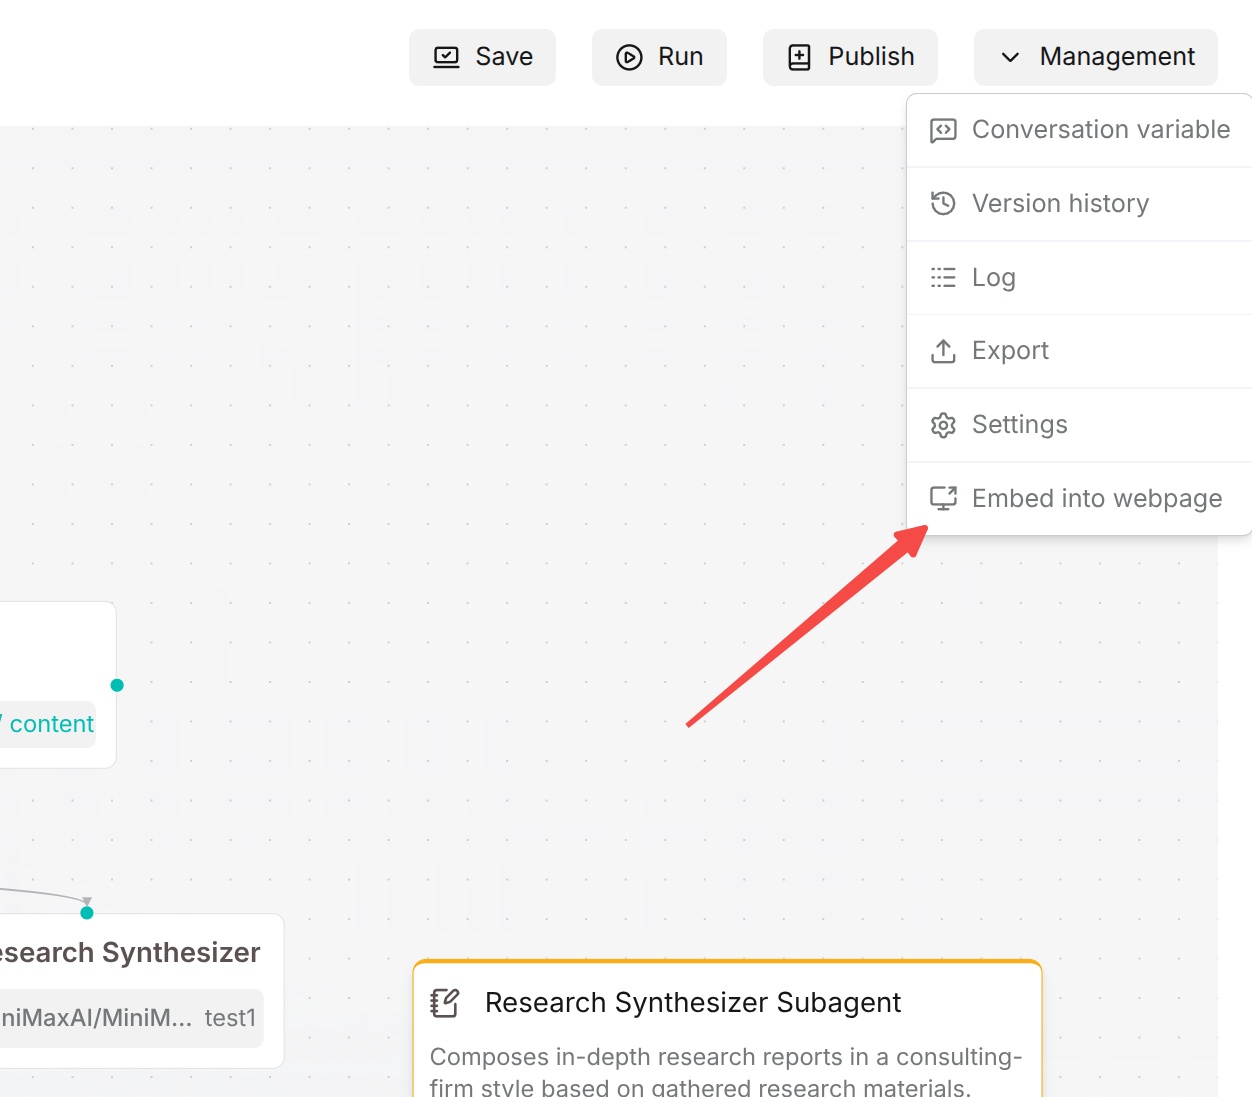
The Workflow canvas provides these entries under **Management**:
|
||||
|
||||
| Entry | Purpose |
|
||||
| --- | --- |
|
||||
| Conversation variable | Configure variables used in a conversation. |
|
||||
| Version history | Browse recorded versions and inspect their canvas configurations. A history entry alone does not indicate a published version. |
|
||||
| Log | Search execution records by **ID/Title** and date. View state, version, and other record details, or use **Export current page**. |
|
||||
| Export | Export the Agent configuration. |
|
||||
| Settings | Open Agent settings. |
|
||||
| Embed into webpage | Open the website embedding options. |
|
||||
|
||||
Available controls differ for other Agent types. Ingestion pipeline creation and validation are covered in the [pipeline guide](./ingestion_pipeline/create_ingestion_pipeline.md).
|
||||
+6
-5
@@ -1,16 +1,16 @@
|
||||
---
|
||||
sidebar_position: 5
|
||||
title: Embed into Web Pages
|
||||
sidebar_label: Embed into Web Pages
|
||||
title: Embed Workflows into Web Pages
|
||||
sidebar_label: Embed Workflows into Web Pages
|
||||
slug: /embed_into_web_pages
|
||||
sidebar_custom_props: {
|
||||
categoryIcon: RagAiAgent
|
||||
}
|
||||
---
|
||||
|
||||
# Embed into Web Pages
|
||||
# Embed Workflows into Web Pages
|
||||
|
||||
## Embed Agent Via Webpage
|
||||
## Embed a Workflow into a Webpage
|
||||
Embed a **Workflow** Agent in a website as a fullscreen chat or floating widget.
|
||||
|
||||
Follow these steps to embed an Agent from a self-managed deployment. Obtain an API key under **User settings > API** before configuring the embed; see [Acquire a RAGFlow API key](../../develop/acquire_ragflow_api_key.md).
|
||||
@@ -19,7 +19,8 @@ Steps:
|
||||
1. On the Agent page, click the target Agent to open its editing page.
|
||||
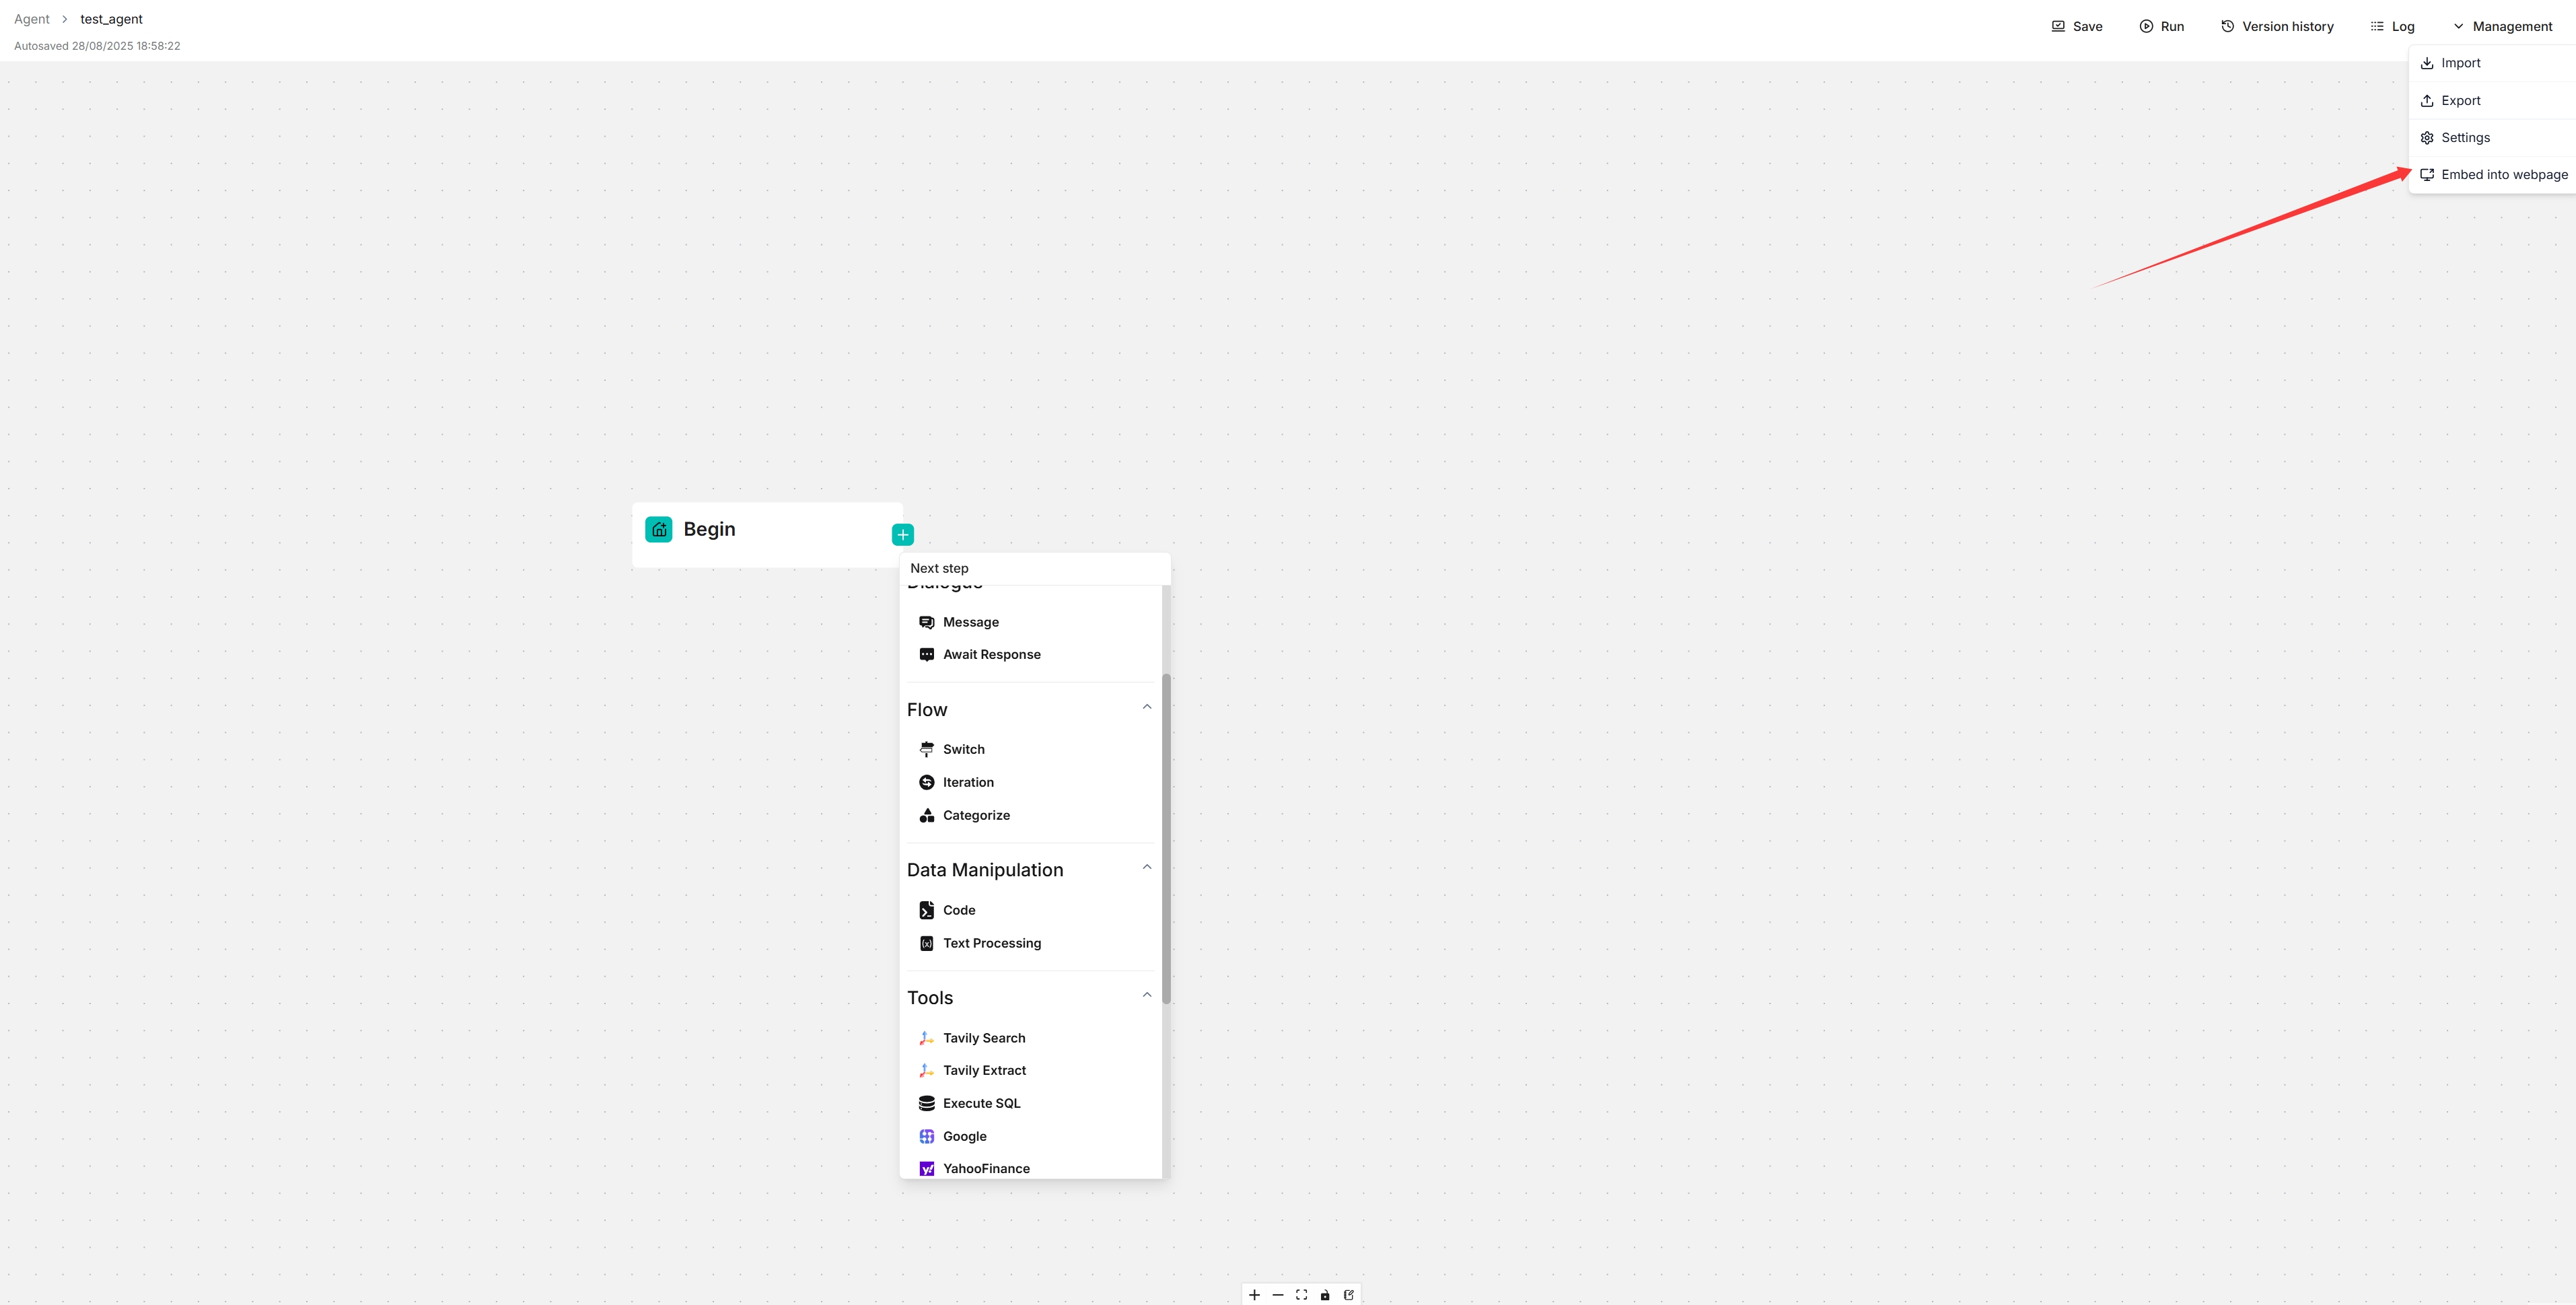
2. Click **Management > Embed into webpage** in the upper right corner of the canvas to open the embedding settings.
|
||||
|
||||
|
||||
|
||||
|
||||
3. In **Embed Setup**, choose **Fullscreen chat (traditional iframe)** or **Floating widget (Intercom-style)**.
|
||||
4. Set **Language**, **User ID**, and display options as needed. Enable **Published** to use the published version of the Agent.
|
||||
5. For a floating widget, use **Widget Customization** to adjust its title, text, and colors. Click **Save widget settings** to save the settings.
|
||||
@@ -1,32 +0,0 @@
|
||||
---
|
||||
sidebar_position: 4
|
||||
title: Import and Export Agents
|
||||
sidebar_label: Import and Export Agents
|
||||
slug: /import_and_export_agents
|
||||
sidebar_custom_props: {
|
||||
categoryIcon: RagAiAgent
|
||||
}
|
||||
---
|
||||
|
||||
# Import and Export Agents
|
||||
|
||||
## Import Agent
|
||||
|
||||
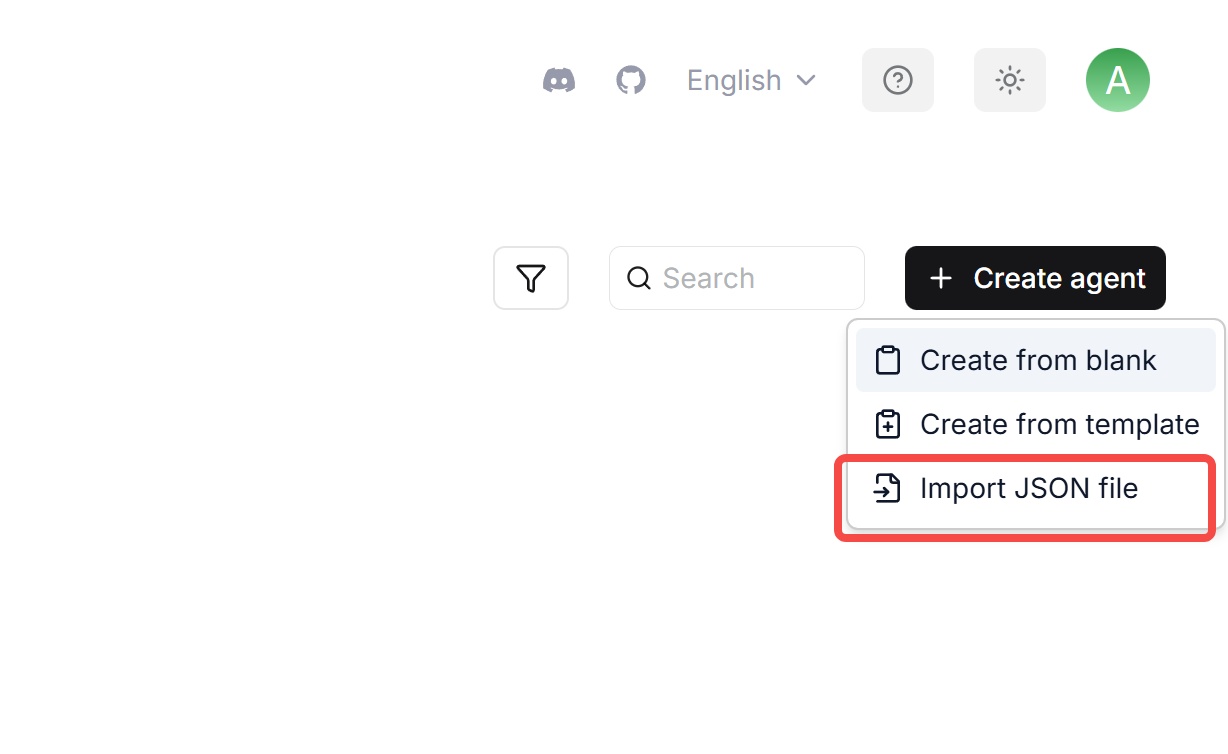
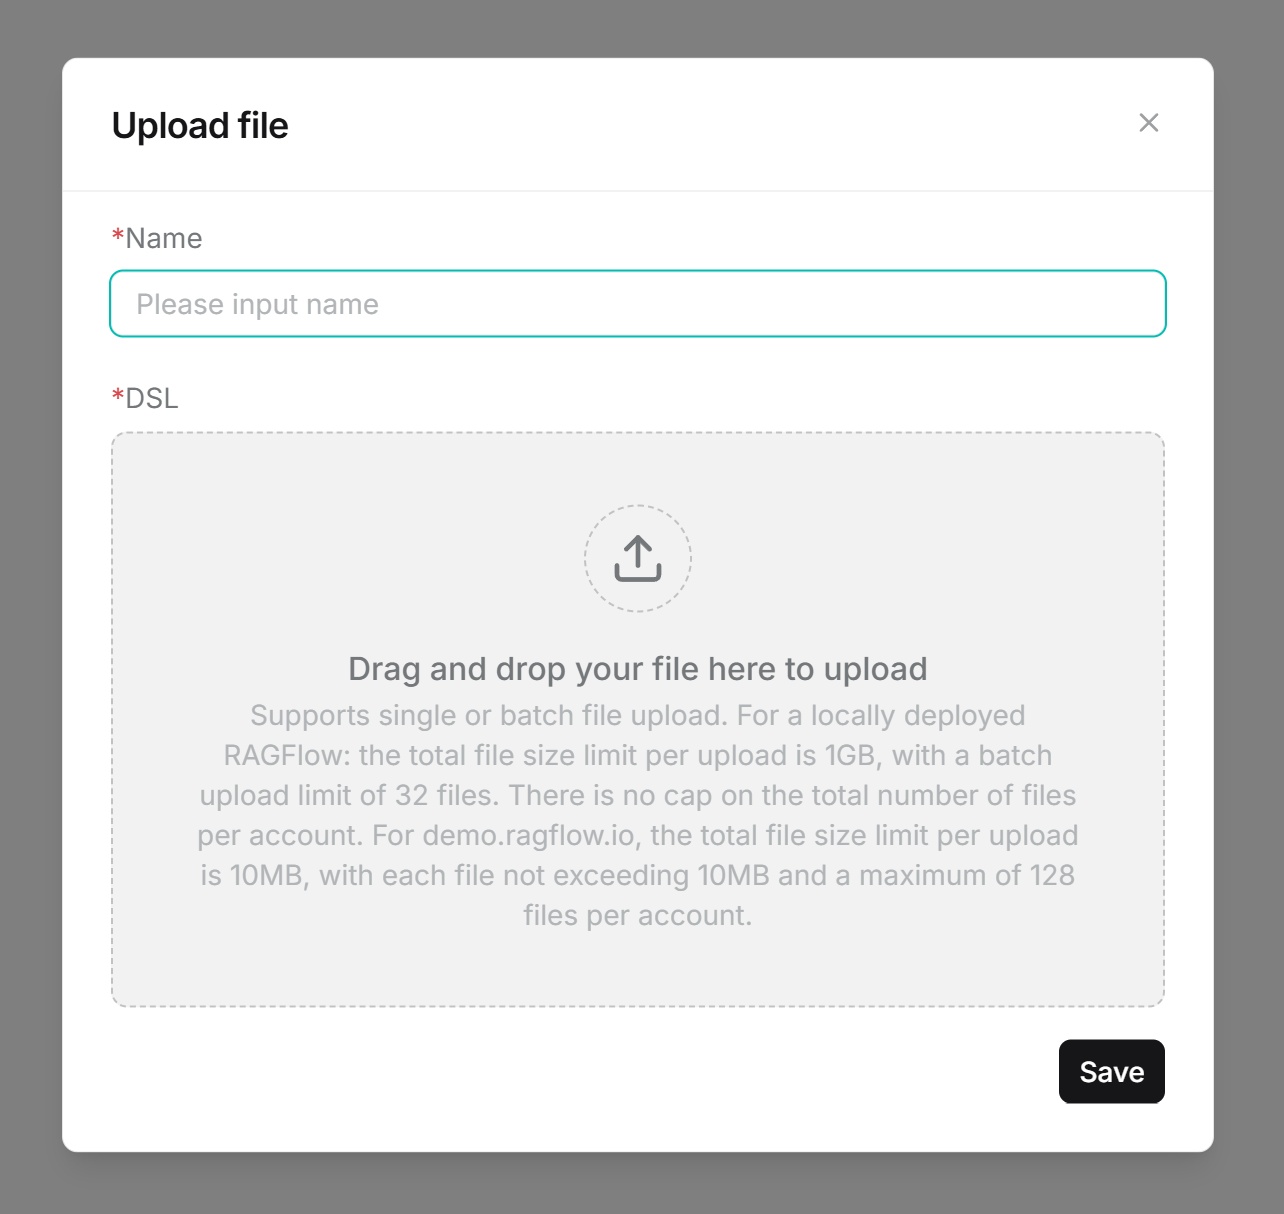
1. On the **Agent** page, open **Create agent > Import JSON file**. On an empty list, click **Import JSON file** directly.
|
||||
2. Enter **Name** and upload one Agent JSON file under **DSL**.
|
||||
3. Click **Save**, then open the imported Agent to check its configuration.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
## Export Agent
|
||||
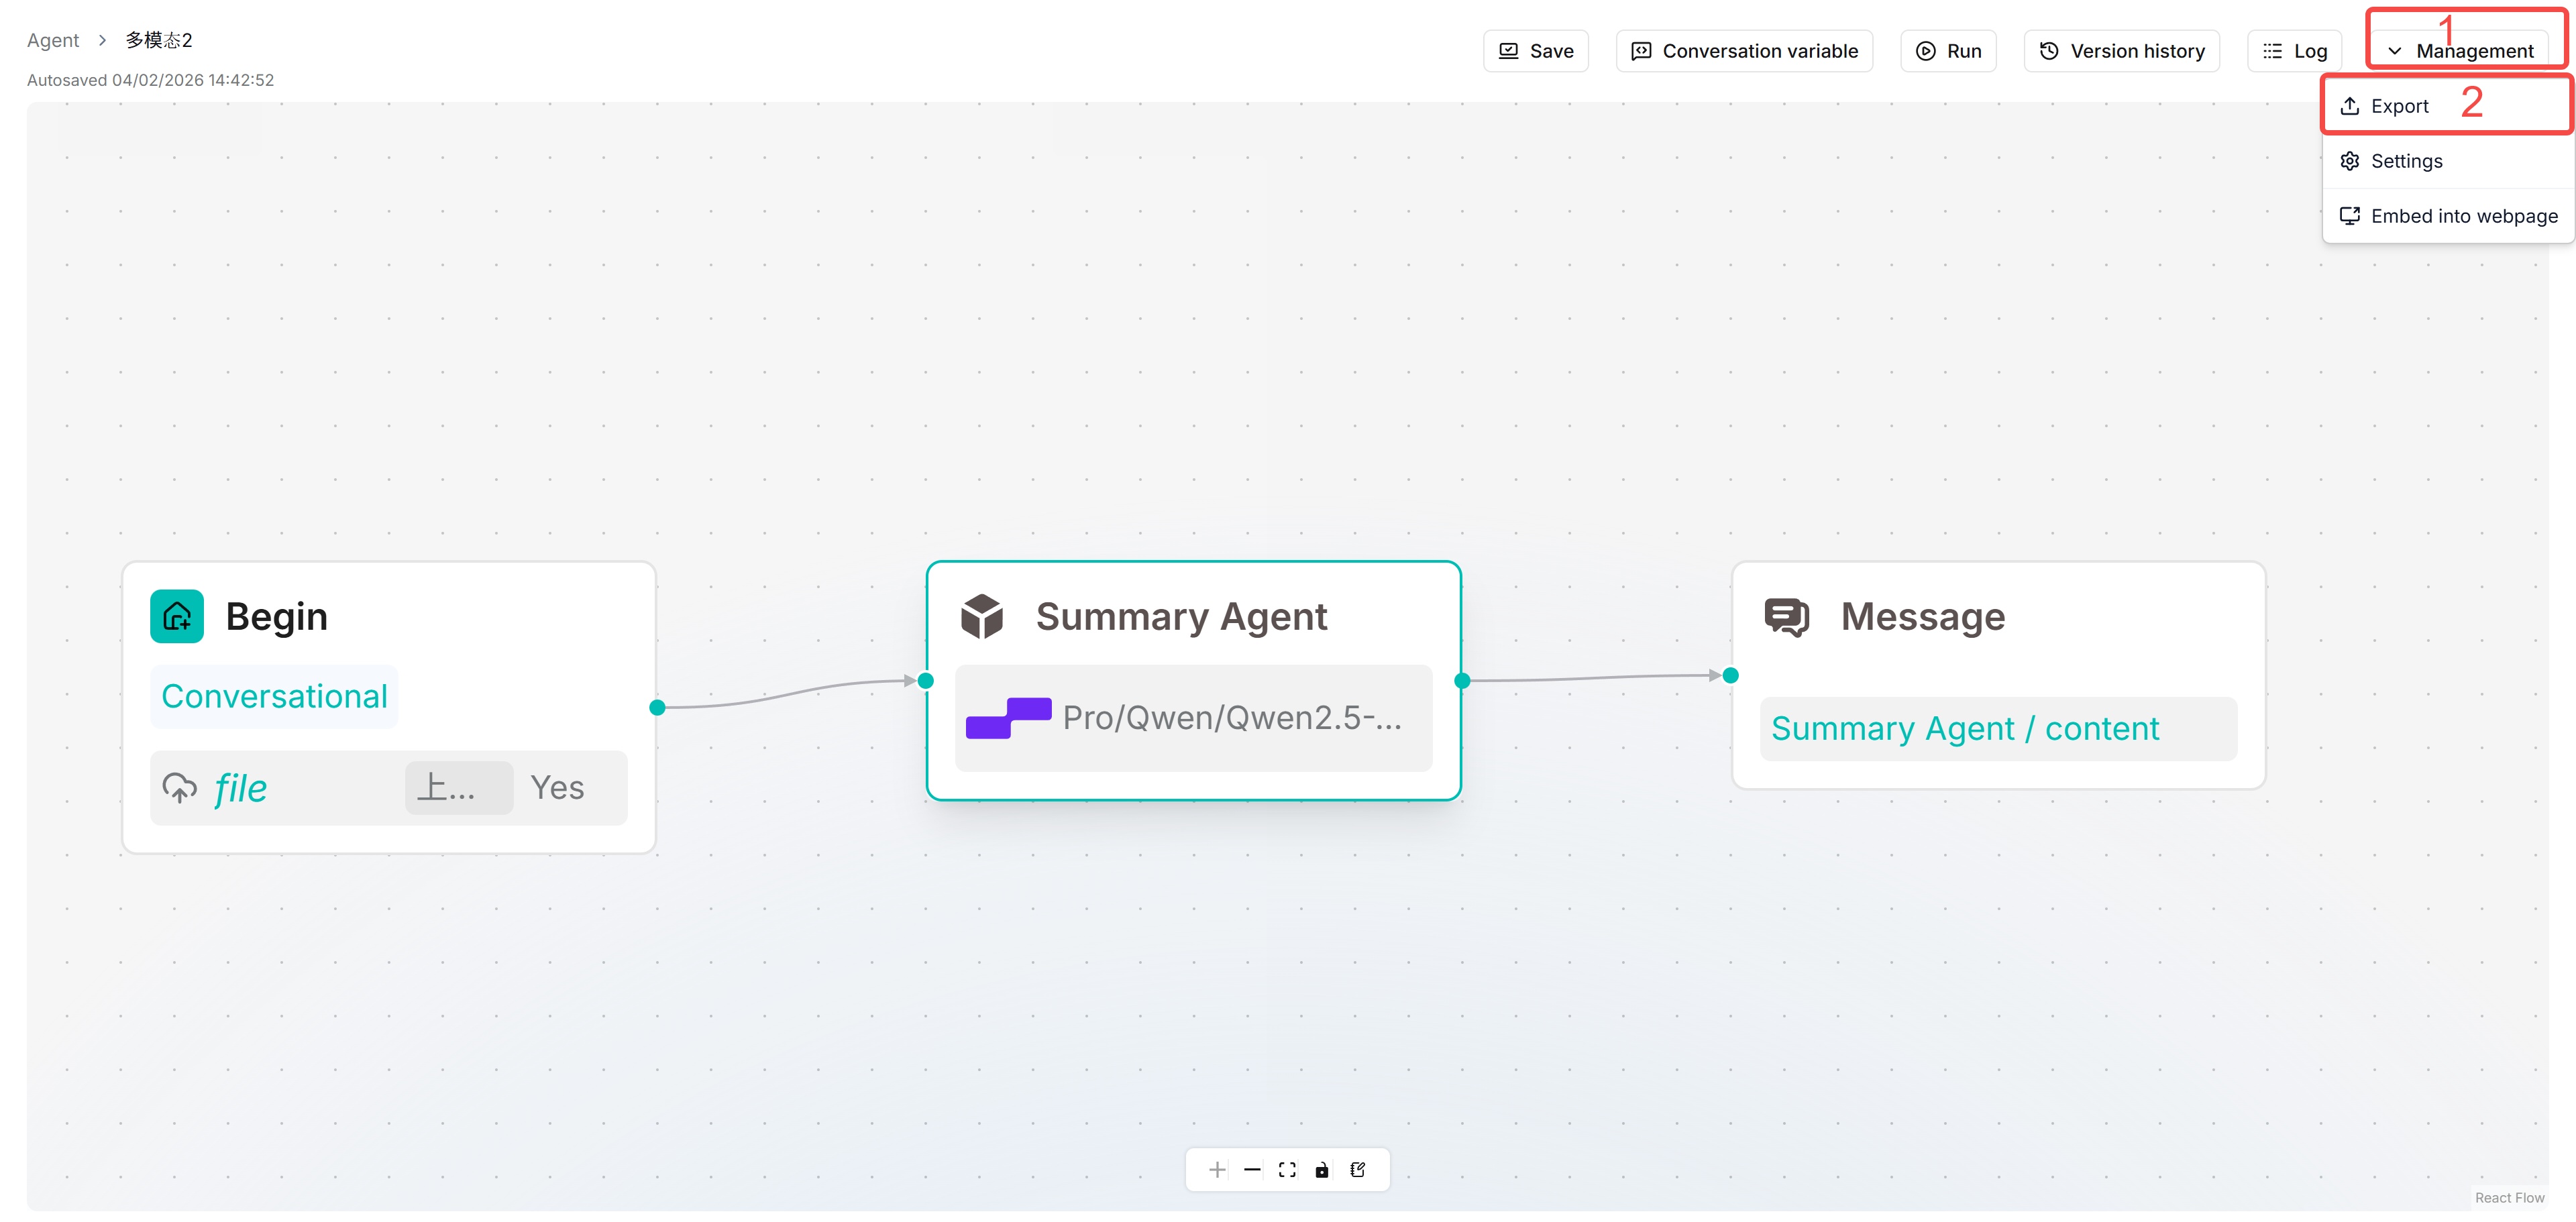
Open an Agent, click **Management** in the upper right corner, then select **Export**.
|
||||
|
||||
|
||||
|
||||
## Check imported dependencies
|
||||
|
||||
After importing, reselect models, datasets, memories, MCP servers, and compilation template groups that are available to the importing account. Importing a JSON configuration does not create or transfer those resources. Check **Checklist**, save, and validate the workflow or pipeline before use.
|
||||
|
||||
The exporter clears API keys for selected tool types. Re-enter the required keys after import. It does not guarantee that every password, token, header, or secret in a configuration has been removed; inspect the exported JSON before sharing it.
|
||||
@@ -0,0 +1,36 @@
|
||||
---
|
||||
sidebar_position: 4
|
||||
title: Import and Export Workflows
|
||||
sidebar_label: Import and Export Workflows
|
||||
slug: /import_and_export_agents
|
||||
sidebar_custom_props: {
|
||||
categoryIcon: RagAiAgent
|
||||
}
|
||||
---
|
||||
|
||||
# Import and Export Workflows
|
||||
|
||||
Use JSON files to back up a workflow configuration or move it to another account or environment. This chapter covers **Workflow**; pipeline import and export are described in the [pipeline manual](./ingestion_pipeline/create_ingestion_pipeline.md#import-and-export-a-pipeline).
|
||||
|
||||
## Import Workflow
|
||||
|
||||
1. Open **Agent** and select **Workflow**.
|
||||
2. Open the creation menu and choose **Import JSON file**. On an empty list, use the **Import JSON file** entry directly.
|
||||
3. Enter **Name** and upload one workflow JSON file under **DSL**.
|
||||
4. Click **Save**, then open the imported workflow card.
|
||||
5. Check its components and [imported dependencies](#check-imported-dependencies), click **Save draft**, and test with **Run** before publishing.
|
||||
|
||||
## Export Workflow
|
||||
|
||||
1. Open **Agent > Workflow** and click the workflow card you want to export.
|
||||
2. Check that the canvas contains the configuration you want to keep. The canvas export uses the current components and connections.
|
||||
3. In the upper-right corner, open **Management > Export**.
|
||||
4. The browser downloads a JSON file named after the workflow. Keep this file as a configuration backup or import it into the target environment.
|
||||
|
||||
The exported file contains the workflow configuration. It does not transfer execution logs, conversation records, or the external resources referenced by the workflow.
|
||||
|
||||
## Check Imported Dependencies
|
||||
|
||||
After importing, reselect models, datasets, memories, and MCP servers that are available to the importing account. Importing a JSON configuration does not create or transfer those resources. If **Checklist** appears, resolve its reported issues, then save and test the workflow before use.
|
||||
|
||||
The exporter clears API keys for selected tool types. Re-enter the required keys after import. It does not guarantee that every password, token, header, or secret in a configuration has been removed; inspect the exported JSON before sharing it.
|
||||
@@ -10,28 +10,31 @@ sidebar_custom_props: {
|
||||
|
||||
# Configure the Chunker Component
|
||||
|
||||
After **Parser**, choose **Token Chunker** or **Title Chunker** through the outgoing connection point. After Token Chunker, add **Transformer** or **Compiler** to enrich the chunks, or **Indexer** to index them.
|
||||
After **Parser**, choose **Token Chunker** or **Title Chunker** through the outgoing connection point. After the Chunker, add **Transformer** or **Compiler** to enrich the chunks, or **Indexer** to index them.
|
||||
|
||||
The custom pipeline's connection menu offers **Token Chunker** and **Title Chunker**. Built-in previews can display other names, such as **Manual Chunker**; those names are not additional choices in the custom pipeline's add menu. A canvas supports one chunking component, so the menu no longer offers another after one has been added.
|
||||
|
||||
## Token Chunker
|
||||
|
||||
Use token-based chunking for text without reliable section structure.
|
||||
Use token-based chunking for text without reliable section structure. Click the node to open its panel, then choose **Delimiters** to configure splitting or **One** to keep the content together. The splitting controls below are shown in Delimiters mode; One hides them.
|
||||
|
||||
| Setting | Description |
|
||||
| --- | --- |
|
||||
| Delimiters / One | Choose delimiter-based splitting or keep the content as one chunk. |
|
||||
| Recommended chunk size | Target chunk length in tokens. Defaults to `512` in Delimiters mode. |
|
||||
| Overlapped percent (%) | Adds overlapping text between adjacent chunks. Defaults to `0`. |
|
||||
| Recommended chunk size | Target chunk length in tokens. Defaults to `512`; the control supports `1`–`2048`. |
|
||||
| Overlapped percent (%) | Adds overlapping text between adjacent chunks. Defaults to `0`; the control supports `0`–`30`. |
|
||||
| Image & table context window | Number of tokens taken before and after an image or table as context. Defaults to `0`; the slider ranges from `0` to `256`. |
|
||||
| Delimiters | Defaults to `\n`, `!`, `?`, `;`, `。`, `;`, `!`, and `?`. Add or remove entries as needed. |
|
||||
| Child chunk are used for retrieval | Splits parent chunks into smaller retrieval chunks using **Child delimiters**. Disabled by default. For line-based child chunks, enable it and add `\n`. |
|
||||
| Delimiters | Defaults to `\n`, `!`, `?`, `;`, `。`, `;`, `!`, and `?`. Each entry is a separate delimiter. Edit or remove entries, or click **Add** for another delimiter; check the **Splits at** preview. |
|
||||
| Child chunk are used for retrieval | Splits parent chunks into smaller retrieval chunks using **Child delimiters**, which appear after enabling the switch. Disabled by default. For line-based child chunks, enable it and add `\n`. |
|
||||
|
||||
The output is `chunks`, an array of objects that downstream components can process.
|
||||
|
||||
Click **Save draft** after configuring the node. [Publish and validate](./test_run.md) on a sample to check chunk boundaries, overlap, and child chunks.
|
||||
|
||||
## Title Chunker
|
||||
|
||||
Use Title Chunker for documents with clear headings, such as manuals and papers. Check that the resulting chunks keep each heading with its content.
|
||||
|
||||
|
||||
1. Choose **Hierarchy** to retain the heading path in each chunk, or **Group** to split at a selected heading level and group adjacent sections.
|
||||
2. Select the heading level and configure the matching rules. Use **Add Rule** for another heading pattern and **Add regular expressions** for additional levels within a rule.
|
||||
3. Set **Chunk token cap**. It defaults to `512`; the slider supports `128`–`8000`. Content exceeding the cap is split further at sentence boundaries.
|
||||
|
||||
@@ -10,11 +10,13 @@ sidebar_custom_props: {
|
||||
|
||||
# Configure the Indexer Component
|
||||
|
||||
**Indexer** prepares chunk data for full-text and embedding search. Connect it after the Chunker or Transformer and use the pipeline with a knowledge base to index documents.
|
||||
**Indexer** prepares chunk data for full-text and embedding search. Connect it after the Chunker, Transformer, or Compiler and use the pipeline with a knowledge base to index documents.
|
||||
|
||||
Click the Indexer node to open its panel. Review **Search method**, adjust **Filename embedding weight**, and select **Field** as described below.
|
||||
|
||||
## Search method
|
||||
|
||||
The panel displays the configured methods as labels:
|
||||
The panel displays **Embedding** and **Full-text** as labels, rather than selectable checkboxes:
|
||||
|
||||
- **Embedding**: Vector representations for semantic search.
|
||||
- **Full-text**: Tokenized text for keyword search.
|
||||
@@ -38,3 +40,7 @@ For Questions or Augmented context, first enable the corresponding function in T
|
||||
## Embedding model
|
||||
|
||||
The model comes from the connected knowledge base, rather than an independent model selector in this panel. Knowledge bases searched together must use the same embedding model.
|
||||
|
||||
## Apply and Validate
|
||||
|
||||
Click **Save draft**, resolve any **Checklist** issues, and publish a version. [Apply it to a test Dataset](./connect_the_pipeline_to_a_knowledge_base.md), parse a sample document, and check both the stored chunks and retrieval results. If **Field** is Questions or Augmented context, also check that the upstream Transformer generated the corresponding content.
|
||||
@@ -10,61 +10,61 @@ sidebar_custom_props: {
|
||||
|
||||
# Configure the Parser Component
|
||||
|
||||
The **Parser** component converts your files into structured text while preserving layout, tables, headers and other formatting.
|
||||
**Parser** extracts document content into structured items for a downstream Chunker. The available controls depend on the file category and the selected parser.
|
||||
|
||||
The initial configuration lists 12 file categories: **PDF**, **Spreadsheet**, **Image**, **Email**, **Markdown**, **Text & Code**, **HTML**, **DOC**, **DOCX**, **PPTX**, **Video**, and **Audio**. Configure the options for each required category.
|
||||
1. Open an editable pipeline under **Agent > Ingestion pipeline** and click **Parser**.
|
||||
2. Configure the categories your files require: **PDF**, **Spreadsheet**, **Image**, **Email**, **Markdown**, **Text & Code**, **HTML**, **DOC**, **DOCX**, **PPTX**, and **Audio**. There is no separate Video category in the current panel.
|
||||
3. Review the shared vision settings and the options for each required category below.
|
||||
|
||||
Key configurations:
|
||||
## Vision Enhancement
|
||||
|
||||
For PDF files, select one of the following:
|
||||
**Enable vision enhancement** is a shared switch at the top of the Parser panel. Turn it on to generate image descriptions, then select **Model** and review **System prompt**. Configure an accessible vision model first if the required model is not listed.
|
||||
|
||||
- **DeepDoc** (default): RAGFlow's built-in model. Use for scanned documents or complex layouts with tables.
|
||||
- **MinerU**: Parses mathematical formulas, tables, and complex page layouts.
|
||||
- **Naive**: Simple text extraction. Use it for clean, text-based PDFs without complex elements.
|
||||
This switch is separate from **OCR** under Image: OCR recognizes text, while vision enhancement generates descriptions. Keep at least one enabled for image processing.
|
||||
|
||||
## PDF
|
||||
|
||||
| Setting | How to use it |
|
||||
| --- | --- |
|
||||
| Detect multi-column layout | Enable for documents whose text is arranged in multiple columns. Check the reading order on sample pages. |
|
||||
| Remove original table of contents | Remove the document's existing table of contents from the parsed content when it is not needed for retrieval. |
|
||||
| Remove header and footer | Exclude repeated page headers and footers. |
|
||||
| Parser | Choose the parsing method or a configured model. See the choices below. |
|
||||
| Page ranges | Enter the start and end pages to process. Use **Add page** to add another range. |
|
||||
|
||||
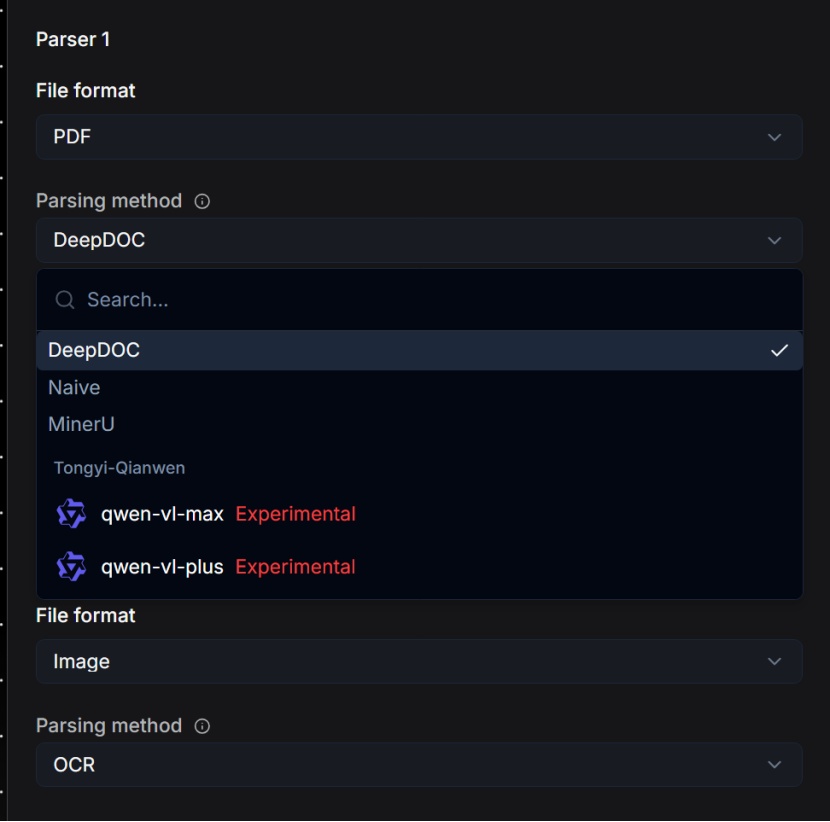
The **Parser** dropdown includes **DeepDOC**, **Naive**, **Docling**, **OpenDataLoader**, **TCADP Parser**, and **MonkeyOCRv2**, followed by available configured models grouped by provider. Choose a parser appropriate for your deployment and document layout, and validate its results on a sample file. **Naive** provides simple text extraction for text-based PDFs.
|
||||
|
||||
|
||||
|
||||
### MinerU formula and table controls
|
||||
Some selections expose additional controls:
|
||||
|
||||
When using MinerU for PDF, **Formula recognition** and **Table recognition** are enabled by default. Turn off the corresponding option when it is not needed.
|
||||
- **Language** appears for parsers that support this setting. Select the document language when the field is shown.
|
||||
- **TCADP Parser** shows **Table result type** (Markdown or HTML) and **Markdown image response type** (URL or Text).
|
||||
- A configured **MinerU** model exposes **Formula recognition** and **Table recognition**. These are conditional model settings; MinerU is not a fixed entry in the parser catalog. Add and configure the service in model settings before selecting its model.
|
||||
|
||||
Available controls depend on the connected MinerU service. Some services continue to recognize block formulas even when formula recognition is disabled. If parsing reports that an option is unsupported, ask an administrator to check the service configuration.
|
||||
Configured OCR and vision models depend on the pipeline owner's available providers and permissions. If a required model is missing or parsing fails, check its availability and connection settings. Selecting a parser does not configure its external service.
|
||||
|
||||
### SoMark and OpenDataLoader models
|
||||
## Image
|
||||
|
||||
To use **SoMark** or **OpenDataLoader**, first add and enable the OCR model in model settings, then select it in the PDF parser options. The selected model must be available to your account.
|
||||
1. Leave **OCR** enabled when you need to recognize text in images.
|
||||
2. Select **OCR model**. The panel offers the built-in DeepDoc option and configured OCR models where available.
|
||||
3. To generate image descriptions, enable the shared **Enable vision enhancement** switch at the top of the panel and configure its model and prompt.
|
||||
|
||||
If the model is unavailable or its connection settings are incomplete, parsing fails rather than switching to a different model. Check model access and ask an administrator to verify the connection.
|
||||
To turn OCR off, enable vision enhancement first. The panel rejects a configuration with both disabled.
|
||||
|
||||
### Other file types
|
||||
## Other File Categories
|
||||
|
||||
For image files:
|
||||
| Category | Configuration |
|
||||
| --- | --- |
|
||||
| Spreadsheet | Choose **Parser**. The fixed choices are DeepDOC and TCADP Parser; configured models may also be listed. TCADP Parser exposes the table and image response controls described above. |
|
||||
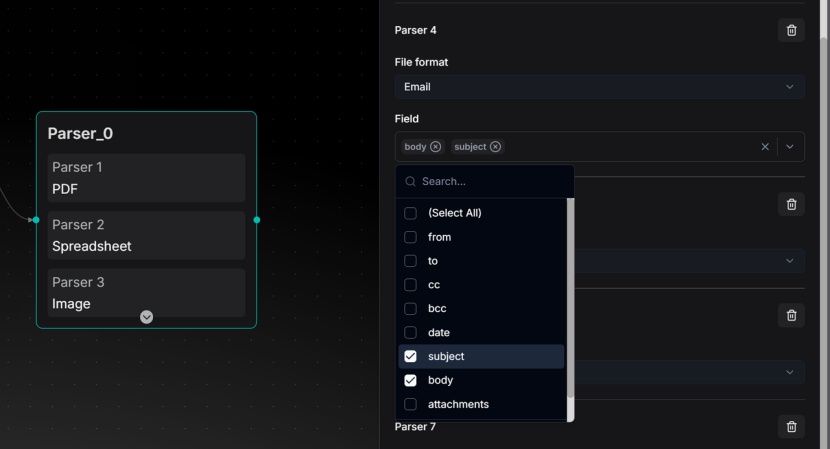
| Email | Select the required entries in **Field**: `from`, `to`, `cc`, `bcc`, `date`, `subject`, `body`, and `attachments`. |
|
||||
| Markdown / Text & Code | These sections have no additional parsing controls in the current panel. |
|
||||
| HTML / DOC / DOCX | Set **Remove header and footer** as required. |
|
||||
| PPTX | Choose **Parser**. The fixed choices are DeepDOC and TCADP Parser; configured models may also be listed. TCADP Parser exposes its table and image response controls. |
|
||||
| Audio | Select **Model** for speech recognition. Configure an accessible speech-to-text model first if none is available. |
|
||||
|
||||
- **OCR** is enabled by default. To turn it off, first enable **Enable vision enhancement**. Keep at least one of these options enabled so that images can produce searchable text.
|
||||
- **OCR model** selects local DeepDOC or an available configured PaddleOCR model. The model must be available to the canvas owner.
|
||||
- **Enable vision enhancement** separately controls image descriptions. Enabling OCR does not enable vision enhancement.
|
||||
- SVG text is read directly.
|
||||
- Check parsing warnings if text recognition fails. A configuration with both OCR and vision enhancement disabled is rejected.
|
||||
## Output and Validation
|
||||
|
||||
For email files:
|
||||
**Output** displays `json` as an array of objects. This is the node's output definition, not an output selector. Connect **Token Chunker** or **Title Chunker** after Parser to split the parsed items into `chunks`.
|
||||
|
||||
- Select specific fields to parse, such as `subject` and `body`, for precise extraction.
|
||||
|
||||
|
||||
|
||||
For spreadsheets:
|
||||
|
||||
- Preserves table content and row/column structure in the parsed items.
|
||||
|
||||
For Word/PPT:
|
||||
|
||||
- Preserves document structure, such as headings, paragraphs, and slides, in the parsed items.
|
||||
|
||||
For text and markup (HTML/MD):
|
||||
|
||||
- Extracts document content as structured items for downstream chunking.
|
||||
|
||||
|
||||
### Output
|
||||
|
||||
Select the `json` output to use the parsed content. It contains structured items such as paragraphs and tables. Connect **Token Chunker** or **Title Chunker** after Parser to split this content into `chunks` for Transformer, Compiler, or Indexer.
|
||||
Click **Save draft**, resolve any **Checklist** issues, publish a version, and [validate it in a test Dataset](./test_run.md). Check extracted text, reading order, tables, and image descriptions for the file types and features you use.
|
||||
@@ -10,29 +10,44 @@ sidebar_custom_props: {
|
||||
|
||||
# Configure the Transformer Component
|
||||
|
||||
**Transformer** uses a chat model to generate summaries, keywords, questions, tags, or metadata for document chunks. These additions provide more ways to find relevant content during retrieval.
|
||||
**Transformer** uses an LLM to enrich document chunks with keywords, questions, tags, summaries, and metadata. Configure it on the **Agent > Ingestion pipeline** canvas. One Transformer can enable several extraction functions at the same time.
|
||||
|
||||
Enable one or more of the following options:
|
||||
## Open the Configuration Panel
|
||||
|
||||
- **Summary**: Creates a concise overview.
|
||||
- **Auto keywords**: Extracts key terms.
|
||||
- **Auto-question**: Generates questions that each text chunk can answer.
|
||||
- **Tags**: Assigns relevant tags from the selected **Tag file**. Set the maximum number of tags to extract.
|
||||
- **Metadata**: Custom metadata extraction.
|
||||
1. Open **Agent**, select **Ingestion pipeline**, and open the pipeline you want to edit.
|
||||
2. Add **Transformer** after a chunking component, or click an existing Transformer node to open its configuration panel.
|
||||
3. In **Model**, select an available chat model. Configure the model provider first if the required model is not listed.
|
||||
4. Expand each function you need and turn on its switch. Expanding a section only shows its settings; use the switch beside the section name to enable processing.
|
||||
|
||||
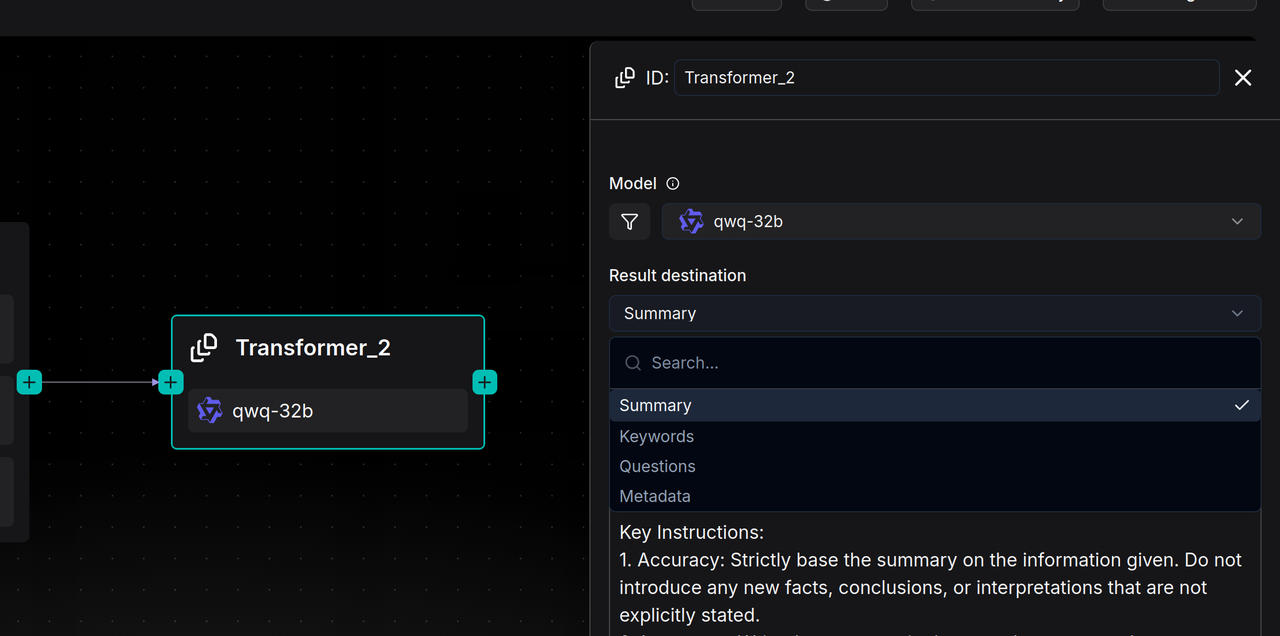
|
||||
The panel lists **Auto keywords**, **Auto-question**, **Tags**, **Summary**, and **Metadata** in that order.
|
||||
|
||||
A single **Transformer** can enable multiple options; a separate component is not required for each function.
|
||||
## Configure Extraction Functions
|
||||
|
||||
Key configurations:
|
||||
| Function | Settings and purpose |
|
||||
| --- | --- |
|
||||
| Auto keywords | Set **Number of keywords to extract** and review **System prompt**. The model extracts key terms from each chunk to assist retrieval. |
|
||||
| Auto-question | Set **Auto-question number** and review **System prompt**. The model generates questions that the chunk can answer. |
|
||||
| Tags | Set **Auto-tags** to control the number of tags and select the source under **Tag file**. The model assigns tags from that source. |
|
||||
| Summary | Review or customize **System prompt** to control how the model summarizes chunk content. |
|
||||
| Metadata | Enable metadata generation and click **Settings** to define custom fields or select built-in fields. See the steps below. |
|
||||
|
||||
**Model**: Select a configured chat model.
|
||||
Enable only the functions you need. Review the prompts for your document language, required output, and business scope before processing a large collection of files.
|
||||
|
||||
Prompt engineering:
|
||||
## Configure Metadata
|
||||
|
||||
- Customize **System prompt** where the selected option provides it.
|
||||
1. Expand **Metadata**, turn on its switch, and click **Settings**.
|
||||
2. In **Metadata generation settings**, open **Generation** and click **Add** to define a custom field.
|
||||
3. In **Field settings**, enter **Field name**, select **Type**, and fill in **Description** to explain what the model should extract. If the field must use predefined values, enable **Restrict to defined values** and configure the allowed values.
|
||||
4. Click **Confirm** to add the field. Check the **Field**, **Description**, **Type**, and **Values** columns in the list.
|
||||
5. Open **Built-in** if you need fields such as **update_time** or **file_name**, and enable the fields you want to include.
|
||||
6. Click **Save** to apply the metadata field settings to the node. This dialog button is separate from **Save draft** on the canvas.
|
||||
|
||||
Connection and input:
|
||||
Use consistent field names and types across documents so the generated metadata can be used in retrieval filters. Check the generated values on sample documents before relying on them for filtering.
|
||||
|
||||
- Connect **Transformer** to an upstream node that provides document chunks. It enriches those chunks with the enabled extraction results.
|
||||
- After **Transformer**, add **Indexer** for indexing or **Compiler** for knowledge compilation. Generated summaries are stored alongside the original chunk text.
|
||||
## Connect and Validate
|
||||
|
||||
Connect Transformer to an upstream component that produces `chunks`. Add **Indexer** after Transformer for indexing, or **Compiler** for knowledge compilation followed by Indexer. For example:
|
||||
|
||||
**Begin → Parser → Token chunker → Transformer → Indexer**
|
||||
|
||||
The node outputs enriched `chunks` for downstream components. Click **Save draft** on the pipeline canvas, resolve any issues shown in **Checklist**, and publish a version when the configuration is ready. Expand the pipeline under **Configuration > Parsing mode** in a test Dataset, select that published version within the dropdown, and [validate the pipeline](./test_run.md) with a representative document. Check the generated keywords, questions, tags, summaries, and metadata for the functions you enabled.
|
||||
@@ -10,14 +10,17 @@ sidebar_custom_props: {
|
||||
|
||||
# Connect the Pipeline to a Knowledge Base
|
||||
|
||||
1. When creating or editing a knowledge base, find the parsing method section.
|
||||
2. Open **Parse mode** and select your pipeline.
|
||||
Publish a pipeline version before applying a custom pipeline to a Dataset. Saving a draft alone does not make it selectable for document processing.
|
||||
|
||||
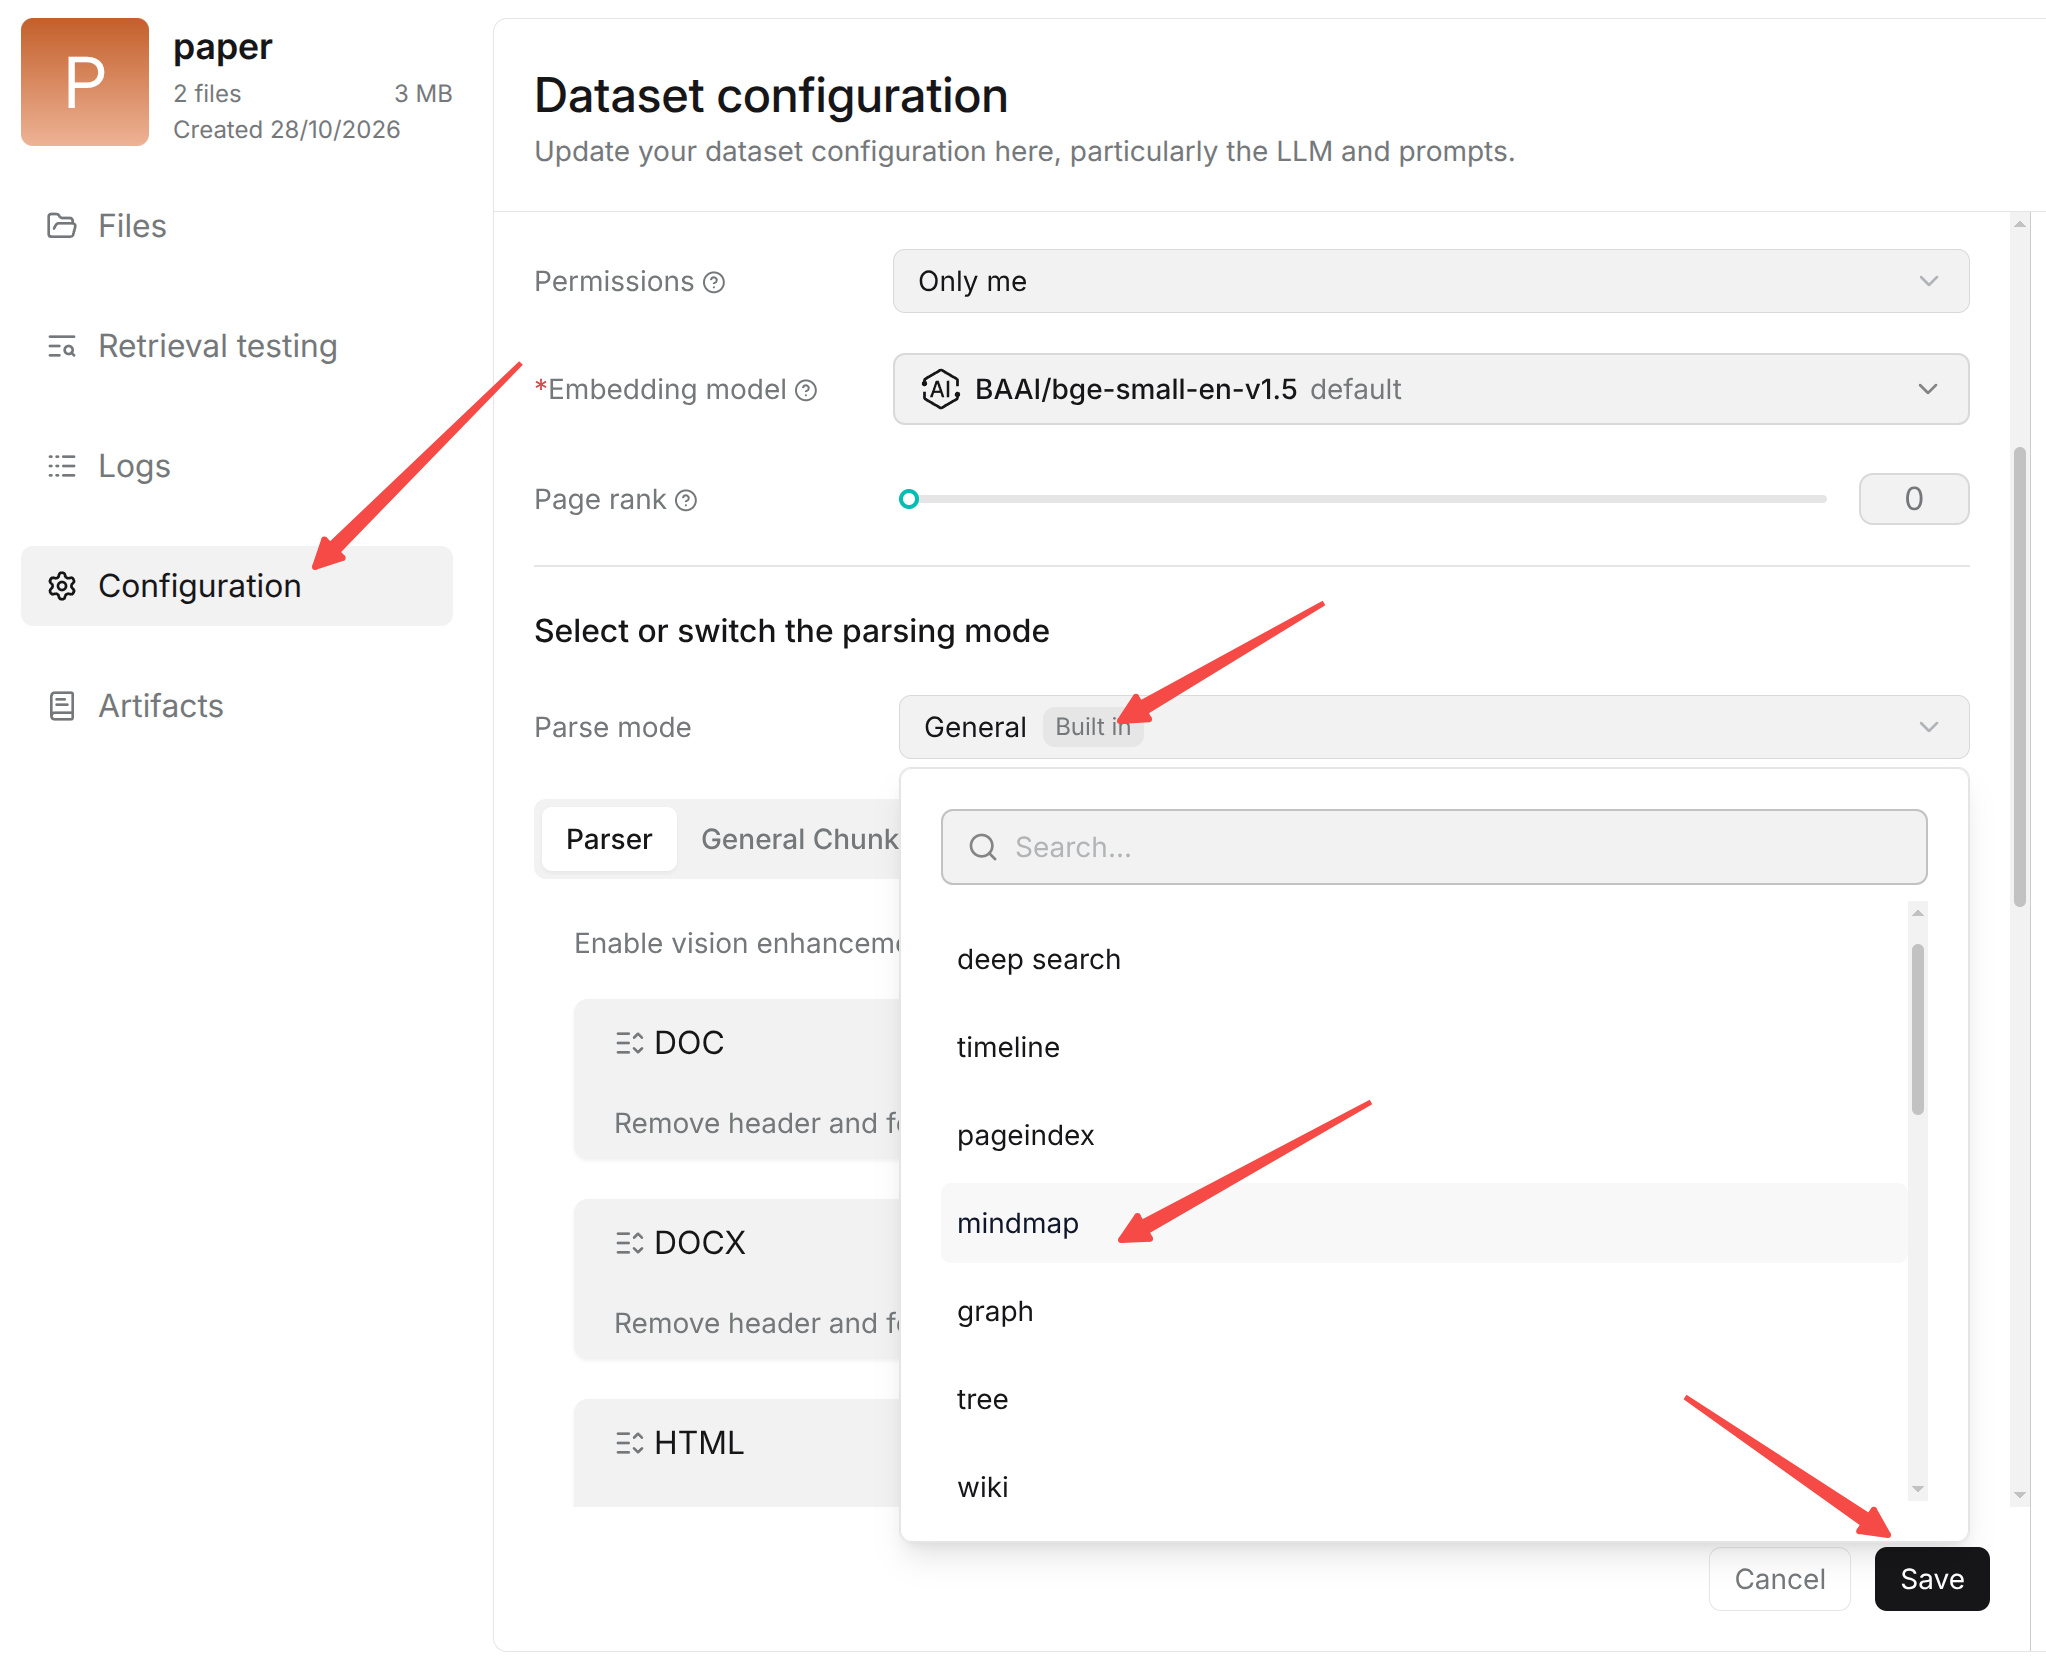
|
||||
1. Open the target Dataset and select **Configuration**.
|
||||
2. Find **Parsing mode** and open its dropdown. Search for the pipeline name if needed.
|
||||
3. Expand the custom pipeline to view its published versions, then select the required version within the same dropdown. Use the version title and alias, when provided, to identify the intended configuration. The pipeline name itself is a group, not a selectable draft.
|
||||
|
||||
The screenshot shows pipeline selection in **Parse mode**. The **Version** selector appears after choosing a pipeline.
|
||||

|
||||
|
||||
3. In the dataset configuration, select a pipeline **Version**, then click **Save**.
|
||||
4. Files uploaded to this knowledge base use the selected pipeline version.
|
||||
4. Click **Save** to apply the selection to the Dataset.
|
||||
5. [Parse a sample document and inspect the results](./test_run.md) before processing more files.
|
||||
|
||||
The dataset keeps its selected pipeline version. To use a different version, select the target version in **Configuration** and save.
|
||||
There is no separate Version dropdown. **No published versions** means the pipeline has no version available for selection: return to its canvas, check the configuration, and click **Publish** first. Entries marked **Built in** are built-in parsing modes and can be selected directly without expanding a custom pipeline.
|
||||
|
||||
The Dataset keeps its selected pipeline version when another version is published. To apply an update, reopen **Configuration > Parsing mode**, expand the pipeline, select the new version, and click **Save**. Reparse existing documents that need the updated processing; changing the selection does not regenerate their existing chunks.
|
||||
@@ -10,13 +10,61 @@ sidebar_custom_props: {
|
||||
|
||||
# Create an Ingestion Pipeline
|
||||
|
||||
1. Open **Agent > Create agent > Create from blank**.
|
||||
2. Select **Ingestion pipeline**, enter a name, and click **Confirm**.
|
||||
An ingestion pipeline parses documents, splits content into chunks, optionally enriches or compiles it, and sends the results to an index. Create and manage pipelines under **Agent > Ingestion pipeline**.
|
||||
|
||||
## Create a Pipeline
|
||||
|
||||
1. Open **Agent** and select **Ingestion pipeline**, then click **+** to open the creation menu.
|
||||
2. Choose **Create from blank**, enter **Name**, and click **Confirm**.
|
||||
3. Open the created card. The canvas starts with **Begin → Parser**.
|
||||
4. Configure Parser, then use its outgoing connection point to add **Token Chunker** or **Title Chunker**.
|
||||
5. From Token Chunker, add **Transformer** if enrichment is needed, then add **Indexer**. A basic flow is **Begin → Parser → Token Chunker → Transformer → Indexer**.
|
||||
6. Configure each component, review **Checklist**, and click **Save**.
|
||||
4. Click **Parser** and configure the file types you need to process. Use its outgoing connection point to add **Token chunker** or **Title chunker**.
|
||||
5. Add **Transformer** if you need to enrich chunks, or **Compiler** for knowledge compilation. Connect the final processing step to **Indexer**.
|
||||
6. Configure each component and click **Save draft**. If **Checklist** appears, open it and resolve the reported configuration issues.
|
||||
|
||||
Use each component's outgoing connection point to add the next step. After Transformer, choose Indexer or Compiler.
|
||||
A basic flow is **Begin → Parser → Token chunker → Indexer**. Add optional processing steps according to your document requirements.
|
||||
|
||||
See [Validate the pipeline](./test_run.md) before processing a collection of documents.
|
||||
## Start from a Template
|
||||
|
||||
Choose **Create from template** from the same creation menu, select a template, and follow the creation dialog. Open the resulting pipeline and review each component's models, prompts, and referenced resources before publishing it.
|
||||
|
||||
## Start from a Built-in Pipeline
|
||||
|
||||
The same list includes **Built-in pipelines**, such as General, Q&A, Manual, and Table. Click a built-in card to inspect its configuration. The built-in preview is read-only. Use the card's **Copy** button to create an editable pipeline, then configure the copy for your documents.
|
||||
|
||||

|
||||
|
||||
## Pipeline Canvas Toolbar
|
||||
|
||||
An editable pipeline has **Save draft**, **Publish**, and **Management** in the upper-right corner. It has no **Run** or **Launch** button. Test document processing from a Dataset after selecting a published pipeline version.
|
||||
|
||||
| Button | When and how to use it |
|
||||
| --- | --- |
|
||||
| Save draft | Save the current pipeline configuration. The **Autosaved** time below the name shows the latest save. Saving a draft does not publish a version for a Dataset to select. |
|
||||
| Publish | Publish the current configuration as a version. Optionally enter an **Alias** in the confirmation dialog, then click **Confirm**. Select this version in the target Dataset configuration. |
|
||||
| Checklist | Appears when configuration issues are detected. Open it and click an issue to locate the affected component. Correct the configuration; the button disappears when no issues are detected. |
|
||||
| Management | Open the pipeline's variables, version history, JSON export, or settings. |
|
||||
|
||||
### Management Menu
|
||||
|
||||
| Entry | What you can do |
|
||||
| --- | --- |
|
||||
| Conversation variable | Open the variable configuration provided by the editor. This menu entry does not start a conversation or parse a document. |
|
||||
| Version history | Browse version records and inspect pipeline configurations. Use the version information to identify the configuration you intend to apply to a Dataset. |
|
||||
| Export | Download the current pipeline canvas configuration as JSON. |
|
||||
| Settings | Change the pipeline title, avatar, description, and access permissions for yourself or your team. Save the settings dialog to apply changes. |
|
||||
|
||||
## Publish and Apply a Pipeline
|
||||
|
||||
1. Complete the component configuration and connections, then click **Save draft**.
|
||||
2. Resolve any issues shown in **Checklist**.
|
||||
3. Click **Publish**, optionally enter an **Alias**, and click **Confirm**.
|
||||
4. In the target Dataset's **Configuration**, open **Parsing mode**, expand the custom pipeline, select a published version within that dropdown, and click **Save**. If it shows **No published versions**, publish the pipeline first.
|
||||
5. [Validate the pipeline](./test_run.md) with a small sample before processing more files.
|
||||
|
||||
Publishing another version does not switch the version already selected by a Dataset. To apply an update, select the new version under the pipeline in **Configuration > Parsing mode** and click **Save**, then parse the documents that need the updated processing.
|
||||
|
||||
## Import and Export a Pipeline
|
||||
|
||||
To export, open an editable pipeline and choose **Management > Export**. The browser downloads the current canvas configuration as a JSON file.
|
||||
|
||||
To import, select **Agent > Ingestion pipeline**, choose **Import JSON file** from the creation menu, enter **Name**, upload the pipeline JSON under **DSL**, and click **Save**. Open the imported card and check models, compilation template groups, and other referenced resources. These resources are not transferred by importing JSON. Save the draft, publish a version, and validate it in a test Dataset before use.
|
||||
@@ -10,11 +10,13 @@ sidebar_custom_props: {
|
||||
|
||||
# Validate the Pipeline
|
||||
|
||||
Save the pipeline, then parse a sample document in a connected knowledge base to check the results.
|
||||
Publish a pipeline version, then parse a sample document in a connected knowledge base to check the results. The pipeline canvas has no **Run** button; document processing is started from the knowledge base.
|
||||
|
||||
1. Review **Checklist**, resolve configuration issues, and click **Save**.
|
||||
2. [Connect the pipeline to a knowledge base](./connect_the_pipeline_to_a_knowledge_base.md). Use a dedicated test knowledge base to avoid affecting existing documents.
|
||||
1. Click **Save draft**. If **Checklist** appears, resolve its configuration issues. Click **Publish** and confirm to create the version you want to test.
|
||||
2. [Connect the pipeline to a knowledge base](./connect_the_pipeline_to_a_knowledge_base.md), expand it in **Configuration > Parsing mode**, select a published version within the dropdown, and click **Save**. Use a dedicated test knowledge base to avoid affecting existing documents.
|
||||
3. Upload a small sample file and start parsing from the knowledge base's document controls.
|
||||
4. Check the document's parsing status and resulting chunks. Confirm that content, chunk boundaries, and enabled enrichment results meet your needs before processing more files.
|
||||
|
||||
If parsing fails, use the reported error to check the parser, model access, and component settings.
|
||||
Check the functions you actually enabled: PDF reading order and page ranges, OCR or image descriptions, chunk size and heading structure, Transformer enrichment, and Compiler output. Check retrieval after indexing, especially when Indexer uses Questions or Augmented context.
|
||||
|
||||
If parsing fails, use the reported error to check the parser, model access, and component settings. After changing the pipeline, save and publish a new version, select that version in the test Dataset, and reparse the sample. A saved draft or a newly published version does not update a Dataset's existing selection or document chunks automatically.
|
||||
+16
-5
@@ -13,17 +13,28 @@ sidebar_custom_props: {
|
||||
The Ingestion Pipeline is composed of the following core components:
|
||||
|
||||
- **Parser component**: Reads and understands your files, such as PDFs, images, emails and other file types, and extracts text and structure.
|
||||
- **Chunker component**: Splits parsed content into chunks. The custom pipeline menu offers Token Chunker and Title Chunker.
|
||||
- **Transformer component**: Enriches chunks with summaries, keywords, questions, tags, or metadata. Multiple functions can be enabled in one node.
|
||||
- **Chunker component**: Splits long text into smaller sections, or chunks, for retrieval.
|
||||
- **Compiler component**: Organizes chunks into a knowledge tree, mind map, or wiki using a compilation template group and model.
|
||||
- **Indexer component**: The final step. Sends the processed data to the document engine, supporting hybrid full-text and vector search.
|
||||
|
||||
A typical flow is **Begin → Parser → Token Chunker → Transformer → Indexer**. Transformer is optional. The outgoing connection menu also provides **Compiler** after Token Chunker or Transformer for knowledge compilation.
|
||||
A typical flow is **Begin → Parser → Token Chunker → Transformer → Indexer**. Transformer is optional. The outgoing connection menu also provides **Compiler** after Token Chunker, Title Chunker, or Transformer for knowledge compilation.
|
||||
|
||||
## Add and Connect Components
|
||||
|
||||
**Begin** is the entry point for the uploaded file. Click a component's outgoing connection point to see the components available at that position.
|
||||
|
||||
- Connect **Parser** to a chunking component. Its structured `json` output must be split into `chunks` for downstream processing.
|
||||
- Choose one chunking component per canvas: **Token Chunker** or **Title Chunker**. A Chunker cannot connect directly to another Chunker.
|
||||
- Add **Transformer** for enrichment or **Compiler** for knowledge compilation, then connect the final processing step to **Indexer**.
|
||||
- Parser, Transformer, Compiler, and Indexer are each limited to one instance per canvas. Components already present are omitted from the add menu.
|
||||
|
||||
The connection menu depends on the selected node and the components already on the canvas. Complete the required fields and resolve **Checklist** issues before publishing.
|
||||
|
||||
## Configure the Compiler Component
|
||||
|
||||
1. Prepare a template group through **Agent > Create agent > Create from blank > Compilation operator**. See [template configuration](../../knowledge_compilation/basic_information_configuration.md). Then add **Compiler** after Token Chunker, Title Chunker, or Transformer; one Compiler is allowed per canvas.
|
||||
2. Select an accessible **Compilation template group** and chat model. Choose templates for the result you need, such as a knowledge tree or wiki. **Compilation operator** configurations use the same settings.
|
||||
3. Connect **Compiler → Indexer** to index the original and generated chunks. Save and [validate the pipeline](./test_run.md) with a sample document.
|
||||
1. Prepare a template group through **Agent > Compilation operator > Create from blank**. See [template configuration](../../knowledge_compilation/basic_information_configuration.md). Then add **Compiler** after Token Chunker, Title Chunker, or Transformer; one Compiler is allowed per canvas.
|
||||
2. In the Compiler panel, select a template group under **Operator**. To create a group from this panel, click **Create template** beside the field and complete the dialog. You can also manage groups on the **Compilation operator** tab. Select the execution model under **Model** and review its model settings. The selected group determines the compilation tasks, such as a knowledge tree or wiki.
|
||||
3. Connect **Compiler → Indexer** to index the original and generated chunks. Click **Save draft**, publish a version, and [validate the pipeline](./test_run.md) with a sample document.
|
||||
|
||||
Example: **Begin → Parser → Token Chunker → Compiler → Indexer**. After parsing, check the generated content and retrieval results. If the template group or model is unavailable after import, select an accessible one.
|
||||
@@ -15,7 +15,7 @@ Build a workflow that answers product questions through retrieval and collects c
|
||||
|
||||
## Build the workflow
|
||||
|
||||
1. [Create a blank Workflow Agent](../creation_and_management.md#create-from-blank-agent) named `Customer support demo`.
|
||||
1. [Create a blank Workflow Agent](../create_and_manage_workflows.md#create-from-blank-workflow) named `Customer support demo`.
|
||||
2. After **Begin**, add **Categorize**. Use `sys.query` as the query variable and select the chat model.
|
||||
3. Add two categories:
|
||||
|
||||
|
||||
@@ -1,60 +0,0 @@
|
||||
---
|
||||
sidebar_position: 6
|
||||
title: Understand the Canvas
|
||||
sidebar_label: Understand the Canvas
|
||||
slug: /understand_the_canvas
|
||||
sidebar_custom_props: {
|
||||
categoryIcon: RagAiAgent
|
||||
}
|
||||
---
|
||||
|
||||
# Understand the Canvas
|
||||
|
||||
## Add Components
|
||||
Click the plus sign next to any component on the canvas to select the next component. Workflow and Ingestion pipeline canvases offer different component menus. Workflow components include `Begin`, `Agent`, `Retrieval`, `Message`, `Await response`, `Switch`, `Iteration`, `Categorize`, `Code`, `Text processing`, `Execute SQL`, `HTTP Request`, while Ingestion pipeline components include `Parser`, `Title chunker`, `Token chunker`, `Transformer`, `Compiler`, and `Indexer`.
|
||||
|
||||
After adding a component, click the component itself to open the configuration panel on the right. Fields in the configuration panel define input data, processing logic, output variables, and references for subsequent steps.
|
||||
|
||||
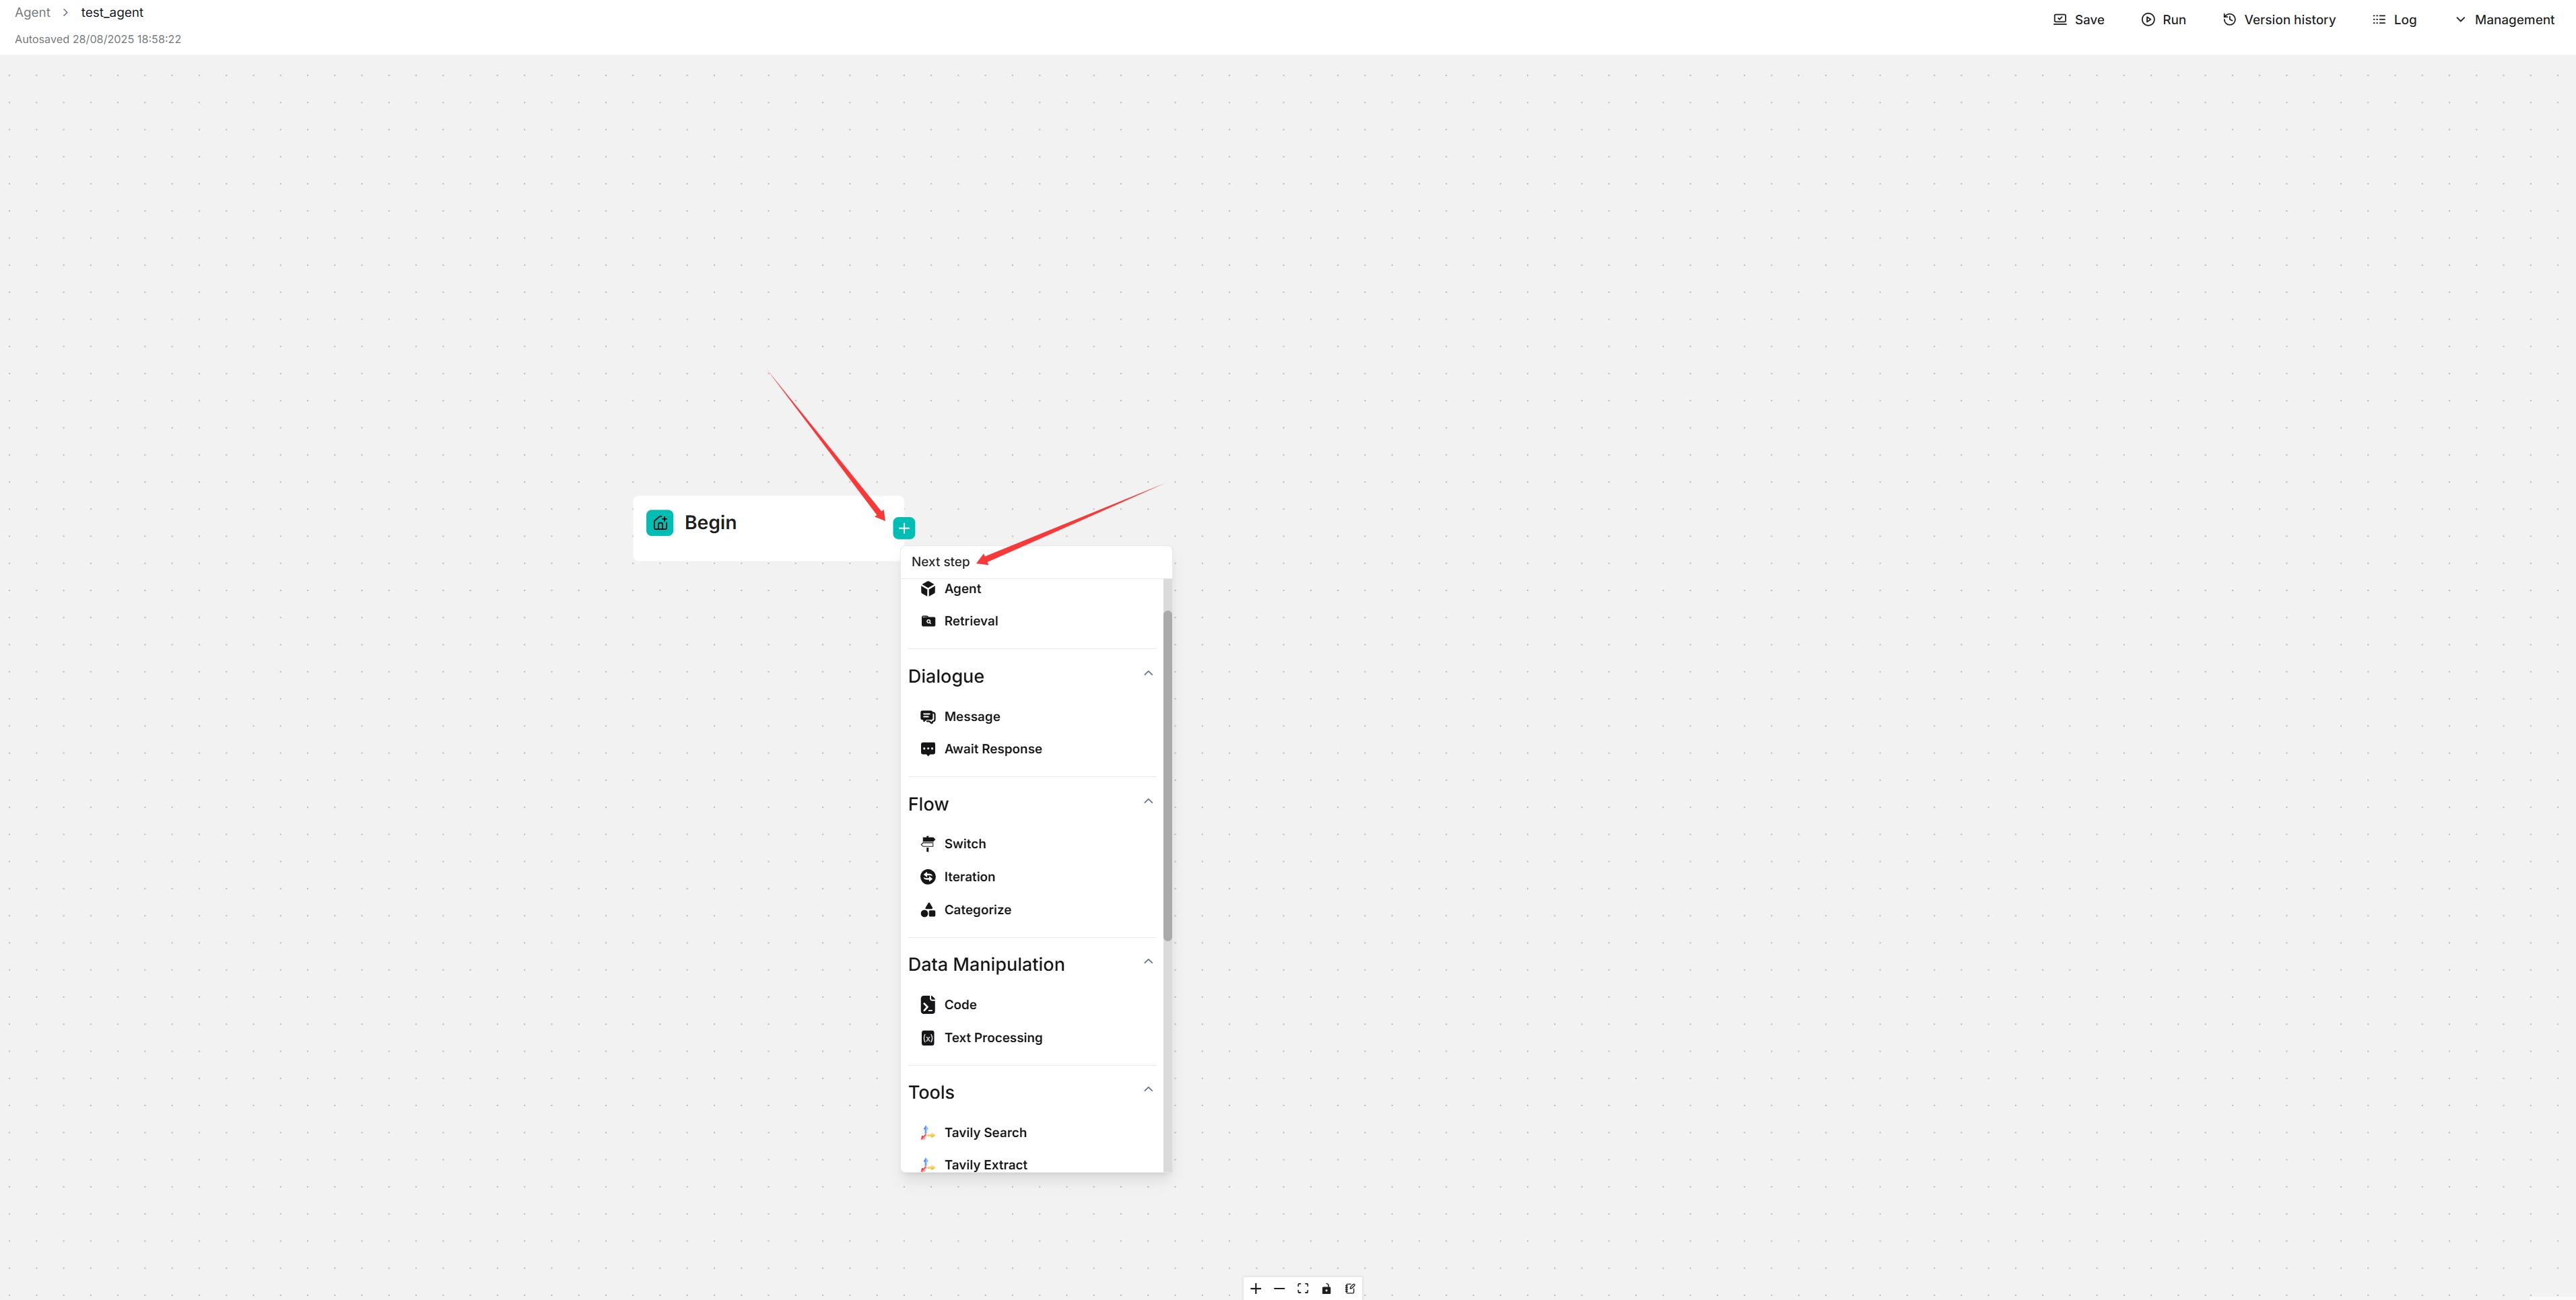
|
||||
|
||||
## Use Variables
|
||||
Components on the Agent canvas support variable references to implement data transmission between components. Variable sources include system variables, global variables defined in the Begin component, and outputs from upstream components.
|
||||
|
||||
In fields that support variables, type `/` or click the variable button to open the variable selector, then choose the required variable. This inserts a reference to the component on your canvas; names shown in examples are illustrative and should not be typed as references.
|
||||
|
||||
Common variables:
|
||||
| Variable | Description |
|
||||
| ---- | ---- |
|
||||
| `sys.query` | Current user input question |
|
||||
| `formalized_content` | Sorted text results from Retrieval, SQL or tool components |
|
||||
| `chunks` | Fragment set output by document parsing or chunking components |
|
||||
| `content` | Main text output from Agent, Code or other components |
|
||||
|
||||
Operation Steps:
|
||||
1. Enter the Agent page and open the target canvas for editing.
|
||||
2. Select a component supporting variable references, e.g. Agent, Retrieval, Message, Code, HTTP Request, Execute SQL.
|
||||
3. On the right configuration panel, click the input box that needs variable reference, such as **System prompt**, **User prompt**, or **Query variables**.
|
||||
4. Open the variable selector via either method:
|
||||
- Type `/` inside the input box
|
||||
- Click the variable icon next to the input box (may display as `{}`, `+` or other icons in different versions)
|
||||
5. Select required variables in the selector. Available variables include:
|
||||
- System variables such as `sys.query`
|
||||
- Global variables defined in the Begin component
|
||||
- Output variables from upstream components
|
||||
6. After selection, the variable will be automatically inserted into the input box.
|
||||
7. Save component configuration and run the Agent to verify data transmission.
|
||||
|
||||
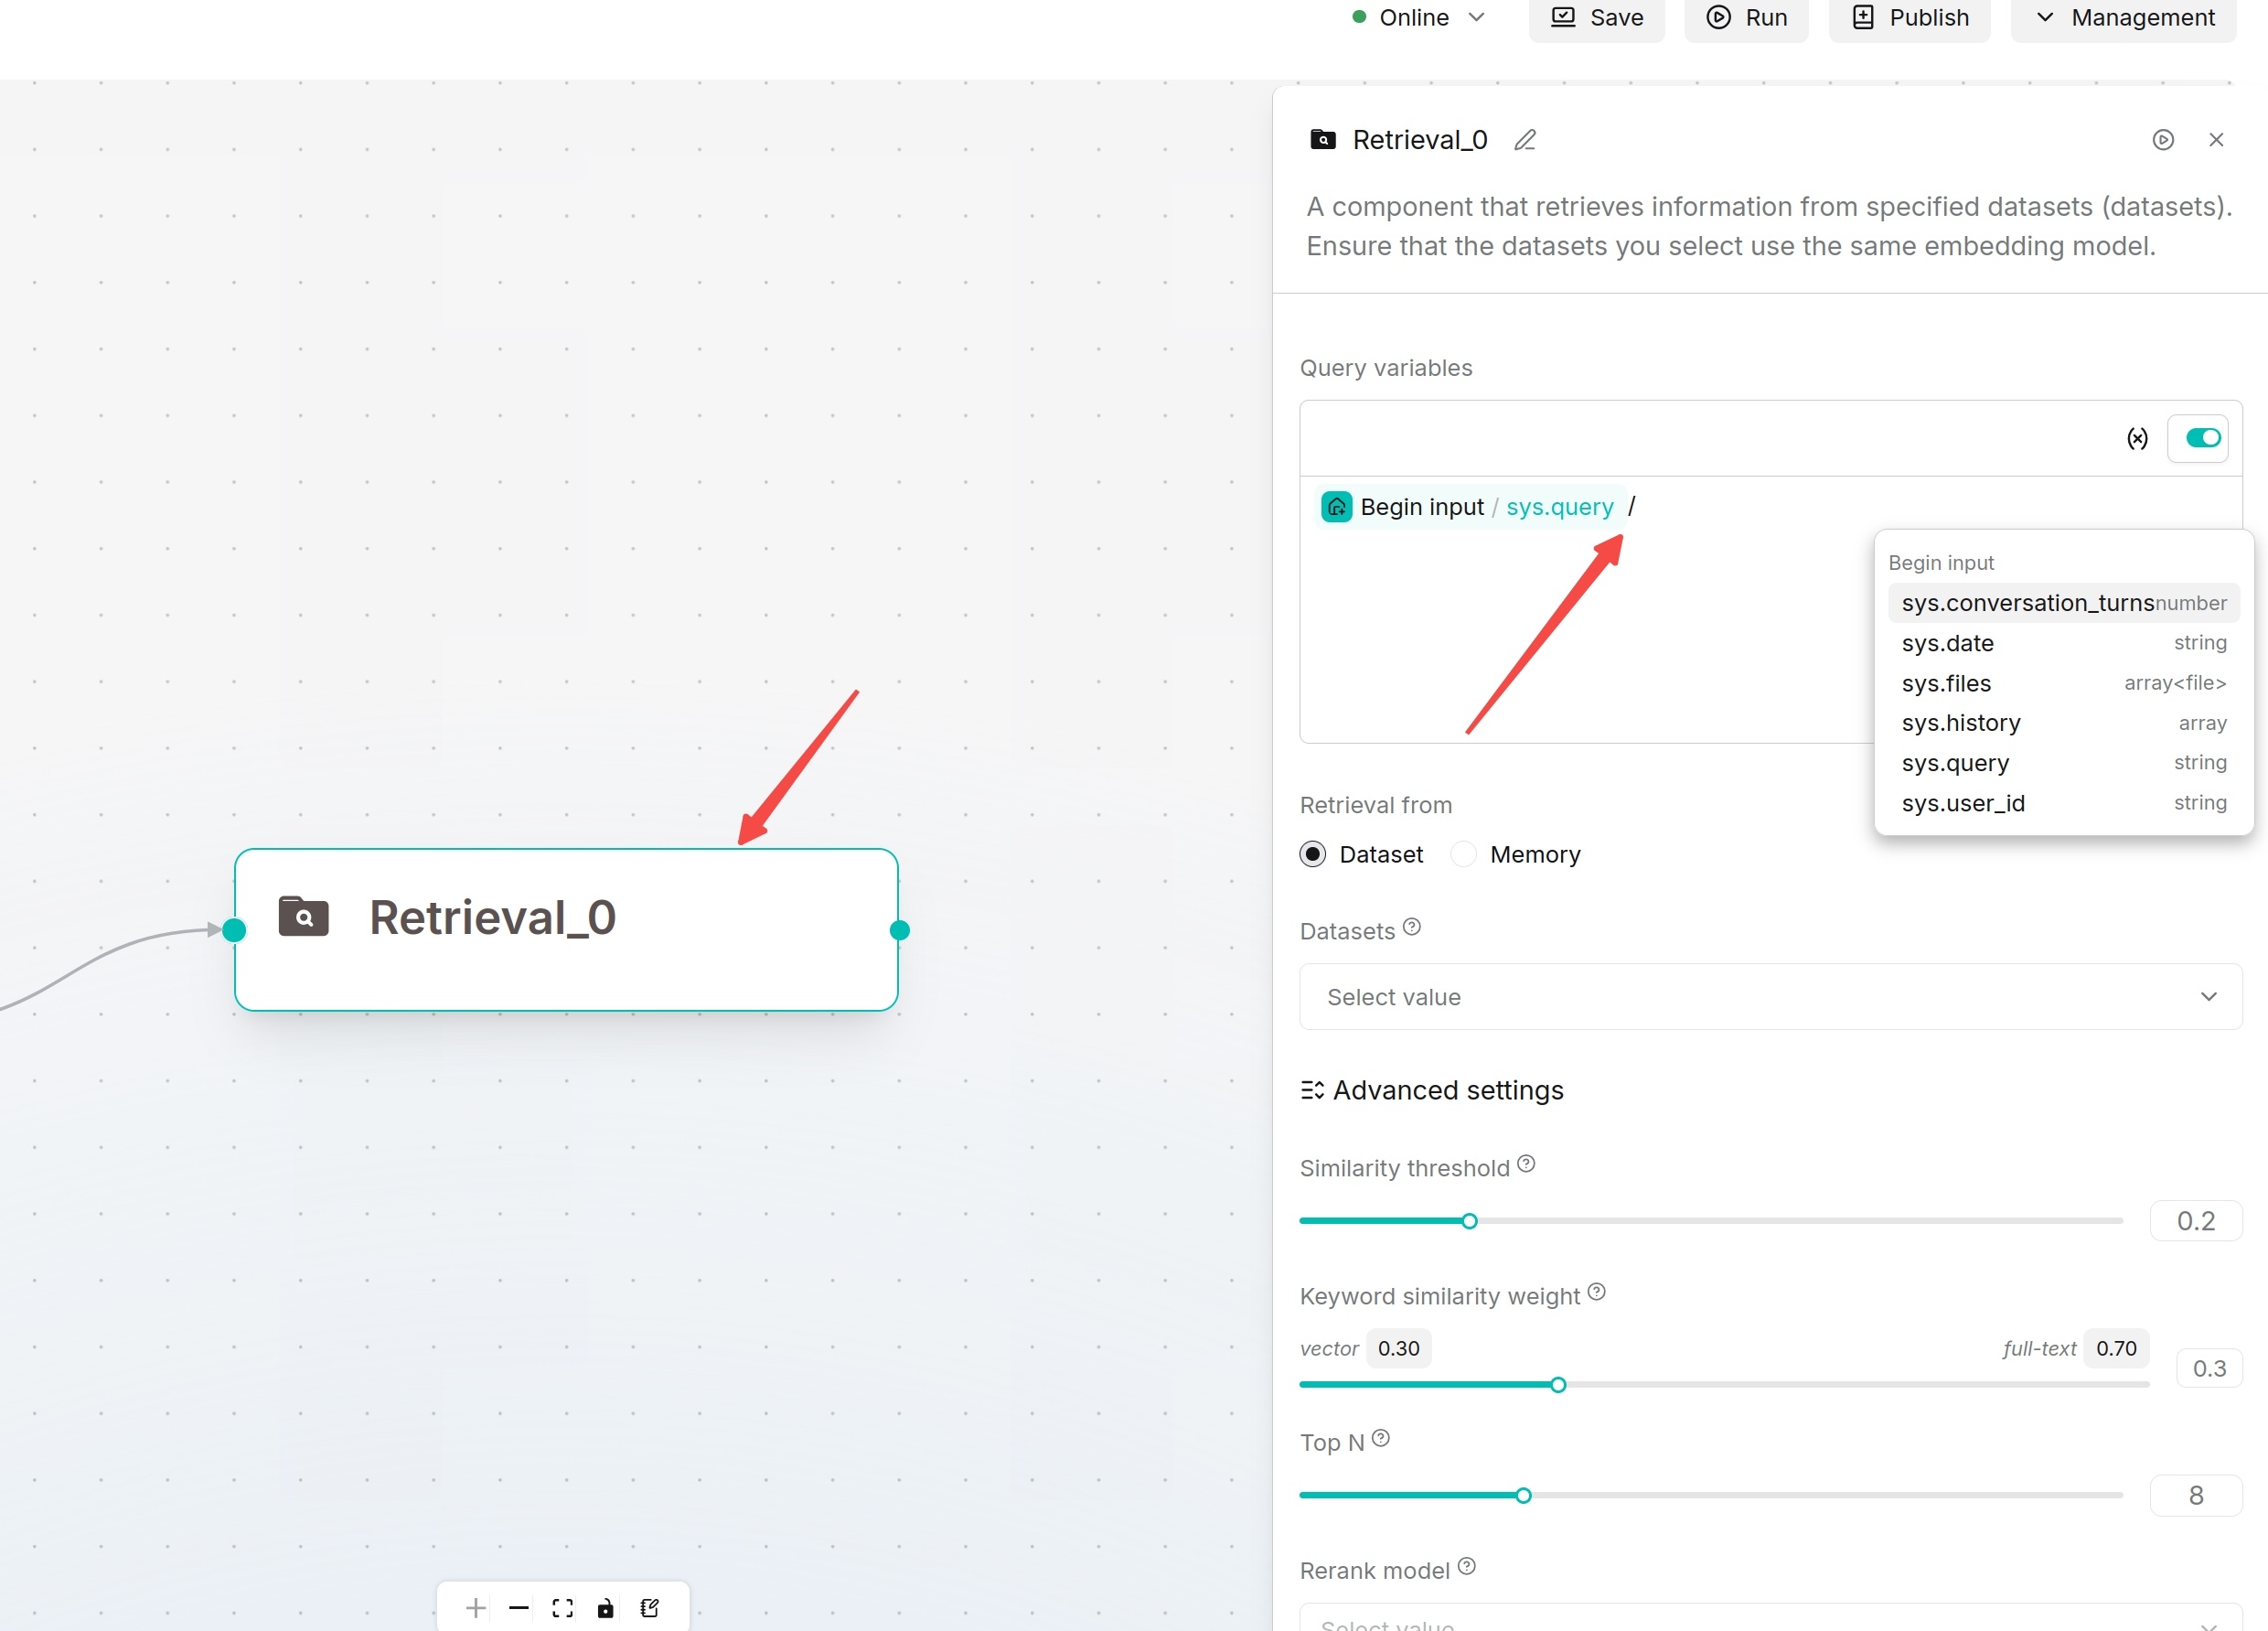
|
||||
## Save & Run
|
||||
For a **Workflow**, click **Save** after configuration. During debugging, click **Run** at the top of the canvas, enter test questions and observe the execution result of each component. If a component returns no output, check input variables, model configuration, knowledge base permissions, external interface addresses or tool configuration.
|
||||
|
||||
For an **Ingestion pipeline**, save the configuration and [validate it with a test knowledge base](./ingestion_pipeline/test_run.md).
|
||||
|
||||
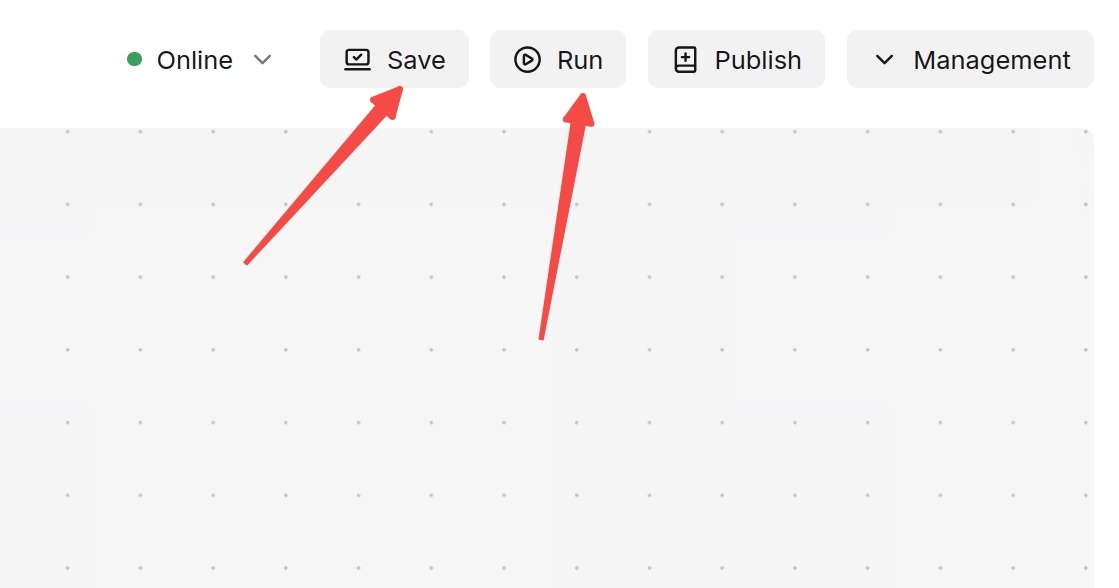
|
||||
## Component Connection Rules
|
||||
Connections define component execution order. Sequential components run along a single path. Branch components such as `Switch` and `Categorize` route workflows to different exits according to conditions. `Iteration` executes sub-processes in loops. Components not connected to the execution path will not run. Before deleting a component, check upstream/downstream connections and variable references to avoid missing inputs for subsequent nodes.
|
||||
|
||||
## Configuration Panel
|
||||
Click any canvas component to open the right-side configuration panel, which displays fields, input variables, output variables and execution settings. Recommended workflow: confirm which variable the component reads → configure processing logic → verify downstream nodes reference correct outputs.
|
||||
|
||||
For slow workflows, see [Improve Agent Response Time](./best_practices/accelerate_agent_question_answering.md).
|
||||
@@ -0,0 +1,85 @@
|
||||
---
|
||||
sidebar_position: 6
|
||||
title: Understand the Workflow Canvas
|
||||
sidebar_label: Understand the Workflow Canvas
|
||||
slug: /understand_the_canvas
|
||||
sidebar_custom_props: {
|
||||
categoryIcon: RagAiAgent
|
||||
}
|
||||
---
|
||||
|
||||
# Understand the Workflow Canvas
|
||||
|
||||
## Add Components
|
||||
This chapter describes the Workflow canvas. Click a component's outgoing connection point to select the next component. Workflow components include `Begin`, `Agent`, `Retrieval`, `Message`, `Await response`, `Switch`, `Iteration`, `Categorize`, `Code`, `Text processing`, `Execute SQL`, and `HTTP Request`.
|
||||
|
||||
After adding a component, click the component itself to open the configuration panel on the right. Fields in the configuration panel define input data, processing logic, output variables, and references for subsequent steps.
|
||||
|
||||

|
||||
|
||||
## Use Variables
|
||||
Components on the Agent canvas support variable references to implement data transmission between components. Variable sources include system variables, global variables defined in the Begin component, and outputs from upstream components.
|
||||
|
||||
In fields that support variables, type `/` or click the variable button to open the variable selector, then choose the required variable. This inserts a reference to the component on your canvas; names shown in examples are illustrative and should not be typed as references.
|
||||
|
||||
Common variables:
|
||||
| Variable | Description |
|
||||
| ---- | ---- |
|
||||
| `sys.query` | Current user input question |
|
||||
| `formalized_content` | Sorted text results from Retrieval, SQL or tool components |
|
||||
| `content` | Main text output from Agent, Code or other components |
|
||||
|
||||
Operation Steps:
|
||||
1. Enter the Agent page and open the target canvas for editing.
|
||||
2. Select a component supporting variable references, e.g. Agent, Retrieval, Message, Code, HTTP Request, Execute SQL.
|
||||
3. On the right configuration panel, click the input box that needs variable reference, such as **System prompt**, **User prompt**, or **Query variables**.
|
||||
4. Open the variable selector via either method:
|
||||
- Type `/` inside the input box
|
||||
- Click the variable icon next to the input box (may display as `{}`, `+` or other icons in different versions)
|
||||
5. Select required variables in the selector. Available variables include:
|
||||
- System variables such as `sys.query`
|
||||
- Global variables defined in the Begin component
|
||||
- Output variables from upstream components
|
||||
6. After selection, the variable will be automatically inserted into the input box.
|
||||
7. Save component configuration and run the Agent to verify data transmission.
|
||||
|
||||

|
||||
## Canvas Toolbar
|
||||
|
||||
The buttons in the upper-right corner let you save, test, publish, and manage the workflow.
|
||||
|
||||
| Button | When and how to use it |
|
||||
| --- | --- |
|
||||
| Save draft | Save the configuration currently being edited. Check the **Autosaved** time below the workflow name to see the latest save. Saving a draft does not create a published version. |
|
||||
| Run | Open the test panel for the current workflow. In Conversational mode, enter a test question and inspect the response and component execution results. In Webhook mode, use the webhook test panel. Fix missing inputs or configuration errors before retrying. |
|
||||
| Launch | Open the conversation page to use the workflow in a full conversation view. This button is available in Conversational mode. It does not publish a version. |
|
||||
| Publish | Create a published version of the workflow. In the confirmation dialog, optionally enter an **Alias** to identify the version, then click **Confirm**. |
|
||||
| Checklist | Appears when configuration issues are detected. Open it to view issues grouped by component; click an issue to locate the affected component and correct it. The button disappears when there are no detected issues. |
|
||||
| Management | Open conversation variables, version history, logs, export, settings, and website embedding options. See the table below. |
|
||||
|
||||
### Management Menu
|
||||
|
||||
| Entry | What you can do |
|
||||
| --- | --- |
|
||||
| Conversation variable | Define and maintain variables used during a conversation. Use the variable selector in component fields to reference them. |
|
||||
| Version history | Browse saved version records and inspect their configurations. Use version information to identify the configuration you need; a history record alone does not mean that it is published. |
|
||||
| Log | Review workflow execution records. Search by **ID/Title** or date, open a record to inspect its state and version, or use **Export current page** to download the displayed records. |
|
||||
| Export | Download the current canvas configuration as JSON. See [Import and Export Workflows](./import_and_export_workflows.md). |
|
||||
| Settings | Change the workflow title, avatar, description, and access permissions for yourself or your team. Save the settings dialog to apply changes. |
|
||||
| Embed into webpage | Open the website embedding options and copy the integration code for your website. See [Embed a Workflow into Your Website](./embed_workflows_into_web_pages.md). |
|
||||
|
||||
### Test and Publish a Workflow
|
||||
|
||||
1. Finish configuring the components and their connections, then click **Save draft**.
|
||||
2. If **Checklist** appears, open it and resolve the reported issues.
|
||||
3. Click **Run**, supply the required test inputs, and review the response and component results. If output is missing, check input variables, model access, dataset permissions, and tool settings.
|
||||
4. Repeat the test with representative questions and edge cases until the results meet your needs.
|
||||
5. Click **Publish**, optionally enter an **Alias**, and click **Confirm**. Continue editing the draft when further changes are needed, and publish again to create another version.
|
||||
|
||||
## Component Connection Rules
|
||||
Connections define component execution order. Sequential components run along a single path. Branch components such as `Switch` and `Categorize` route workflows to different exits according to conditions. `Iteration` executes sub-processes in loops. Components not connected to the execution path will not run. Before deleting a component, check upstream/downstream connections and variable references to avoid missing inputs for subsequent nodes.
|
||||
|
||||
## Configuration Panel
|
||||
Click any canvas component to open the right-side configuration panel, which displays fields, input variables, output variables and execution settings. Recommended workflow: confirm which variable the component reads → configure processing logic → verify downstream nodes reference correct outputs.
|
||||
|
||||
For slow workflows, see [Improve Agent Response Time](./best_practices/accelerate_agent_question_answering.md).
|
||||
@@ -1,17 +1,17 @@
|
||||
---
|
||||
sidebar_position: 2
|
||||
title: Agent Overview
|
||||
sidebar_label: Agent Overview
|
||||
title: Workflow Overview
|
||||
sidebar_label: Workflow Overview
|
||||
slug: /agent_overview
|
||||
sidebar_custom_props: {
|
||||
categoryIcon: RagAiAgent
|
||||
}
|
||||
---
|
||||
|
||||
# Agent Overview
|
||||
# Workflow Overview
|
||||
|
||||
## Purpose of Agent
|
||||
Use Agent to build automated workflows by connecting components on a visual canvas. Connections define the execution order; conditions, categories, and loops control which steps run.
|
||||
## Purpose of Workflow
|
||||
Open **Agent > Workflow** to build automated workflows by connecting components on a visual canvas. Connections define the execution order; conditions, categories, and loops control which steps run.
|
||||
|
||||
Agents are commonly used in the following scenarios:
|
||||
- Answering user questions based on knowledge bases.
|
||||
@@ -13,7 +13,14 @@ sidebar_custom_props:
|
||||
|
||||
Multi-model comparison tests several models simultaneously with the same Chat configuration and the same question, then displays the answer generated by each model.
|
||||
|
||||
Select the models to compare, enter a test question, and run the comparison. Focus on whether each answer is accurate, whether it correctly uses knowledge base content, and how the answers differ between models.
|
||||
1. Open the Chat you want to test and click **Multiple models** above the conversation area.
|
||||
2. The comparison page initially displays one model panel. Click **+** in the last panel to add another. The counter beside **Multiple models** shows the number of panels; the current UI supports up to **3**.
|
||||
3. Use the model dropdown at the top of each panel to select the model for that panel. Configure the required model providers first if a model is not available.
|
||||
4. Enter one test question in the shared message box at the bottom, select **Naive** or **Agentic** as needed, and click **Send message**. The selected models receive the same question for comparison.
|
||||
5. Compare the answers side by side. Check accuracy, use of dataset evidence, completeness, and differences in the responses.
|
||||
6. To remove a panel, click its trash icon. This action is available when more than one panel is present. Click **Back** to return to the normal Chat view.
|
||||
|
||||
To use a panel's model configuration for the Chat, click its **Apply model configs** icon. This updates the Chat's saved model configuration; simply selecting a model for comparison does not apply it to the Chat.
|
||||
|
||||
|
||||
|
||||
@@ -27,5 +34,5 @@ Use representative questions from actual business scenarios instead of selecting
|
||||
Yes, we support enhancing user queries based on existing context of an ongoing conversation:
|
||||
|
||||
1. Open the desired Chat and click the settings icon in the upper-right corner.
|
||||
2. Expand **Advanced settings** in **Chat setting**.
|
||||
2. In **Chat setting**, expand **Advanced settings**, then expand **Naive**.
|
||||
3. Enable **Multi-turn optimization** and click **Save**.
|
||||
@@ -9,114 +9,120 @@ sidebar_custom_props:
|
||||
|
||||
# Chat Configuration
|
||||
|
||||
## Dataset Configuration
|
||||
Open a Chat from the **Chat** list, then click the gear icon on the right to open **Chat setting**. Configure the basic fields first, expand **Advanced settings** for additional options, and click **Save** to apply your changes. Use **Cancel** to discard unsaved changes.
|
||||
|
||||
Datasets determine the data scope that Chat can retrieve and cite. Only datasets that contain successfully parsed, available chunks can serve as valid knowledge sources.
|
||||
## Basic Configuration
|
||||
|
||||
- **Select dataset**: Associate one or more datasets in the **dataset** field. New or empty datasets generally do not appear in the selection list.
|
||||
- **Unavailable dataset**: If a dataset has been deleted or contains no available chunks, Chat indicates that the selected dataset is unavailable. Select another dataset.
|
||||
The top of **Chat setting** contains the Chat's name, avatar, description, **Model**, **Model settings**, **Opening greeting**, and **Datasets**.
|
||||
|
||||
:::tip NOTE
|
||||
For answers grounded in retrieved knowledge, consider retaining the `{knowledge}` placeholder in the system prompt.
|
||||
:::
|
||||
### Model
|
||||
|
||||
## Model
|
||||
Select the model used to generate answers. Available models depend on the provider instances configured for your account. Expand **Model settings** to adjust the generation parameters supported by the selected model. Start with the defaults and change one setting at a time while testing representative questions.
|
||||
|
||||
Select the large language model that understands questions and generates answers. Models differ in context length, reasoning capability, response speed, tool-calling capability, and cost.
|
||||
### Opening Greeting
|
||||
|
||||
Choose a model based on the use case. For routine dataset Q&A, prioritize response speed. For complex analysis or multi-document synthesis, select a model with stronger reasoning capabilities.
|
||||
Enter the message users see when starting a conversation. Briefly explain the Chat's purpose, the content it can answer questions about, and a few example questions. This greeting introduces the Chat; it does not set the rules for subsequent answers.
|
||||
|
||||
The available models depend on the models that have been added and configured in the current system.
|
||||
### Datasets
|
||||
|
||||
## Opening Greeting
|
||||
Select one or more datasets as the sources for retrieval. Prepare and parse documents before selecting a dataset: only datasets with available chunks can provide evidence for answers. If a selected dataset is unavailable or has been deleted, select another accessible dataset and save.
|
||||
|
||||
The opening greeting is the initial content shown when a user enters the Chat. Use it to briefly introduce the Chat's purpose, capability scope, usage, or example questions and help users begin a conversation.
|
||||
## Advanced Settings
|
||||
|
||||
An opening greeting can explain:
|
||||
Expand **Advanced settings** below **Datasets**. It contains shared options followed by separate **Naive** and **Agentic** groups. Expand the group for the mode you want to configure.
|
||||
|
||||
- The types of questions the Chat can answer.
|
||||
- The knowledge or business content on which its answers are based.
|
||||
- How users should phrase their questions.
|
||||
- Recommended examples or frequently asked questions.
|
||||
The groups configure how each mode works. To choose the mode for a question, use the selector beside the message box; expanding a group in the settings panel does not switch the conversation's mode.
|
||||
|
||||
The opening greeting primarily provides an introduction and guidance; it does not control subsequent answer behavior.
|
||||
### Shared Options
|
||||
|
||||
## System Prompt
|
||||
| Setting | Purpose and operation |
|
||||
| --- | --- |
|
||||
| Show citations | Display references to source content in answers so users can inspect the supporting evidence. Turn it off if citation display is not needed. |
|
||||
| Text to speech | Enable spoken playback of answers. Configure an available TTS model in **User settings > Model providers** before using this option. This field is a switch; it is not the model selector. |
|
||||
| Web search provider | Select the search service used when a user enables web search for a question. Complete the provider-specific API key field when required. See [Configure Web Search](#configure-web-search). |
|
||||
| Metadata | When available for the selected datasets, set metadata filters to narrow the documents searched. Check the selected datasets and their metadata fields before adding rules. |
|
||||
|
||||
The system prompt defines the Chat's role, tasks, and answer rules, and affects model behavior throughout the conversation.
|
||||
### Configure Web Search
|
||||
|
||||
Use it to specify the role, answer scope, language and tone, dataset usage, answer format, and how the Chat should handle missing information. For knowledge-base Q&A, explicitly instruct the model to prioritize dataset content and avoid filling in gaps or guessing when reliable evidence is unavailable.
|
||||
1. Open **Chat setting > Advanced settings**.
|
||||
2. In **Web search provider**, select the provider you want to use.
|
||||
3. Complete the API key field displayed for that provider. Fields marked as required must be filled in. Use the help link below the field if you need to obtain a key; providers that do not require a key can be used without one.
|
||||
4. Click **Save**.
|
||||
5. Return to the message box. Enable the globe-shaped web search control before sending a question that needs public web information. Turn it off when you want to ask without web search.
|
||||
|
||||
You can also require the Chat to:
|
||||
<img src="https://raw.githubusercontent.com/infiniflow/ragflow-docs/main/images/retrieval_augmentation_options_1.jpg" alt="Select a web search provider, enter its required API key, and save the Chat settings" width="520" />
|
||||
|
||||
- Answer in English, Chinese, or another specified language.
|
||||
- Keep answers concise and professional, or use a specified format.
|
||||
- State clearly when an answer cannot be confirmed from the available information.
|
||||
- Decline questions outside the scope of the current Chat.
|
||||
The screenshot uses Querit as an example. Select your own provider and complete the fields displayed for it.
|
||||
|
||||
Clearer prompts produce more stable behavior. Refine the prompt continuously based on testing, and avoid conflicting settings or overly complex rules.
|
||||
The web search control is shown only when a provider is configured and its required key is present. If the control is missing, reopen **Advanced settings**, check the provider and its required fields, and save again. A visible control means the configuration is present; a failed search can still require checking the key, provider quota, or network access.
|
||||
|
||||
## Retrieval Configuration
|
||||
Web search supplements the datasets selected for the Chat. Select a provider, complete its required fields, and save the configuration to make the web search control available. For providers that require an API key, the key must be nonblank. Users can then enable web search when asking a question.
|
||||
|
||||
Retrieval configuration controls how Chat recalls, filters, and ranks chunks from datasets. Tune these settings to balance retrieval scope, relevance, and response efficiency.
|
||||
## Naive Settings
|
||||
|
||||
- **Similarity threshold**: The minimum similarity score for retrieved content. A higher threshold is stricter and usually returns more relevant content, but may miss useful information. A lower threshold broadens recall but may introduce less relevant content.
|
||||
- **Keyword similarity weight**: Sets the full-text weight in hybrid retrieval; the vector weight is `1` minus this value. Increase it for exact keyword matching and decrease it for semantic matching.
|
||||
- **Rerank candidates**: The candidate pool used for ranking or reranking, with a default of `64` and a range of `64–256`. This controls the pool from which the final results are selected.
|
||||
- **Top N**: The maximum number of retrieved chunks used to generate the answer. A larger value provides more context but increases context length, response time, and cost. Tune it according to document scale and retrieval results.
|
||||
- **Rerank model**: Reranks retrieval results, calculates the relevance between candidate chunks and the question, and moves more relevant content forward for answer generation. Configure an available rerank model before using this option.
|
||||
- **Metadata**: Uses document or chunk metadata to limit the retrieval scope, such as by document type, date, or source.
|
||||
Expand **Advanced settings > Naive**. These fields configure the standard retrieval-and-answer flow. They do not replace the separate **Agentic template**.
|
||||
|
||||
## Empty Response
|
||||
### Empty Response
|
||||
|
||||
An empty response is preset content returned when the system cannot obtain enough information from a dataset, for example:
|
||||
Enter a fallback message for questions where retrieval finds no usable dataset content, for example:
|
||||
|
||||
> No relevant content was found in the dataset. Add more information and try again.
|
||||
> No relevant content was found in the dataset. Try a different question or add the missing information.
|
||||
|
||||
When retrieval returns no usable dataset content, Chat returns the preset response instead of continuing to generate an answer. This is useful when answers must be strictly grounded in a dataset and helps reduce unreliable output.
|
||||
Use this field when answers must be grounded in your datasets. Leaving it blank allows the model to continue generating an answer when retrieval finds no usable content. The fallback is based on retrieval results, not a guarantee that every generated answer is complete.
|
||||
|
||||
If no empty response is configured, the model may continue answering from its own knowledge when the dataset contains no relevant content.
|
||||
### Keyword Analysis
|
||||
|
||||
Choose a configuration according to the scenario:
|
||||
Enable **Keyword analysis** to extract keywords from the question to assist retrieval. This can help with product names, technical terms, and reference numbers. Compare the results with the option enabled and disabled using questions typical of your users.
|
||||
|
||||
- **Strictly use the dataset**: Configure an empty response for internal policies, customer service, compliance, product documentation, and other scenarios that depend heavily on dataset content.
|
||||
- **Allow the model to answer freely**: Leave it blank if answering from the model's own knowledge is acceptable.
|
||||
- **Guide the user's next action**: Include a clear instruction, such as adding information, trying again, or contacting an administrator.
|
||||
### System Prompt
|
||||
|
||||
An empty response is triggered only when retrieval finds no usable content. If any usable result exists, the system normally continues model generation; it does not decide based on whether the final answer is complete.
|
||||
Use **System prompt** to define the Naive mode's role, answer scope, language, format, and behavior when evidence is missing. For dataset-based Q&A, retain the `{knowledge}` placeholder so retrieved content can be inserted into the prompt.
|
||||
|
||||
The Thinking mode also affects this process. **Agentic** investigates the data with its own retrieval tools before answering, so it performs more retrieval and reasoning than **Naive** before returning an empty response. An empty response is returned only when the system ultimately determines that it cannot answer.
|
||||
For example, instruct the model to prioritize the supplied dataset content, cite evidence, and state when the available information does not answer the question. Avoid conflicting instructions. This field configures Naive mode; configure Agentic behavior under **Advanced settings > Agentic**.
|
||||
|
||||
### Retrieval Parameters
|
||||
|
||||
The following parameters appear after **System prompt** in the Naive group.
|
||||
|
||||
| Setting | How to use it |
|
||||
| --- | --- |
|
||||
| Similarity threshold | Set the minimum score for accepting retrieved content. Increase it to filter more strictly; decrease it if relevant content is being missed. |
|
||||
| Keyword similarity weight | Set the full-text weight in hybrid retrieval. The vector weight is `1 - keyword weight`. For example, `0.70` gives full-text a weight of `0.70` and vector retrieval `0.30`. Increase it for exact terms; decrease it to give semantic matching more weight. |
|
||||
| Rerank candidates | Set the candidate pool used for ranking or reranking. The default is `64`, within a range of `64–256`. This pool is separate from the final number of chunks used for the answer. |
|
||||
| Top N | Set the maximum number of retrieved chunks used for answer generation. More chunks provide more context but can increase response time and token usage. |
|
||||
| Rerank model | Select an available rerank model to reorder candidate chunks by relevance to the question. Configure the model provider before selecting it here. |
|
||||
|
||||
### Cross-Language Search
|
||||
|
||||
In **Cross-language search**, select the languages relevant to your documents. Use this when users ask questions in a different language from the dataset content, then test whether it improves retrieval for those questions.
|
||||
|
||||
### Multi-Turn Optimization
|
||||
|
||||
Enable **Multi-turn optimization** to use conversation history when refining the current retrieval query. This helps with follow-up questions that omit a name or refer to an earlier topic. Start a new conversation when changing to an unrelated topic.
|
||||
|
||||
### Variables
|
||||
|
||||
Use **Variable** to manage prompt variables. Keep the variable keys consistent with the placeholders used in **System prompt**, and set whether a variable is optional according to the inputs your application supplies.
|
||||
|
||||
## Agentic Settings
|
||||
|
||||
Expand **Advanced settings > Agentic** to configure the retrieval agent used by Agentic mode.
|
||||
|
||||
| Setting | How to use it |
|
||||
| --- | --- |
|
||||
| Decision model | Select an available decision model for Agentic processing. Configure the model under **User settings > Model providers** before selecting it here. |
|
||||
| Agentic template | Edit the instructions used by the Agentic retrieval agent for this Chat. Begin with the supplied template, then adjust its role, evidence requirements, and answer rules for your scenario. |
|
||||
| Reset to default | Restore the supplied Agentic template in the editor. Click **Save** to apply the restored template to the Chat. |
|
||||
|
||||
Agentic mode investigates the corpus with retrieval tools and can combine evidence across documents. It is suited to comparisons and questions that require several retrieval steps, and can take longer than Naive mode. Configure its instructions here rather than assuming that the Naive **System prompt** controls both modes.
|
||||
|
||||
## Select a Thinking Mode
|
||||
|
||||
Thinking mode determines how Chat investigates available data before answering.
|
||||
The mode selector is beside the message box. Before sending a question, open it and choose:
|
||||
|
||||
Before asking a question, select **Naive** or **Agentic** from the Thinking menu near the message box.
|
||||
|
||||
Retrieval means searching for evidence before answering. If a dataset is associated with the Chat, the system retrieves relevant chunks. If web search is enabled, or the current version provides PageIndex or Graph capabilities, those sources can also be used as supplemental evidence. The final answer should be based on the retrieved content.
|
||||
|
||||
- **Naive**: Performs retrieval without complex analysis. Use it for straightforward factual questions when identifiers, terms, or locations are clearly present in a document. It generally uses one query and responds fastest. It can be used together with empty responses and citations.
|
||||
- **Agentic**: Hands the turn to a retrieval agent that searches the corpus itself — locating passages, reading documents in depth, and combining evidence across several of them — before answering. Use it for cross-document questions, comparisons, and multi-step research. It takes longer and invokes the model more often.
|
||||
|
||||
If you are unsure which mode to choose, use **Naive** for straightforward questions or when speed is critical, and **Agentic** when the answer is incomplete or requires cross-document comparison.
|
||||
- **Naive** for straightforward factual questions and a standard retrieval-and-answer flow.
|
||||
- **Agentic** for questions requiring investigation, comparisons, or evidence across several documents.
|
||||
|
||||
|
||||
|
||||
## Retrieval Augmentation Options
|
||||
|
||||
Retrieval augmentation options further optimize queries or expand information retrieval beyond basic dataset retrieval. Enable them according to the actual question-answering scenario; you do not need to enable every option.
|
||||
|
||||
- **Keyword analysis**: Analyzes the user's question and uses the extracted keywords to assist retrieval. It is suitable for questions with distinctive keywords, such as product names, technical terms, and reference numbers.
|
||||
- **Multi-turn conversation optimization**: Uses the conversation history to optimize the current retrieval query, helping the system understand context, references, and omitted information in a continuous conversation. It is suitable for multi-turn conversations about the same topic.
|
||||
- **Cross-language search**: Improves retrieval across languages. When the question language differs from the language of the dataset documents, this option can improve the recall of cross-language content.
|
||||
|
||||
<img src="https://raw.githubusercontent.com/infiniflow/ragflow-docs/main/images/retrieval_augmentation_options_1.jpg" alt="Retrieval augmentation options" width="700" />
|
||||
|
||||
|
||||
|
||||
## Answer and Display Settings
|
||||
|
||||
Answer and display settings control how generated content is presented and output. They generally do not change the dataset retrieval scope, but affect how citations, metadata, and voice content are presented to users.
|
||||
|
||||
- **Show citations**: When enabled, Chat displays the dataset content cited in the answer and its source, allowing users to inspect the evidence and trace it to the original document. When disabled, citation information is not shown.
|
||||
- **Text-to-speech**: Select the model used to convert text answers to speech. Once configured, Chat can output generated text as speech. Leave it disabled if voice output is not needed. Before using this feature, configure an available text-to-speech (TTS) model.
|
||||
Selecting a mode chooses the flow for the question. Configure that flow in the corresponding **Naive** or **Agentic** settings group, save the Chat, and test both modes with representative questions. See [Using Chat conversations](./using_chat_sessions.md) for the message-box controls.
|
||||
@@ -19,19 +19,22 @@ After creating a Chat, configure its datasets, model, system prompt, and retriev
|
||||
|
||||
1. Select **Chat** in the top navigation bar.
|
||||
2. Click **Create chat**.
|
||||
|
||||
|
||||
|
||||
3. Enter a name for the Chat.
|
||||
4. Confirm the creation.
|
||||
5. Open **Chat setting**, then configure the datasets, model, system prompt, and retrieval parameters.
|
||||
|
||||
|
||||
|
||||
5. Click the gear icon on the right to open **Chat setting**. Configure **Model**, **Opening greeting**, and **Datasets**. Expand **Advanced settings** for shared options and the separate **Naive** and **Agentic** settings groups.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
6. Save the setting, then open the chat window to test and use the Chat.
|
||||
|
||||

|
||||
|
||||

|
||||
|
||||

|
||||
|
||||

|
||||
|
||||
You do not need to complete every setting when creating a Chat. You can return to the corresponding Chat from the Chat list and update its configuration later.
|
||||
|
||||
## Basic Information
|
||||
@@ -50,8 +53,11 @@ Complete the main Chat settings according to the actual scenario:
|
||||
|
||||
- **Dataset**: Select the dataset the Chat can retrieve from. When answering a question, the system searches for relevant content in the associated dataset.
|
||||
- **Model**: Select the large language model used to generate answers.
|
||||
- **Retrieval configuration**: Configure the similarity threshold, vector similarity weight, Top N, and other settings to control the retrieval scope and results.
|
||||
- **Advanced settings**: Use the options available in the current version to further tune answer generation and retrieval behavior.
|
||||
- **Naive settings**: Under **Advanced settings > Naive**, configure **System prompt**, **Similarity threshold**, **Keyword similarity weight**, **Top N**, and other retrieval options. Keyword similarity weight is the full-text weight; the vector weight is `1` minus this value.
|
||||
- **Shared options**: Under **Advanced settings**, configure **Show citations**, **Text to speech**, and **Web search provider**.
|
||||
- **Agentic settings**: Under **Advanced settings > Agentic**, configure **Decision model** and **Agentic template**.
|
||||
|
||||
These groups configure the two modes. Select **Naive** or **Agentic** beside the message box when asking a question. See [Chat Configuration](./chat_configuration.md) for the complete settings and web search prerequisites.
|
||||
|
||||
Save the setting and test it in the chat window.
|
||||
|
||||
|
||||
@@ -31,10 +31,22 @@ Use different conversations for different topics. For example, after discussing
|
||||
|
||||
Enter a question in the message box and press **Enter**, or click **Send**. Press **Shift+Enter** to insert a line break.
|
||||
|
||||
While an answer is being generated, click **Stop** to interrupt it. Before sending a question, you can select a Thinking mode, enable or disable web search, and add attachments.
|
||||
While an answer is being generated, click **Stop** to interrupt it. Before sending a question, select a Thinking mode, enable web search when available, or add attachments.
|
||||
|
||||
Chat generates an answer using the current conversation history together with the Chat's configured knowledge bases, model, and system prompt.
|
||||
|
||||
## Choose a Thinking Mode
|
||||
|
||||
Open the mode selector beside the message box and choose **Naive** or **Agentic** before sending a question. Use Naive for straightforward retrieval questions and Agentic for investigations or comparisons across documents.
|
||||
|
||||
The corresponding settings are under **Chat setting > Advanced settings > Naive** and **Agentic**. Expanding one of those settings groups does not select the mode for your question. See [Chat Configuration](./chat_configuration.md) to configure each flow.
|
||||
|
||||
## Use Web Search
|
||||
|
||||
When a web search provider is configured, the message box shows a globe-shaped web search control. Enable it before sending a question that needs public web information; turn it off when web search is not needed.
|
||||
|
||||
If the control is missing, open **Chat setting > Advanced settings > Web search provider**, select a provider, complete its required API key field, and click **Save**. Providers that require no key only need to be selected and saved. See [Configure Web Search](./chat_configuration.md#configure-web-search).
|
||||
|
||||
## Upload Files
|
||||
|
||||
Click the paperclip icon in the message box, or drag files into the message box, to send files with your question as attachments. Uploaded files appear above the message box; remove any unnecessary files before sending.
|
||||
|
||||
@@ -14,11 +14,16 @@ sidebar_custom_props: {
|
||||
|
||||
Creating a data source connection only saves the access configuration for the external system. To bring external content into a knowledge base, you also need to add that data source in the target knowledge base and start synchronization.
|
||||
|
||||
1. Enter the knowledge base page.
|
||||
2. Open the target knowledge base that needs to synchronize external content.
|
||||
3. In the data import or data source settings entry of the knowledge base, select the created data source connection.
|
||||
4. Follow the prompts on the knowledge base page to select the synchronization scope, parsing method, or chunking parameters.
|
||||
5. Save and start synchronization, then wait for the synchronization task to complete.
|
||||
1. Open **Dataset** and select the target Dataset.
|
||||
2. Open **Configuration** and find the **Data source** section.
|
||||
3. Click **Link data source**, select the existing connection, and click **Confirm**.
|
||||
4. Review the linked source and set **Auto parse** as needed. Configure the Dataset's **Parsing mode** and its parsing parameters separately on the same configuration page.
|
||||
5. Click **Save** to apply the Dataset configuration, including the data source association.
|
||||
6. Check synchronized documents on **Files** and synchronization records under **Logs > Data source**. Documents must complete parsing before their chunks are available for retrieval.
|
||||
|
||||
To change credentials, synchronization scope, or refresh intervals, open the connection under **User settings > Data sources**. These connection settings are separate from the Dataset's parsing settings.
|
||||
|
||||
|
||||
|
||||
## Synchronization and Updates
|
||||
|
||||
@@ -33,5 +38,3 @@ After synchronization is complete, users can retrieve and ask questions about th
|
||||
If changes to external content do not appear in the knowledge base immediately, first check the refresh interval, synchronization status, and data source logs.
|
||||
|
||||
Some data sources support the test connection feature. After saving or modifying a connection, you can test the connection first to confirm that account permissions, connection parameters, and data access are normal, and then start synchronization in the knowledge base.
|
||||
|
||||

|
||||
@@ -14,6 +14,8 @@ RAGFlow supports many data sources. It is recommended to first select a major ca
|
||||
|
||||
**Documents and collaboration platforms**: Used to synchronize team documents, wikis, cloud drive files, and collaborative documents. This category is suitable for building enterprise knowledge bases or project repositories. It includes Confluence, Notion, Feishu Wiki, Google Drive, OneDrive, SharePoint, Box, Dropbox, WebDAV, and SeaFile.
|
||||
|
||||
**Research libraries**: Use **Zotero** to synchronize PDF attachments from papers and references. Choose Zotero cloud or WebDAV according to where the attachments are stored.
|
||||
|
||||
**Object storage**: Used to synchronize large numbers of files in buckets or containers. This category is suitable for historical data archiving, batch file import, and centralized management of cloud files. It includes S3, Google Cloud Storage, Oracle Storage, R2, and Azure Blob Storage.
|
||||
|
||||
**Databases and data warehouses**: Used to synchronize structured records or query results. This category is suitable for business data Q&A, metric knowledge retention, and retrieval of data analysis results. It includes MySQL, PostgreSQL, and BigQuery.
|
||||
|
||||
@@ -419,17 +419,18 @@ The Azure DevOps data source is used to synchronize Azure Repos source files and
|
||||
|
||||
**Permission requirements**: The personal access token (PAT) must have the **Code (Read)** scope for the target organization.
|
||||
|
||||
**Account version requirements**: Both Azure DevOps Services (`dev.azure.com`) and self-hosted Azure DevOps Server are supported. For a self-hosted server, provide the full collection URL as the organization, for example `https://tfs.contoso.com/DefaultCollection`. The URL must use HTTPS, because the personal access token is sent in the `Authorization` header.
|
||||
**Account version requirements**: Both Azure DevOps Services (`dev.azure.com`) and self-hosted Azure DevOps Server are supported. For a self-hosted server, provide its service or collection URL as described below. HTTP and HTTPS URLs are accepted; use HTTPS to protect the personal access token sent in the `Authorization` header.
|
||||
|
||||
**Configuration parameters**:
|
||||
|
||||
- **Name**: Customize the name in RAGFlow to identify this Azure DevOps connection.
|
||||
- **Azure DevOps Personal Access Token**: The PAT used to access the organization.
|
||||
- **Azure DevOps Organization**: The organization name, or the collection URL of a self-hosted server.
|
||||
- **Index Mode**: Choose whether to index every repository in the organization, only selected team projects, or only selected repositories.
|
||||
- **Azure DevOps personal access token**: The PAT used to access the organization.
|
||||
- **Base URL**: For Azure DevOps Services, this is optional when an organization name is provided and defaults to `https://dev.azure.com`. For self-hosted Azure DevOps Server, provide the service URL here, or provide the full collection URL under **Azure DevOps organization**. If the organization field is empty, Base URL must include the collection path, for example `https://tfs.contoso.com/DefaultCollection`.
|
||||
- **Azure DevOps organization**: Enter the hosted organization name, the collection name to append to Base URL, or a full self-hosted collection URL. Leave it empty only when Base URL already includes the collection path. Explicit URLs must use `http://` or `https://`, include a valid host, and contain no query parameters, fragments, or embedded credentials. The same URL restrictions apply to Base URL.
|
||||
- **Index Mode**: Choose **Organization**, **Projects**, or **Repositories**. Organization indexes every repository visible to the token in the organization; the other modes show fields for narrowing the scope.
|
||||
- **Projects**: Comma separated team project names, used when indexing by project.
|
||||
- **Repositories**: Comma separated repositories, used when indexing by repository. Use `project/repo` to disambiguate repositories that share a name across projects.
|
||||
- **Content Types**: Choose whether to index source files, pull requests, or both.
|
||||
- **Content types**: Choose whether to index source files, pull requests, or both.
|
||||
|
||||
Pull request descriptions are re-fetched individually when they reach the 400 character limit imposed by the list endpoint, so long descriptions are indexed in full. Completed and abandoned pull requests are filtered by their close date; active ones are always re-indexed because Azure DevOps exposes no dependable "last updated" timestamp for them.
|
||||
- **Sync deleted files**: After this is enabled, content deleted from the external system is removed from the knowledge base index.
|
||||
@@ -774,49 +775,6 @@ The Feishu Wiki data source is used to synchronize downloadable file nodes from
|
||||
- **Batch size**: Set the number of files processed in each batch. The default value is **2**.
|
||||
|
||||
|
||||
## Azure DevOps
|
||||
|
||||
The Azure DevOps data source is used to synchronize source code and pull request content from Azure DevOps organizations, projects, or repositories to a RAGFlow knowledge base. The synchronization scope and content type can be configured as needed.
|
||||
|
||||
**Permission requirements**: The Azure DevOps personal access token must have read access to the target organization, project, or repository. Read access to pull requests is also required when pull request content is synchronized.
|
||||
|
||||
**Account version requirements**: An Azure DevOps account and a valid Personal Access Token (PAT) are required.
|
||||
|
||||
**Configuration parameters**:
|
||||
|
||||
- **Name**: Customize the name in RAGFlow to identify this Azure DevOps connection.
|
||||
- **Azure DevOps personal access token**: Fill in the Personal Access Token used to access Azure DevOps.
|
||||
- **Base URL**: Fill in the Azure DevOps service URL. The default value is `https://dev.azure.com`.
|
||||
- **Azure DevOps organization**: Fill in the Azure DevOps organization to access.
|
||||
- **Index mode**: Select the synchronization scope. The options are **Organization**, **Project**, and **Repository**.
|
||||
- **Organization**: Index all repositories visible to the token in the specified organization.
|
||||
- **Project**: Index content in a specified project. When selected, fill in the **Project** field.
|
||||
- **Repository**: Index a specified repository. When selected, fill in the **Repository** field.
|
||||
- **Project**: Fill this in when the index mode is **Project**.
|
||||
- **Repository**: Fill this in when the index mode is **Repository**.
|
||||
- **Content type**: Select the content to synchronize. The options are **Code**, **Pull requests**, and **Both**.
|
||||
- **Sync deleted files**: After this is enabled, content deleted from the external system is removed from the knowledge base index.
|
||||
|
||||
|
||||
## Xquik
|
||||
|
||||
The Xquik data source is used to search posts on X through Xquik and synchronize matching posts to a RAGFlow knowledge base. Search conditions, result ordering, and pagination settings can be configured to control the synchronized content.
|
||||
|
||||
**Permission requirements**: A valid Xquik API key with permission to access the corresponding search API is required.
|
||||
|
||||
**Account version requirements**: An account with access to the Xquik API is required. Available data and API usage limits depend on the Xquik service and account configuration.
|
||||
|
||||
**Configuration parameters**:
|
||||
|
||||
- **Name**: Customize the name in RAGFlow to identify this Xquik connection.
|
||||
- **Xquik API key**: Fill in the API key used to access Xquik.
|
||||
- **X search query**: Fill in the query used to search posts on X, for example, `ragflow lang:en`.
|
||||
- **Result order**: Select the order in which search results are returned, such as **Latest**.
|
||||
- **Posts per page**: Set the number of posts retrieved per page. The default value is **100**.
|
||||
- **Maximum pages**: Set the maximum number of result pages retrieved during synchronization. The default value is **10**.
|
||||
- **Batch size**: Set the number of posts processed in each batch. The default value is **32**.
|
||||
|
||||
|
||||
## WebDAV
|
||||
|
||||
The WebDAV data source is used to connect to a WebDAV server and synchronize files from a specified remote path to a RAGFlow knowledge base.
|
||||
@@ -871,3 +829,21 @@ The Salesforce data source is used to connect to Salesforce and synchronize reco
|
||||
- **API version**: Set the Salesforce API version to use. The default value in the current UI is `v59.0`.
|
||||
- **Batch size**: Set the number of records processed in each batch. The default value is **2**.
|
||||
- **Sync deleted files**: After this is enabled, content deleted from the external system is removed from the knowledge base index.
|
||||
|
||||
## Zotero
|
||||
|
||||
Use Zotero to synchronize PDF attachments from a Zotero library into a RAGFlow Dataset for retrieval and question answering about papers and references.
|
||||
|
||||
**Permission requirements**: Use a Zotero API key with read access to the target library. Attachment files must be downloadable from the selected storage service. For WebDAV, the account must have read access to the attachment storage.
|
||||
|
||||
**Configuration parameters**:
|
||||
|
||||
- **Name**: Enter a name that identifies this connection.
|
||||
- **Zotero user ID**: Enter the ID of the Zotero user whose library you want to synchronize.
|
||||
- **Zotero API key**: Enter the key used to read that library.
|
||||
- **Attachment storage**: Choose **Zotero cloud** for attachments stored in Zotero storage, or **WebDAV** for attachments stored on a WebDAV server.
|
||||
- When **WebDAV** is selected, complete the server URL, username, and password fields that appear. These fields are required for WebDAV storage.
|
||||
- **Batch Size**: Set the number of files processed per batch. The default is `4`.
|
||||
- **Sync deleted files**: Enable if files deleted from the source should also be removed from the Dataset index during synchronization.
|
||||
|
||||
Click **Test connection** with the completed settings, then **Confirm** to create the connection. Link it to a Dataset using [Add to a Knowledge Base and Sync](./add_to_knowledge_base_and_sync.md). Check synchronization logs and document parsing results on a small sample before importing a large library.
|
||||
@@ -24,7 +24,7 @@ The configuration page is used to maintain the core configuration of a dataset.
|
||||
|
||||
## Parsing Method
|
||||
|
||||
The parsing method determines how uploaded documents are processed into chunks. In **Parse mode**, select a built-in template or a saved ingestion pipeline from the same drop-down list.
|
||||
The parsing method determines how uploaded documents are processed into chunks. In **Parsing mode**, select a built-in template or expand a custom ingestion pipeline and select one of its published versions from the same dropdown.
|
||||
|
||||
### Built-in Parsing
|
||||
|
||||
@@ -40,6 +40,7 @@ The following built-in parsing methods are available:
|
||||
- **Book**: Designed for DOCX, PDF, and TXT books or other long documents with a chapter-based structure.
|
||||
- **Laws**: Designed for legal documents in DOCX, PDF, and TXT formats. Chunk boundaries are identified based on the structural characteristics of legal documents.
|
||||
- **Presentation**: Designed for presentations in PDF and PPTX formats. Each page or slide is typically treated as an individual chunk.
|
||||
- **Picture**: Processes image and video materials into searchable text using OCR and visual descriptions. Configure the relevant OCR or vision model for the content you want to process.
|
||||
- **One**: Treats the entire document as a single chunk. This method is suitable for relatively short documents when the complete context needs to be preserved.
|
||||
- **Audio**: An audio parsing method for audio files such as WAV, MP3, AAC, FLAC, and OGG. It uses an ASR model to transcribe audio into text and then generates chunks from the transcription.
|
||||
- **Email**: An email parsing method for email files such as EML and MSG. It extracts content including the sender, recipients, subject, body, and attachments, and generates chunks from the extracted content.
|
||||
@@ -133,14 +134,6 @@ For PPTX files mainly containing text and standard tables, consider starting wit
|
||||
|
||||
Parsing quality depends on slide layout, image quality, content complexity, and the selected method.
|
||||
|
||||
##### Video Parsing
|
||||
|
||||
Configure how video files are parsed. An external model recognizes and interprets speech, visuals, and other content, then converts the results into text for subsequent chunking and retrieval.
|
||||
|
||||
Select a configured external model with video or multimodal understanding capabilities. Video parsing supports only external models already configured in the system. Such a model can analyze video frames, visible text, speech, and contextual information to generate corresponding text.
|
||||
|
||||
Available models depend on the configured providers and their capabilities. Long videos, frequent scene changes, and complex content may increase processing time and model usage. External models may incur additional calls and token usage. Parsing quality depends on video quality, audio and visual clarity, content complexity, and the selected model.
|
||||
|
||||
##### Audio Parsing
|
||||
|
||||
Configure how audio files are parsed. An external model transcribes speech into text for subsequent chunking and retrieval.
|
||||
@@ -209,26 +202,28 @@ Group works well when continuity between nearby sections matters. It combines ad
|
||||
|
||||
#### Extractor Configuration
|
||||
|
||||
Open the **Extractor** tab to configure enrichment after chunking. Expand a function to view its settings and use the switch beside its name to enable it; expanding the section alone does not enable processing. The panel lists **Auto keywords**, **Auto-question**, **Tags**, **Summary**, and **Metadata**.
|
||||
|
||||
The Extractor adds information to chunks after chunking. It can use a model to generate keywords, questions, tags, contextual summaries, and metadata. These additions can improve subsequent retrieval and question answering.
|
||||
|
||||
##### Model
|
||||
|
||||
Select the model used by the Extractor. Automatic keywords, automatic questions, augmented context, and metadata that requires model generation call the selected model. Available models depend on the configured providers and their capabilities.
|
||||
Select the model used by the Extractor. Enabled keyword, question, summary, and metadata generation functions call the selected model. Available models depend on the configured providers and their capabilities.
|
||||
|
||||
##### Automatic Keywords
|
||||
##### Auto keywords
|
||||
|
||||
Automatically extract keywords or phrases that represent the main content of each chunk.
|
||||
|
||||
- **Number of automatic keywords:** Sets how many keywords are generated for each chunk. Set it to **0** to disable keyword extraction.
|
||||
- **Number of keywords to extract:** Sets how many keywords are generated for each chunk. Turn on the **Auto keywords** switch and set the required number. Turn the switch off to disable extraction.
|
||||
- **System prompt:** Sets the instruction sent to the model. The default prompt asks the model to analyze the text and extract the `{{ topn }}` most important keywords or phrases. You can adapt the prompt to specify keyword types, output language, or format.
|
||||
|
||||
Generated keywords add semantic information to chunks and can help with retrieval and content matching.
|
||||
|
||||
##### Automatic Questions
|
||||
##### Auto-question
|
||||
|
||||
Automatically generate questions that each chunk can answer. This adds query-like expressions to the content.
|
||||
|
||||
- **Number of automatic questions:** Sets how many questions are generated for each chunk. Set it to **0** to disable question generation.
|
||||
- **Auto-question number:** Sets how many questions are generated for each chunk. Turn on the **Auto-question** switch and set the required number. Turn the switch off to disable question generation.
|
||||
- **System prompt:** Sets the instruction sent to the model. The default prompt asks the model to understand the text and generate `{{ topn }}` questions related to its main content.
|
||||
|
||||
Generated questions should cover important information in the chunk without repeating the same meaning. They can make document content easier to match with users' natural-language questions.
|
||||
@@ -237,16 +232,16 @@ Generated questions should cover important information in the chunk without repe
|
||||
|
||||
Extract or match tags for chunks using a prepared tag file. Tags can classify knowledge content and add semantic information.
|
||||
|
||||
- **Number of automatically extracted tags:** Sets how many tags are extracted for each chunk. Set it to **0** to disable automatic tag extraction.
|
||||
- **Auto-tags:** Sets how many tags are extracted for each chunk. Enable the **Tags** switch to use this function; turn it off to disable processing.
|
||||
- **Tag file:** Selects the file used for tag extraction. The system matches or generates tags for chunks based on the selected tag collection.
|
||||
|
||||
Prepare a tag file suitable for the knowledge base before using this feature. A well-designed tag system can support content classification, retrieval, and filtering.
|
||||
|
||||
##### Augmented Context
|
||||
##### Summary
|
||||
|
||||
Generate a concise contextual summary for each chunk and add it as supplementary information. This helps a chunk retain essential background when viewed separately from its source document.
|
||||
|
||||
- **Enable augmented context:** Calls the selected model to generate contextual information from the chunk.
|
||||
- **Summary** switch: Enables the selected model to summarize chunk content. Turn it off when summaries are not required.
|
||||
- **System prompt:** Sets the instruction sent to the model. The default prompt asks for a concise summary faithful to the source content, without introducing information absent from it.
|
||||
|
||||
Augmented context is useful when a chunk may lose important background after splitting. For example, a chunk containing only a short passage can gain a summary of its subject and context, helping retrieval and model understanding.
|
||||
@@ -257,53 +252,51 @@ Enabling this feature increases model calls and token usage.
|
||||
|
||||
Add structured metadata to parsed content. Metadata describes document or chunk attributes and can be used for retrieval, filtering, and content management.
|
||||
|
||||
- **Enable metadata:** Extracts or generates metadata according to the configured fields.
|
||||
- **Metadata** switch: Enables extraction or generation according to the configured fields.
|
||||
- **Settings:** Opens the metadata generation settings, where you configure the fields to extract or generate.
|
||||
|
||||
Metadata generation settings provide the following options:
|
||||
|
||||
- **Generate:** Define metadata fields to generate. Add fields and configure their descriptions, types, and values. The system generates metadata based on these settings.
|
||||
- **Built-in parser template:** Use structured information already provided during parsing as a metadata source, without defining the same information again.
|
||||
- **Generation:** Define metadata fields to generate. Add fields and configure their descriptions, types, and values. The system generates metadata based on these settings.
|
||||
- **Built-in:** Enable predefined fields such as `update_time` and `file_name`.
|
||||
- **Add:** Add a metadata field with a name, description, type, and value according to your needs.
|
||||
|
||||
For example, you can add fields for document type, department, author, subject, date, or business category. Well-configured metadata lets you narrow subsequent searches with metadata conditions. Metadata generated by a model may incur additional model calls and token usage.
|
||||
|
||||
#### Indexer Configuration
|
||||
|
||||
Configure how chunks are indexed and written to the retrieval engine. You can use full-text search, vector search, or both, and specify which content field is indexed. The Indexer uses the embedding model configured for the knowledge base; you do not need to select one here.
|
||||
Indexer prepares chunks for the retrieval engine. **Search method** displays the methods configured for the selected parsing mode, such as **Embedding** and **Full-text**. Review these labels, then configure **Filename embedding weight** and **Field** below. The Indexer uses the embedding model configured for the Dataset; this panel has no separate embedding model selector.
|
||||
|
||||
- **Search methods:** Select one or more ways to index and retrieve chunks.
|
||||
- **Search method:** Displays **Embedding** and **Full-text** as labels. These are not selectable checkboxes in the current panel.
|
||||
- **Embedding:** Creates vector representations and a vector index for semantic retrieval. A relevant chunk may be retrieved even when the query does not use the same words as the source text.
|
||||
- **Full-text:** Creates a full-text index for keyword matching. This is useful for product codes, names, technical terms, code, and other content requiring exact matches.
|
||||
- **Embedding + Full-text:** Creates both vector and full-text indexes to support semantic and keyword matching.
|
||||
- **Filename embedding weight:** Sets the filename's weight in the vector representation. The filename contributes semantic information alongside the chunk content. A higher value gives it more influence. Increase the weight when filenames clearly express document topics; decrease it when filenames are random identifiers or have little meaning.
|
||||
- **Fields:** Specifies the content used for indexing and retrieval. Available fields are **Processed text**, **Questions**, and **Augmented context**.
|
||||
- **Field:** Selects the content to embed. Available fields are **Processed text**, **Questions**, and **Augmented context**.
|
||||
- **Processed text:** Indexes the chunk body produced by the Parser, Chunker, and other preceding steps. This is the most direct method and the default selection.
|
||||
- **Questions:** Indexes questions generated by the Extractor's Automatic Questions feature. A user's question can then match a pre-generated question, which is useful for question-answering knowledge bases. Configure automatic question extraction before using this field.
|
||||
- **Augmented context:** Indexes context generated by the Extractor instead of relying only on the original chunk content. This is useful when chunks need additional background for effective retrieval.
|
||||
- **Questions:** Indexes questions generated by the Extractor's **Auto-question** function. A user's question can then match a pre-generated question, which is useful for question-answering knowledge bases. Configure automatic question extraction before using this field.
|
||||
- **Augmented context:** Embeds the summary generated by the Extractor's **Summary** function. This is useful when chunks need additional background for effective retrieval.
|
||||
|
||||
For most knowledge bases, you can enable both **Embedding** and **Full-text** and index **Processed text**. If you have enabled Automatic Questions or Augmented Context, consider indexing **Questions** or **Augmented context** according to the types of queries you expect.
|
||||
Start with **Processed text**. To use **Questions**, first enable **Auto-question** in Extractor; to use **Augmented context**, enable **Summary**. Validate that the required content is generated before relying on it for retrieval.
|
||||
|
||||
### Custom Ingestion Pipeline
|
||||
|
||||
**Pipeline** means using a custom **Ingestion Pipeline** as the dataset's parsing method. It is suitable for scenarios that require custom document processing logic or complex processing flows.
|
||||
|
||||
The pipeline must be created and configured in **Agent > Ingestion Pipeline** in advance. In the dataset, you do not need to configure the processing nodes inside the pipeline again. You only need to select the created pipeline.
|
||||
Create and publish the pipeline in **Agent > Ingestion pipeline** before applying it to a Dataset. A saved draft alone is not selectable for parsing.
|
||||
|
||||
Usage:
|
||||
1. Configure the pipeline, click **Save draft**, and resolve any **Checklist** issues.
|
||||
2. Click **Publish** and confirm to create a version.
|
||||
3. Open the Dataset's **Configuration > Parsing mode**.
|
||||
4. Expand the custom pipeline and select the published version you want to use within the same dropdown. There is no separate Version selector. **No published versions** means you must publish the pipeline first. Entries marked **Built in** can be selected directly.
|
||||
5. Click **Save**, then parse a sample document to validate the result.
|
||||
|
||||
1. Create and configure an **Ingestion Pipeline** in **Agent > Ingestion Pipeline**.
|
||||
2. Go to **Dataset > Configuration** and select **Pipeline** as the parsing method.
|
||||
3. Select the pipeline to use from the pipeline list.
|
||||
4. Save the configuration. Afterward, documents in the dataset are processed according to the selected pipeline.
|
||||
|
||||
If no pipeline is currently available, you can use the entry provided in the pipeline area to go to **Agent** and create one.
|
||||
The Dataset retains its selected version when another version is published. To apply an update, select the new version in **Parsing mode**, save, and reparse the documents that need the updated processing. Existing chunks are not regenerated automatically.
|
||||
|
||||
> Note: For pipeline creation, node configuration, and flow orchestration, see [**Ingestion Pipeline**](../agent/ingestion_pipeline/create_ingestion_pipeline.md).
|
||||
|
||||
### Auto Metadata: Automatic Metadata Configuration
|
||||
|
||||
**Auto Metadata** is used to configure metadata automatically generated during document parsing. The system supports two types of metadata: **Generation** and **Built-in**. You can configure them separately as needed.
|
||||
Open **Extractor > Metadata > Settings** to configure metadata automatically generated during document parsing. Enable the **Metadata** switch for the settings to take effect during processing. The system supports two types of metadata: **Generation** and **Built-in**. You can configure them separately as needed.
|
||||
|
||||
> Note: Changes in **Metadata generation settings** only take effect for newly parsed documents later. They do not automatically update documents that have already completed parsing. To apply the new configuration to existing documents, parse the relevant documents again.
|
||||
|
||||
|
||||
@@ -16,7 +16,7 @@ Click **Create dataset** on the dataset list page, then complete the following s
|
||||
|
||||
1. Enter **Name**.
|
||||
2. Select an available **Embedding model**.
|
||||
3. In **Parse mode**, choose a built-in template, such as **General**, or an ingestion pipeline previously created in **Agent**. Built-in templates and saved pipelines appear in the same list.
|
||||
3. Open **Parsing mode** and select a built-in template, such as **General**, or expand an ingestion pipeline previously created in **Agent** and select the published version you want to use. Built-in templates and custom pipelines appear in the same dropdown. A saved pipeline draft cannot be selected for parsing; if the pipeline shows **No published versions**, publish a version in **Agent** first.
|
||||
4. Click **Save**, then review the dataset's **Configuration** before uploading documents.
|
||||
|
||||
## View Dataset List
|
||||
|
||||
@@ -45,14 +45,13 @@ Click **Add file** and select **Upload file** to upload documents from the local
|
||||
|
||||
### Add Documents from an Associated Data Source
|
||||
|
||||
If a dataset has already been associated with an external data source in configuration, documents in the data source can be added to the dataset from the document management page. After addition, the documents enter the dataset document list. They still need to complete parsing before generating chunks, metadata, and retrieval content.
|
||||
To import external content, link a configured data source to the target Dataset through **Configuration**. Synchronization brings source documents into the Dataset; parsing then generates the chunks used for retrieval.
|
||||
|
||||
Operation steps:
|
||||
|
||||
1. Go to the **Files** page of the target dataset.
|
||||
2. Click **Add file** and select the associated data source entry.
|
||||
3. Select the documents to add.
|
||||
4. Confirm the addition and view the document status in the document list.
|
||||
1. Open the target **Dataset** and select **Configuration**.
|
||||
2. Find the **Data source** section and click **Link data source**.
|
||||
3. Select the configured data source connection and click **Confirm**.
|
||||
4. Review the linked source and its parsing settings. For synchronization and updates, follow [Add a Data Source to a Knowledge Base and Synchronization and Updates](../data_source/add_to_knowledge_base_and_sync.md).
|
||||
5. Check synchronized documents and their parsing status on **Files**. Use **Logs > Data source** to inspect synchronization records.
|
||||
|
||||
### Add Documents from File
|
||||
|
||||
|
||||
@@ -19,7 +19,7 @@ Metadata may come from system built-in fields, automatic generation during parsi
|
||||
|
||||
In document management or document details, you can view and maintain metadata related to documents. Metadata is displayed in list form, including **Field**, **Type**, **Values**, and related operations.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
@@ -31,7 +31,18 @@ You can add metadata manually for documents. When adding metadata, you need to s
|
||||
|
||||
## Automatically Generate Metadata
|
||||
|
||||
After **Auto Metadata** is enabled in dataset configuration, the system can automatically generate metadata during document parsing according to the configured generation rules. Automatically generated metadata usually comes from document content, source information, or built-in parsing information.
|
||||
For a built-in parsing mode, configure automatic metadata through **Dataset > Configuration > Extractor > Metadata**.
|
||||
|
||||
1. Open the target Dataset and select **Configuration**.
|
||||
2. Open the **Extractor** tab and expand **Metadata**.
|
||||
3. Turn on the switch beside **Metadata**. Expanding the section alone does not enable generation.
|
||||
4. Click **Settings** to open **Metadata generation settings**.
|
||||
5. In **Generation**, click **Add** to define fields and their descriptions, types, and allowed values. In **Built-in**, enable predefined fields such as `update_time` and `file_name` as needed.
|
||||
6. Click **Save** in the dialog, then **Save** on the Dataset configuration page.
|
||||
|
||||
For metadata generated from document content, check that the Extractor's **Model** is available. See [Dataset configuration](./configuration.md) for the detailed settings.
|
||||
|
||||
If the Dataset uses a custom ingestion pipeline, configure metadata in that pipeline's [Transformer](../agent/ingestion_pipeline/configure_transformer_component.md), publish the updated version, then open **Dataset > Configuration > Parsing mode**, expand the pipeline, select the updated published version, and click **Save** to apply it.
|
||||
|
||||
Changes to auto metadata configuration only affect newly parsed documents. If you need to apply new metadata rules to existing documents, parse the relevant documents again.
|
||||
|
||||
|
||||
@@ -21,7 +21,7 @@ Retrieval testing can also help troubleshoot Q&A result problems. If the correct
|
||||
|
||||
The **Setting** area on the **Retrieval testing** page is used to adjust retrieval parameters for the current test. You can modify parameters and run tests repeatedly to compare recall results under different configurations. The main parameters include:
|
||||
|
||||
- **Similarity threshold**: Candidate chunks below this threshold are filtered out. Raising the threshold narrows the recall range and makes results stricter; lowering the threshold expands the recall range. The default value is `0.2`.
|
||||
- **Similarity threshold**: Candidate chunks below this threshold are filtered out. Raising the threshold narrows the recall range and makes results stricter; lowering the threshold expands the recall range. The default value displayed in the UI is `20`, meaning a threshold of 20%. Enter the percentage value shown by the control.
|
||||
- **Keyword similarity weight**: Sets the full-text weight in hybrid retrieval. For example, `0.7` means full-text weight `0.7` and vector weight `0.3`. Increase it for keyword matching; decrease it for semantic matching.
|
||||
- **Rerank model**: The reranking model used to further calculate relevance and sort candidate results. If no rerank model is selected, retrieval results combine keyword similarity and vector cosine similarity. If selected, reranking results participate in the comprehensive score. Using a rerank model may increase retrieval latency.
|
||||
- **Cross-language search**: Select one or more target languages so a query can match related content in other languages in the dataset. If no language is selected, retrieval is mainly performed in the current language.
|
||||
|
||||
@@ -31,7 +31,7 @@ RAGFlow file management lets you build your own file system through nested folde
|
||||
|
||||
After clicking **Add File** in the upper-right corner of the page, select **Upload File** to open the upload window. The upload control contains two tabs: **File** and **Folder**. You can select one or more files, or upload an entire folder.
|
||||
|
||||
|
||||
|
||||
|
||||
### Upload File
|
||||
|
||||
|
||||
@@ -18,8 +18,8 @@ Configuration steps:
|
||||
|
||||
1. Create or open an Ingestion Pipeline.
|
||||
2. Add and connect Parser, Chunker, Compiler, and Indexer.
|
||||
3. Open CompilerOperator and select the target CompilationTemplate from the template list.
|
||||
4. Check node connections and required parameters, and then save the Pipeline.
|
||||
3. Open **Compiler**, select the target template group under **Operator**, and choose an available compilation model.
|
||||
4. Check node connections and required parameters, click **Save draft**, then **Publish** and confirm to create a pipeline version.
|
||||
|
||||
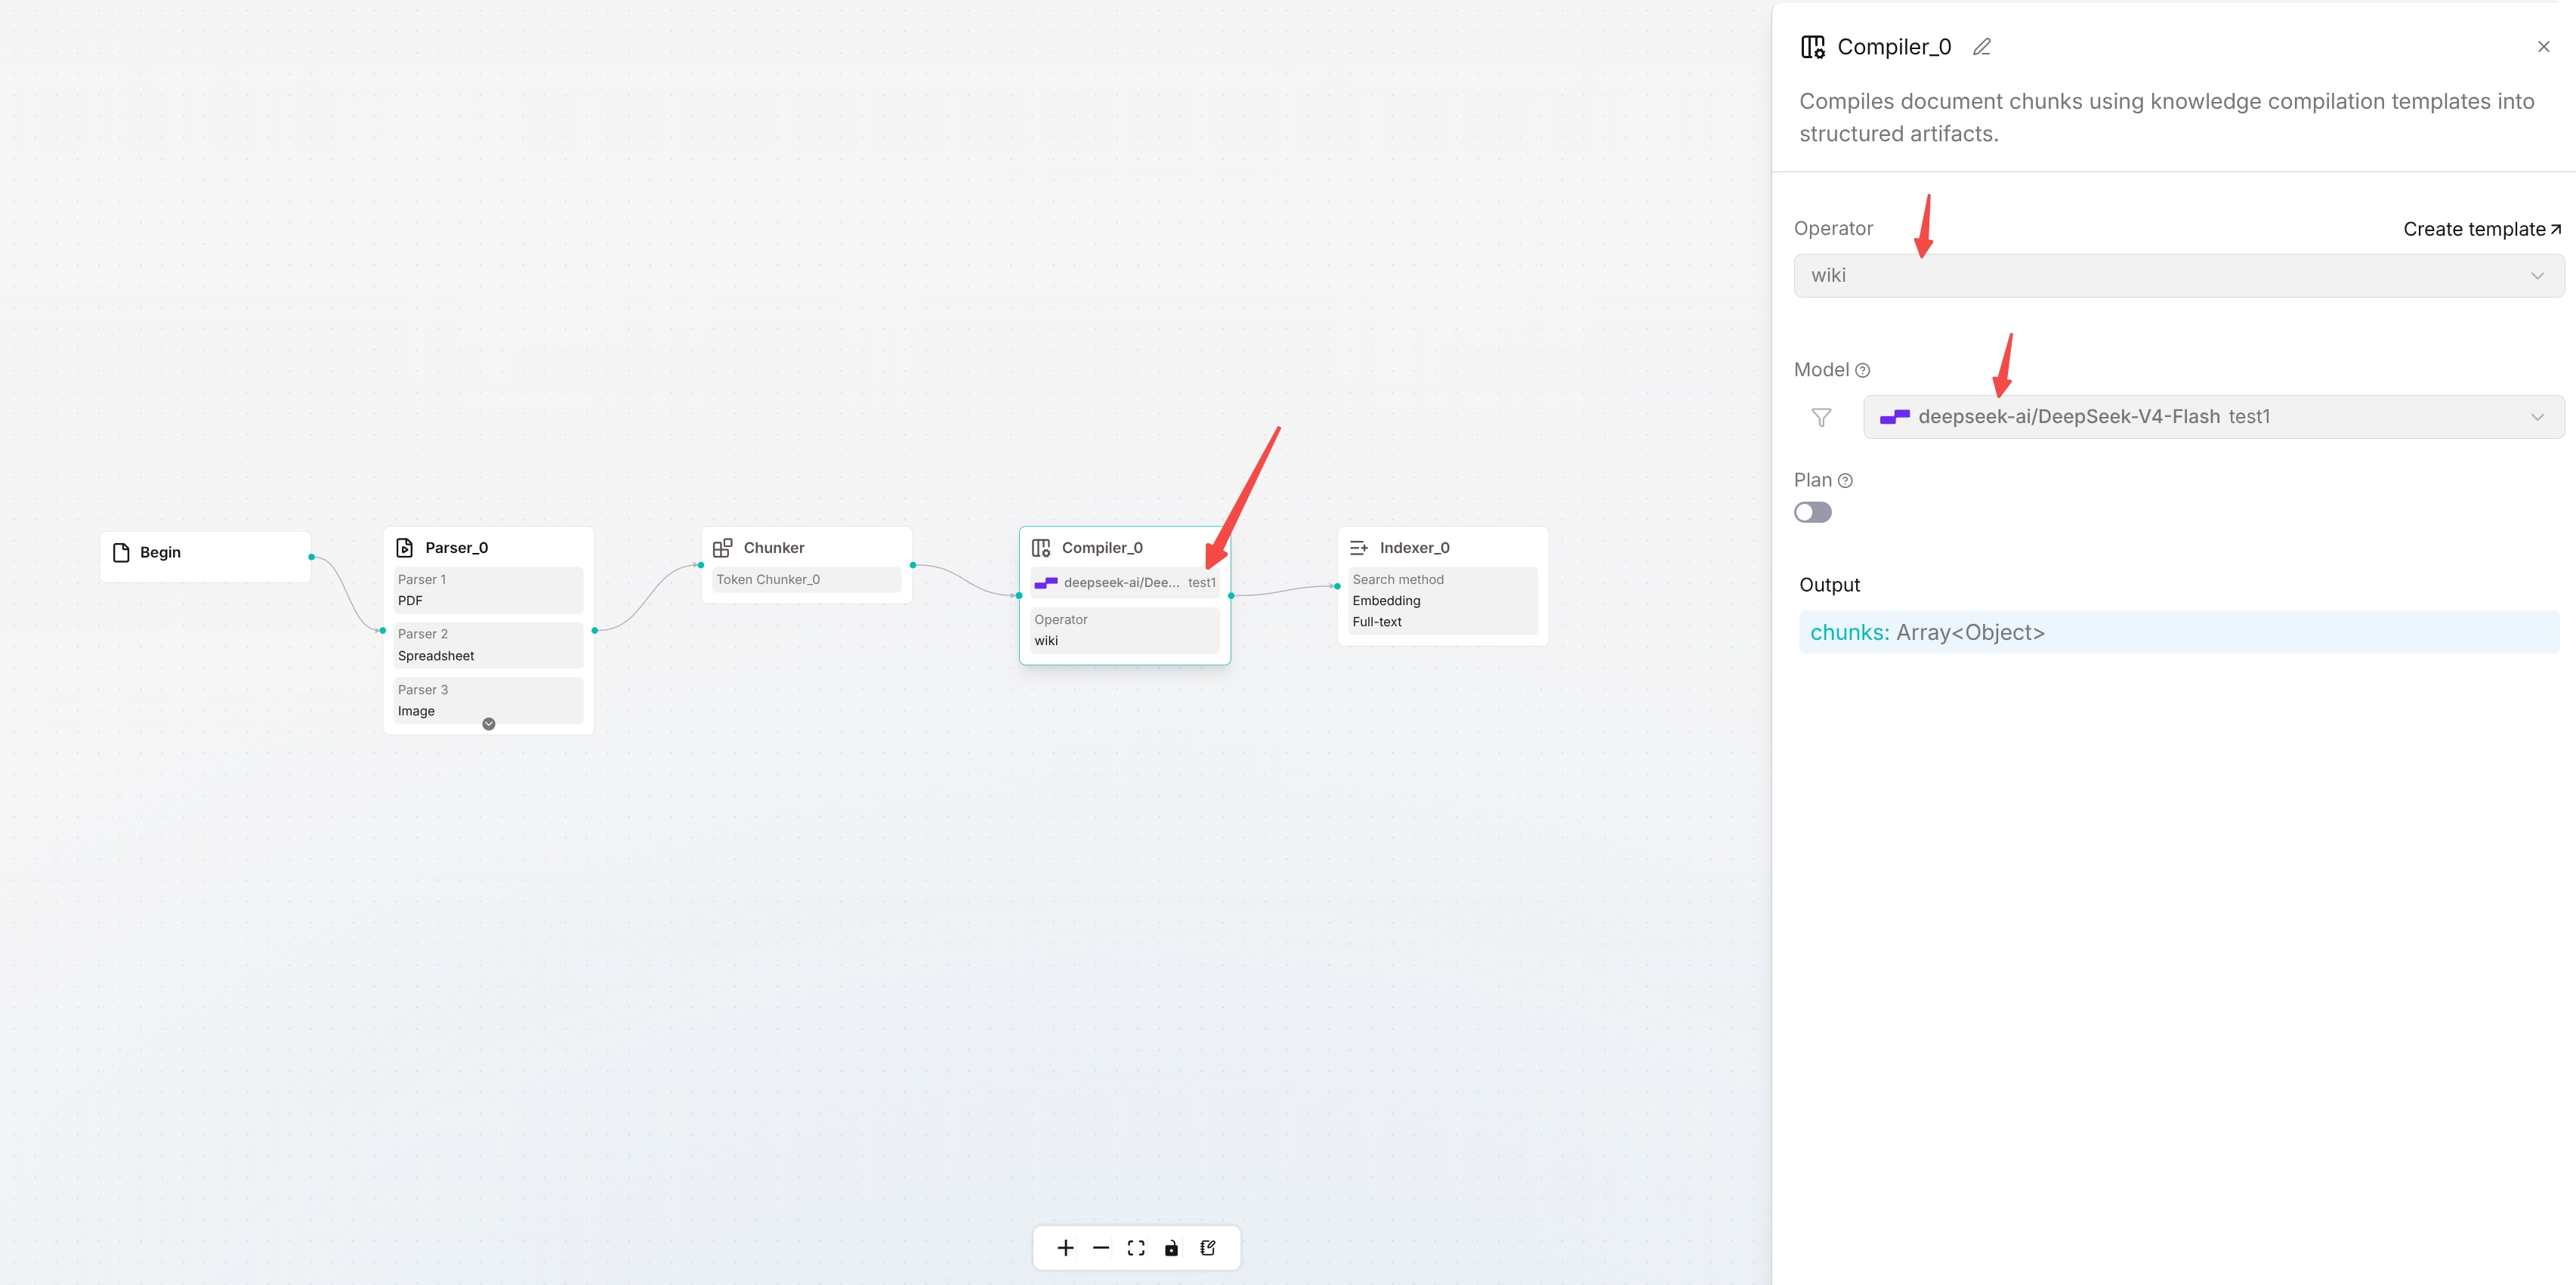
|
||||
|
||||
@@ -29,8 +29,8 @@ Note: CompilationTemplate only defines "how to compile". A KnowledgeArtifact is
|
||||
|
||||
1. Go to the Dataset page and create a Dataset or open an existing Dataset.
|
||||
2. Upload the documents to process.
|
||||
3. Open **Configuration** and find **Parse mode**.
|
||||
4. Select the Ingestion Pipeline that contains CompilerOperator and click **Save**.
|
||||
3. Open **Configuration** and find **Parsing mode**.
|
||||
4. Open **Parsing mode**, expand the ingestion pipeline that contains **Compiler**, select its published version within that dropdown, and click **Save**. If it shows **No published versions**, publish the pipeline first.
|
||||
5. Start parsing and check in the task logs whether Parser, Chunker, Compiler, and Indexer complete in sequence.
|
||||
|
||||

|
||||
@@ -39,11 +39,11 @@ If CompilationTemplate is modified, completed documents are not automatically re
|
||||
|
||||
## View Knowledge Artifacts
|
||||
|
||||
After knowledge compilation is complete, enter the corresponding knowledge base and select **Artifacts** from the left sidebar. In the upper-right corner of the Artifacts page, select the artifact type you want to view from the drop-down list, such as **Wiki**, **Tree/Page index**, **Graph**, **Mind map**, or **Timeline**, to view the corresponding generated results.
|
||||
After knowledge compilation is complete, enter the corresponding knowledge base and select **Artifacts** from the left sidebar. In the upper-right corner of the Artifacts page, select the artifact type you want to view from the drop-down list, such as **Wiki**, **Tree/Page index**, **Graph**, **Mindmap**, or **Timeline**, to view the corresponding generated results.
|
||||
|
||||
Knowledge artifacts can be divided by generation scope into document-level and knowledge-base-level artifacts:
|
||||
|
||||
- **Document-level knowledge artifacts**: Graph, Tree, PageIndex, MindMap, and Timeline can generate corresponding document-level results. Click a file name in the files list to view its artifacts.
|
||||
- **Document-level knowledge artifacts**: Graph, Tree, PageIndex, Mindmap, and Timeline can generate corresponding document-level results. Click a file name in the files list to view its artifacts.
|
||||
|
||||
- **Knowledge-base-level knowledge artifacts**: After a document completes a Pipeline that produces compilation results, the system automatically schedules the corresponding knowledge-base-level processing. Wiki pages are generated and merged from the document-level Wiki compilation results in the background. Open **Artifacts > Wiki** to view the results when processing is complete.
|
||||
|
||||
@@ -60,7 +60,7 @@ For different knowledge artifact types, focus on the following checks:
|
||||
| Graph | Whether entities are duplicated; whether relationship directions are correct; whether there are unsupported nodes or edges. |
|
||||
| Tree | Whether the hierarchy is clear; whether peer nodes are at similar abstraction levels; whether summaries are accurate. |
|
||||
| PageIndex | Whether chapter hierarchy is preserved; whether facts and conclusions come from the corresponding chapters. |
|
||||
| MindMap | Whether the central topic is clear; whether branches are duplicated or crossed; whether node names are concise. |
|
||||
| Mindmap | Whether the central topic is clear; whether branches are duplicated or crossed; whether node names are concise. |
|
||||
| Timeline | Whether time is accurate; whether event order is correct; whether relative time is misinterpreted. |
|
||||
| Wiki | Whether page topics are reasonable; whether links between pages are valid; whether facts are consistent with sources. |
|
||||
|
||||
|
||||
@@ -10,7 +10,7 @@ sidebar_custom_props: {
|
||||
|
||||
# Basic Information Configuration
|
||||
|
||||
When creating or editing a knowledge compilation template, you need to complete the basic information configuration first. Basic information determines the template name, the model used, and the basic compilation method. All knowledge compilation template types include these configuration items.
|
||||
When creating or editing a knowledge compilation template, you need to complete the basic information configuration first. Basic information determines the template name and the basic compilation method. Select the extraction model separately in the pipeline's Compiler component. All knowledge compilation template types include these configuration items.
|
||||
|
||||
## Template Name
|
||||
|
||||
@@ -20,11 +20,17 @@ Sets the name of the knowledge compilation template so different templates can b
|
||||
|
||||
The template description explains the function, applicable scenarios, and main processing content of the current template, making later viewing and management easier.
|
||||
|
||||
## Default Extraction Model
|
||||
## Open the Template Editor
|
||||
|
||||
The default extraction model specifies the model used during knowledge compilation. The system uses this model to understand and analyze document content, and completes information extraction and structured generation according to the rules defined in the template.
|
||||
1. Open **Agent** and select **Compilation operator**.
|
||||
2. Choose **Create from blank**. The **Add template** page opens directly.
|
||||
|
||||
Select an appropriate model based on actual business requirements and model capabilities. You can refer to the related description in the "Template Selection Recommendations" section.
|
||||
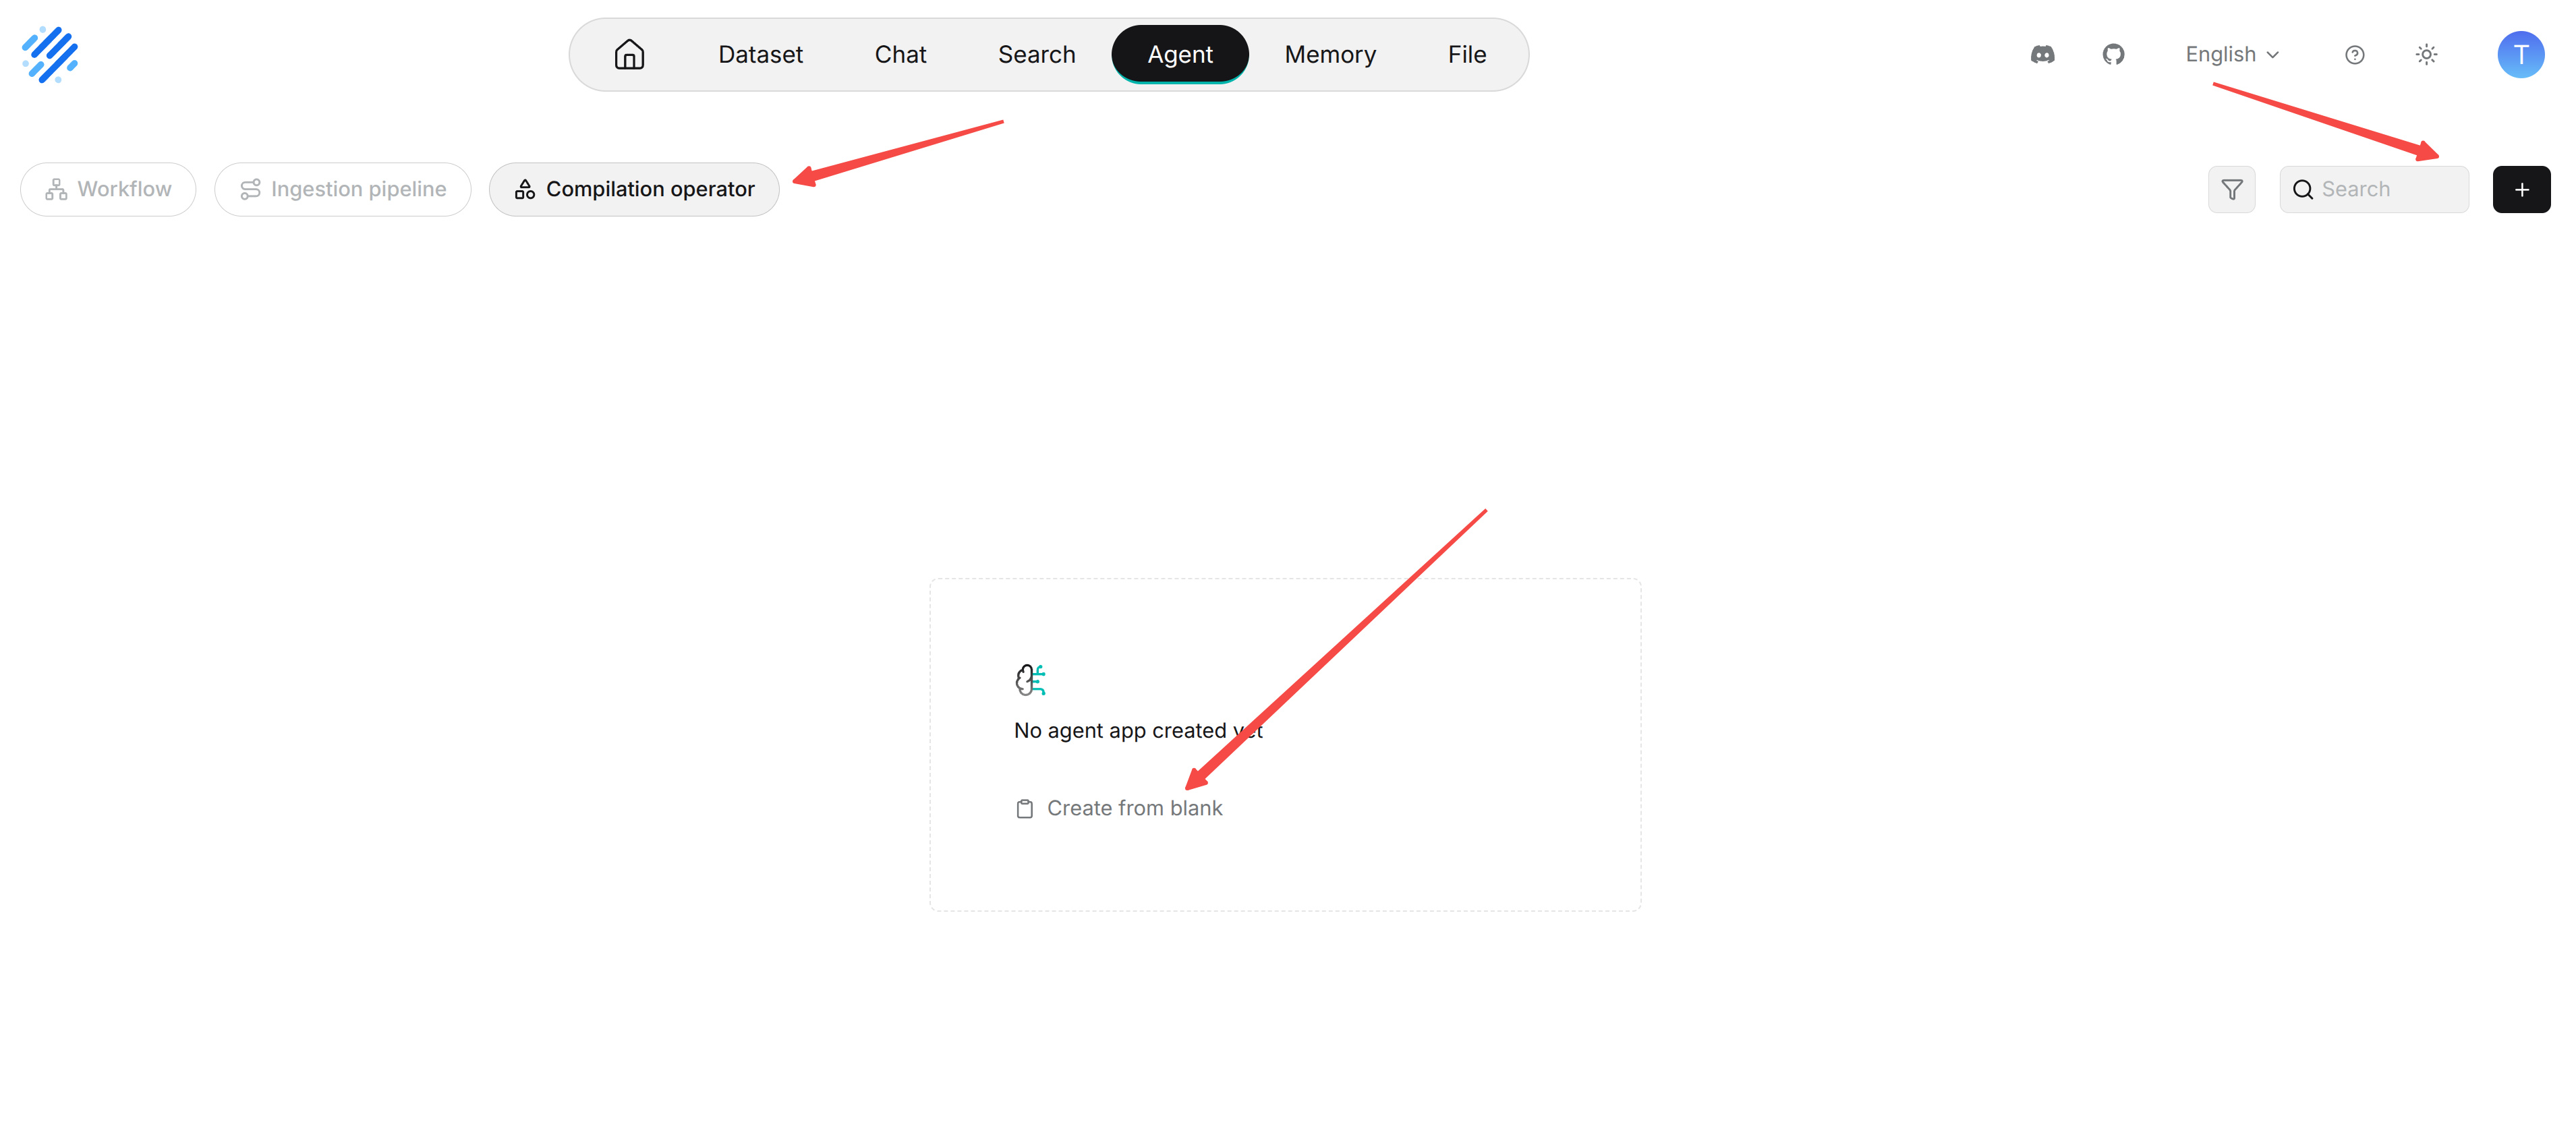
|
||||
|
||||
3. Enter **Name**, optionally enter **Description**, then choose **Template**.
|
||||
4. Complete **Global rules** and the settings that appear for the selected template type, then click **Save**. Use **Back** to return to the list without saving a new template.
|
||||
|
||||
Select the saved template group under **Operator** in the pipeline's **Compiler** component. Configure the compilation model there.
|
||||
|
||||
## Template
|
||||
|
||||
@@ -33,7 +39,7 @@ Selects the knowledge artifact type to generate through knowledge compilation. T
|
||||
- Graph
|
||||
- Tree
|
||||
- PageIndex
|
||||
- MindMap
|
||||
- Mindmap
|
||||
- Timeline
|
||||
- Wiki
|
||||
|
||||
@@ -45,14 +51,12 @@ Sets the requirements that the current knowledge compilation template must follo
|
||||
|
||||
The content controlled by global rules differs between templates. For example, Graph can use global rules to constrain entity and relationship extraction, while Wiki can use global rules to control content organization and generation requirements. For specific configuration methods, refer to the corresponding template chapter.
|
||||
|
||||
## Re-Split Parser Output
|
||||
## Re-chunk parser output
|
||||
|
||||
Controls whether Compiler reorganizes and splits Parser output before executing knowledge compilation.
|
||||
For Graph, Mindmap, PageIndex, and Timeline templates, **Re-chunk parser output** controls whether source chunks are regrouped before compilation. Turn it on to show **Rechunking rules** and review or edit the grouping instructions. Specify how adjacent chunks may be combined and how topic and section boundaries should be preserved. The supplied rules preserve source order and require every source chunk to be used exactly once.
|
||||
|
||||
After this option is enabled, Compiler reorganizes Parser output based on the processing requirements of the current knowledge compilation template before executing subsequent knowledge compilation. If disabled, compilation is performed directly based on Parser output.
|
||||
These settings affect compilation and do not replace the Chunker component. Click **Save** to save the template, then reparse a sample with the pipeline that references it to check the result.
|
||||
|
||||
This setting only affects the knowledge compilation process and does not replace Chunker in the Ingestion Pipeline.
|
||||
|
||||
Whether this feature is enabled must be determined when configuring the knowledge compilation template. After the template is saved, the setting takes effect when the template is used for knowledge compilation.
|
||||
Tree has its own **Re-chunk by tree leaves** setting; Wiki does not show the shared **Re-chunk parser output** control. See [template-specific configuration](./built_in_templates_and_dedicated_configuration.md) for the settings available to each type.
|
||||
|
||||
|
||||
+28
-4
@@ -19,7 +19,7 @@ Graph configuration mainly includes:
|
||||
- Global rules
|
||||
- EntitySpecification
|
||||
- RelationSpecification
|
||||
- Re-splitting Parser output
|
||||
- Re-chunk parser output
|
||||
|
||||
### Global Rules
|
||||
|
||||
@@ -33,6 +33,14 @@ Configuration recommendations:
|
||||
|
||||
Example: Extract only core people, organizations, products, and key events from the document. Keep entity names complete and do not generate entities that cannot be confirmed.
|
||||
|
||||
### Re-chunk parser output
|
||||
|
||||
Enable **Re-chunk parser output** to group related source content before entity and relationship extraction. Turning it on displays **Rechunking rules**, where you can review or edit the instructions for regrouping adjacent source chunks.
|
||||
|
||||
The supplied rules preserve source order, use every source chunk exactly once, and keep self-contained tables, lists, figures, and code blocks intact. Adjust the rules for your documents while preserving the source evidence. When the switch is off, compilation uses the existing source chunks without this regrouping step.
|
||||
|
||||
Click **Save** to save the template, then reparse a sample with the pipeline that references it and check the Graph result. This setting affects compilation input and does not replace the pipeline's Chunker component.
|
||||
|
||||
### EntitySpecification
|
||||
|
||||
EntitySpecification defines the entity types that need to be recognized in the knowledge graph. Click an entity type card to enter the entity configuration page.
|
||||
@@ -241,9 +249,9 @@ Supported operations:
|
||||
|
||||
|
||||
|
||||
## MindMap
|
||||
## Mindmap
|
||||
|
||||
MindMap generates a hierarchical structure around the core topic of a document, displaying content relationships through a central topic, branches, and keywords. It helps users quickly understand the main content, knowledge structure, and concept relationships of a document.
|
||||
Mindmap generates a hierarchical structure around the core topic of a document, displaying content relationships through a central topic, branches, and keywords. It helps users quickly understand the main content, knowledge structure, and concept relationships of a document.
|
||||
|
||||
### Global Rules
|
||||
|
||||
@@ -257,6 +265,14 @@ Configuration recommendations:
|
||||
- Maintain clear hierarchical relationships and avoid duplicate or circular references.
|
||||
- Keep node language consistent with the original text.
|
||||
|
||||
### Re-chunk parser output
|
||||
|
||||
Enable **Re-chunk parser output** to group related source content before extracting topics and branches. Turning it on displays **Rechunking rules**, where you can review or edit the instructions for regrouping adjacent source chunks.
|
||||
|
||||
The supplied rules preserve source order, use every source chunk exactly once, and keep self-contained tables, lists, figures, and code blocks intact. Adjust the rules for your documents while preserving the source evidence. When the switch is off, compilation uses the existing source chunks without this regrouping step.
|
||||
|
||||
Click **Save** to save the template, then reparse a sample with the pipeline that references it and check the Mindmap result. This setting affects compilation input and does not replace the pipeline's Chunker component.
|
||||
|
||||
### EntitySpecification
|
||||
|
||||
EntitySpecification defines the node types in the mind map. Different node types correspond to information content at different levels. Users can adjust the default nodes provided by the system based on business requirements, including deleting existing nodes or adding custom nodes.
|
||||
@@ -322,7 +338,7 @@ Recommendations:
|
||||
- Node names should be short and clear for final display.
|
||||
- Adjust node definitions based on document type. For example, technical documents can add types such as "module" and "function", while business documents can add types such as "process" and "role".
|
||||
|
||||
|
||||

|
||||
|
||||
## Timeline
|
||||
|
||||
@@ -343,6 +359,14 @@ The system provides the following default rules:
|
||||
|
||||
Users can adjust rules based on actual business requirements, such as specifying event types to focus on, limiting the time range, or supplementing domain-specific requirements.
|
||||
|
||||
### Re-chunk parser output
|
||||
|
||||
Enable **Re-chunk parser output** to group related source content before extracting dates and events. Turning it on displays **Rechunking rules**, where you can review or edit the instructions for regrouping adjacent source chunks.
|
||||
|
||||
The supplied rules preserve source order, use every source chunk exactly once, and keep self-contained tables, lists, figures, and code blocks intact. Adjust the rules for your documents while preserving the source evidence. When the switch is off, compilation uses the existing source chunks without this regrouping step.
|
||||
|
||||
Click **Save** to save the template, then reparse a sample with the pipeline that references it and check the Timeline result. This setting affects compilation input and does not replace the pipeline's Chunker component.
|
||||
|
||||
### EntitySpecification
|
||||
|
||||
Entity configuration defines the information types that need to be recognized and extracted in Timeline.
|
||||
|
||||
@@ -24,13 +24,13 @@ Check the following items in sequence:
|
||||
- Whether Compiler has selected the correct knowledge compilation template.
|
||||
- Whether the knowledge compilation task executed successfully.
|
||||
- Whether the knowledge compilation template has been correctly configured and saved.
|
||||
- Whether the default extraction model can be used normally.
|
||||
- Whether the model selected under **Model** in **Compiler** can be used normally.
|
||||
|
||||
If the task execution fails, use the task execution logs to further check the specific cause.
|
||||
|
||||
## 3. Why is the generated knowledge artifact incomplete or inconsistent with expectations?
|
||||
|
||||
The generation result of a knowledge artifact is affected by factors such as the original document content, selected template, default extraction model, and template configuration.
|
||||
The generation result of a knowledge artifact is affected by factors such as the original document content, selected template, model selected under **Model** in **Compiler**, and template configuration.
|
||||
|
||||
It is recommended to first check whether the parsing result of the original document is complete. Then adjust the global rules and the configuration parameters of the corresponding template based on the generated result, and execute knowledge compilation again.
|
||||
|
||||
@@ -40,17 +40,17 @@ No. After modifying template configuration, you need to use the updated template
|
||||
|
||||
## 5. Can I use different knowledge compilation templates for the same document?
|
||||
|
||||
Yes. You can select different knowledge compilation templates based on actual usage scenarios to generate different types of knowledge artifacts, such as Graph, Tree, PageIndex, MindMap, or Timeline.
|
||||
Yes. You can select different knowledge compilation templates based on actual usage scenarios to generate different types of knowledge artifacts, such as Graph, Tree, PageIndex, Mindmap, or Timeline.
|
||||
|
||||
Different templates have different knowledge organization methods and applicable scenarios. For details, refer to the template selection recommendations.
|
||||
|
||||
## 6. What is the difference between "Re-Split Parser Output" and Chunker?
|
||||
## 6. What is the difference between "Re-chunk parser output" and Chunker?
|
||||
|
||||
Re-Split Parser Output controls whether Compiler reorganizes and splits Parser output based on the processing requirements of the current template before knowledge compilation.
|
||||
**Re-chunk parser output** regroups source chunks before compilation for templates that expose this switch. Enabling it displays **Rechunking rules**. Tree uses **Re-chunk by tree leaves** instead, and Wiki does not show the shared switch.
|
||||
|
||||
Chunker is used for document chunk processing in the Ingestion Pipeline.
|
||||
|
||||
They act at different processing stages. Re-Split Parser Output does not replace Chunker.
|
||||
They act at different processing stages. Re-chunk parser output does not replace Chunker.
|
||||
|
||||
## 7. Why do results differ when the same document uses different models?
|
||||
|
||||
@@ -62,4 +62,4 @@ Different models may differ in understanding capability, context length, and gen
|
||||
|
||||
It is recommended to first confirm whether the original document parsing result is correct.
|
||||
|
||||
If the parsing result is normal, check and adjust the default extraction model, global rules, and specific configuration parameters of the current template in sequence. After adjustment, execute knowledge compilation again and compare whether the new knowledge artifact meets expectations.
|
||||
If the parsing result is normal, check and adjust the model selected under **Model** in **Compiler**, global rules, and specific configuration parameters of the current template in sequence. After adjustment, execute knowledge compilation again and compare whether the new knowledge artifact meets expectations.
|
||||
@@ -17,7 +17,7 @@ Generated knowledge artifacts can be used for knowledge retrieval, intelligent Q
|
||||
- **Knowledge graph**: Displays entities in documents and their relationships. It is suitable for content such as personal relationships, organizational structures, and product relationships.
|
||||
- **Knowledge tree**: Organizes document content by hierarchy. It is suitable for chapter structures, topic classification, and knowledge system organization.
|
||||
- **Page index**: Preserves the original document structure and enhances chapter positioning. It is suitable for manuals, specifications, reports, and similar materials.
|
||||
- **Mind map**: Expands content relationships around core topics and helps users quickly understand the overall document structure.
|
||||
- **Mindmap**: Expands content relationships around core topics and helps users quickly understand the overall document structure.
|
||||
- **Timeline**: Organizes event information in chronological order. It is suitable for historical materials, project records, event tracking, and similar content.
|
||||
- **Knowledge page**: Generates interconnected knowledge pages. It is suitable for enterprise knowledge, product materials, and domain knowledge management.
|
||||
|
||||
@@ -40,7 +40,7 @@ Knowledge compilation provides multiple built-in templates. Different templates
|
||||
| Graph | Suitable for extracting entities and relationships between entities in documents, such as people, organizations, products, and their relationships. |
|
||||
| Tree | Suitable for organizing document content by topic and hierarchy, arranging knowledge into a tree structure. |
|
||||
| PageIndex | Suitable for preserving the original chapter and page structure of a document and building a hierarchical index for quick content positioning and retrieval. |
|
||||
| MindMap | Suitable for extracting core topics and branch content from documents and displaying the knowledge structure as a mind map. |
|
||||
| Mindmap | Suitable for extracting core topics and branch content from documents and displaying the knowledge structure as a mind map. |
|
||||
| Timeline | Suitable for documents that contain clear time information and events, organizing and displaying events in chronological order. |
|
||||
| Wiki | Suitable for documents with substantial content and relationships between topics, organizing the content into interconnected Wiki pages. |
|
||||
|
||||
@@ -59,17 +59,11 @@ Recommendation: When using this feature for the first time, select a small numbe
|
||||
|
||||
## Standard Workflow
|
||||
|
||||
1. **Create a knowledge compilation template**: On the Agent page, select **Compilation Operator** when creating a new Agent. Then create a template based on the type of knowledge artifact to generate and complete the related parameter configuration.
|
||||
2. **Configure the Ingestion Pipeline**: Add Compiler to the Ingestion Pipeline and select the created knowledge compilation template.
|
||||
3. **Apply the Ingestion Pipeline**: In Dataset, select the documents to process and apply the configured Ingestion Pipeline.
|
||||
4. **Execute knowledge compilation**: The system parses documents according to the Pipeline configuration and generates the corresponding knowledge artifacts based on the selected template.
|
||||
5. **View knowledge artifacts**: After compilation is complete, view generated artifacts such as Graph, Tree, PageIndex, MindMap, Timeline, or Wiki.
|
||||
|
||||
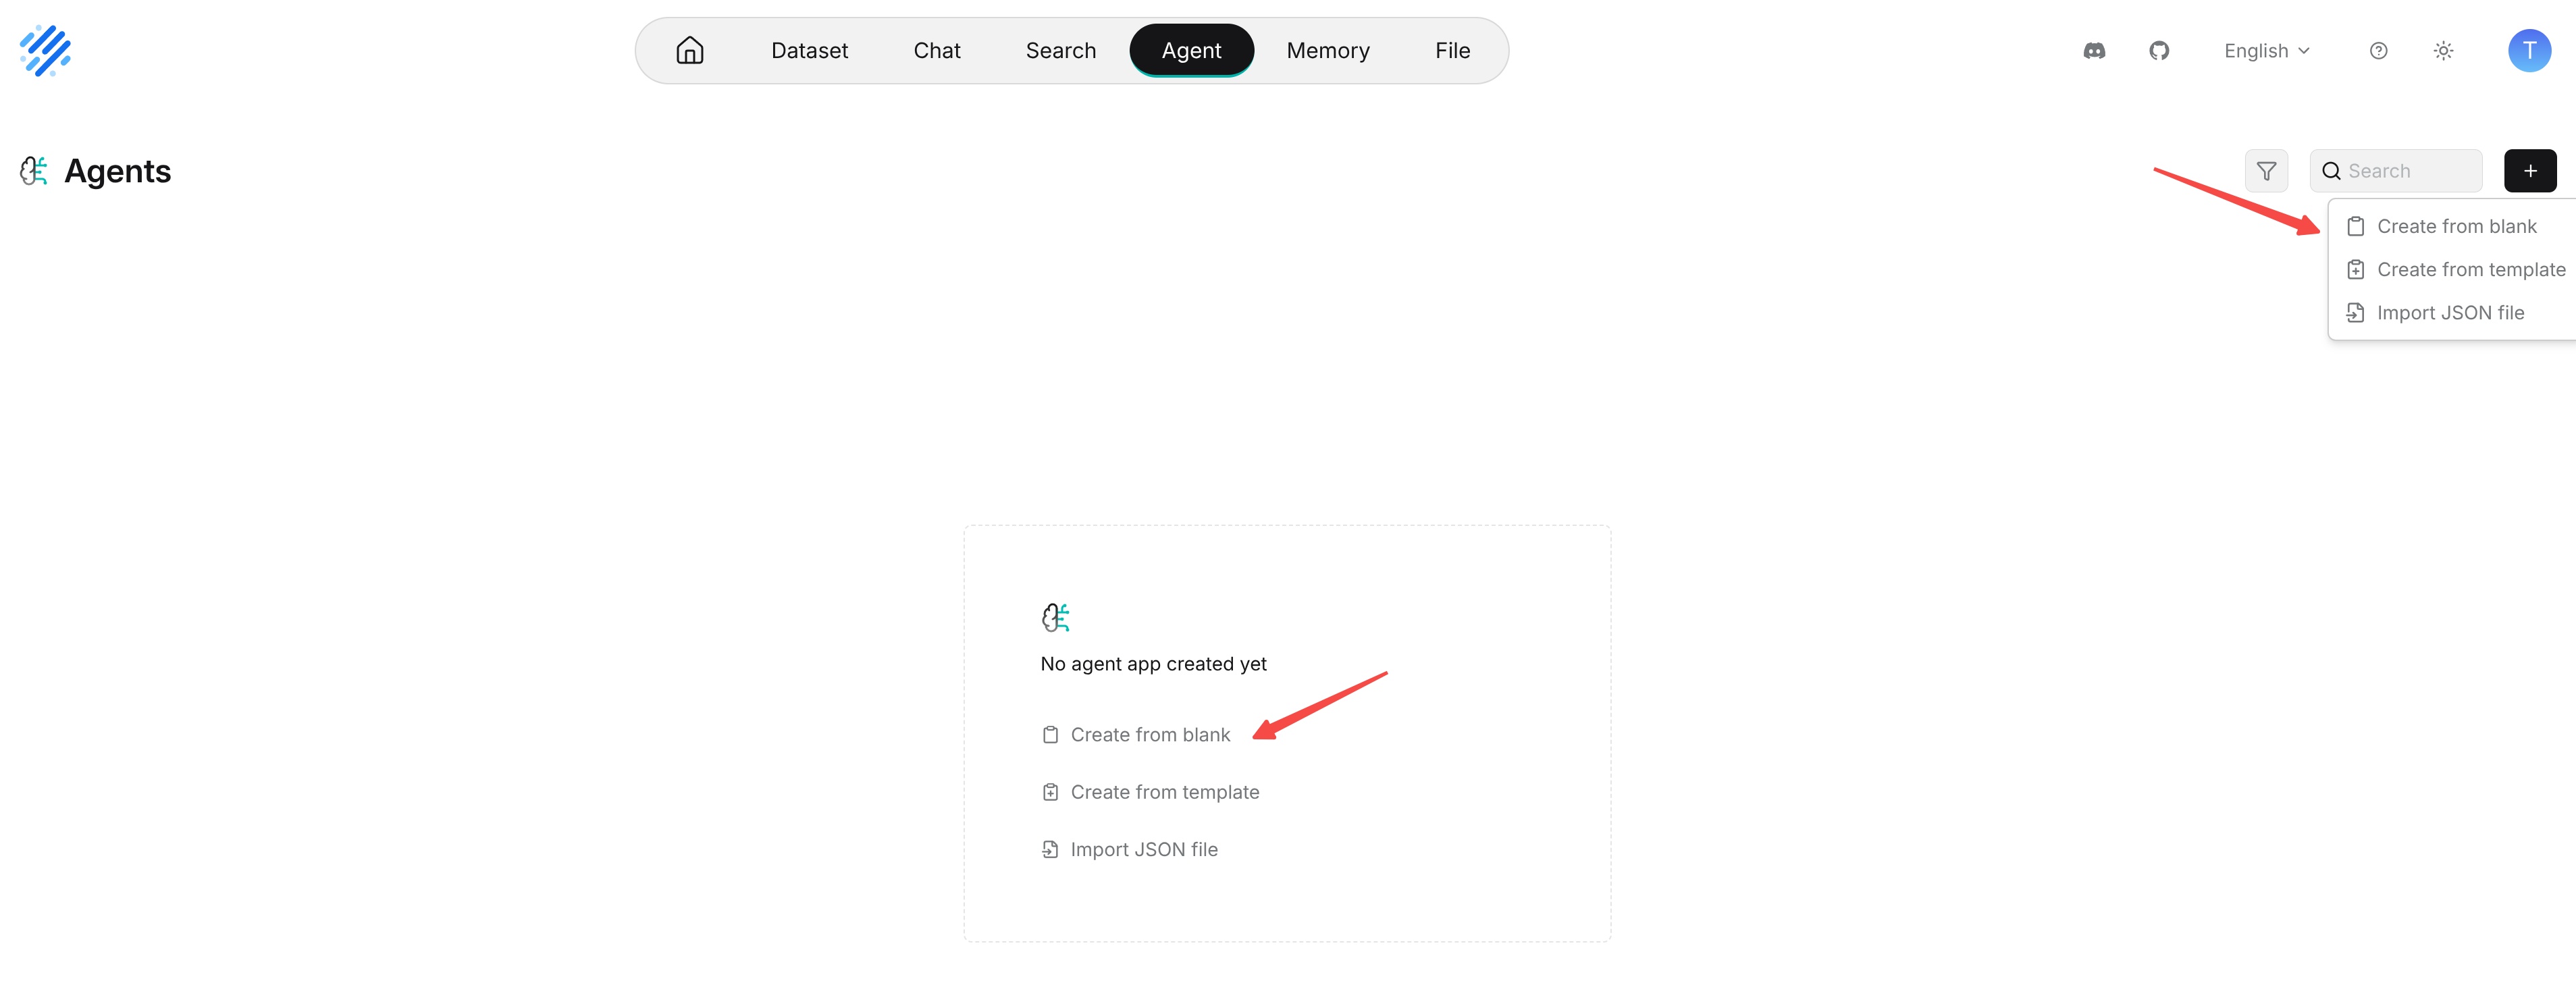
|
||||
|
||||
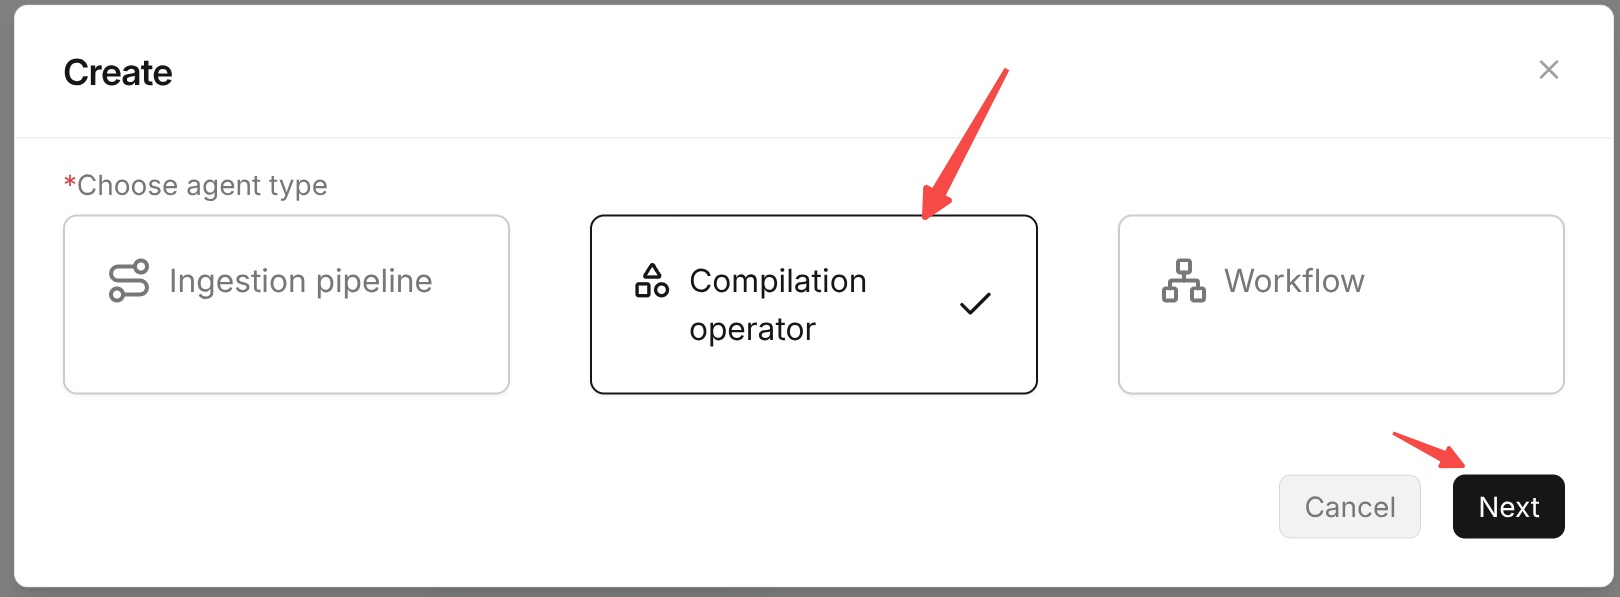
|
||||
|
||||
Note: This section helps users quickly understand the overall workflow of knowledge compilation and only shows the operation interface for "creating a knowledge compilation template". Ingestion Pipeline configuration, document application, knowledge artifact viewing, and other operations are described in detail in the corresponding later chapters with interface screenshots. For specific operations, refer to the relevant chapters.
|
||||
1. **Create a knowledge compilation template**: Open **Agent** and select **Compilation operator**. Choose **Create from blank** to open **Add template**. Enter **Name**, optionally enter **Description**, and select **Template**: Graph, Mindmap, PageIndex, Timeline, Tree, or Wiki. Complete **Global rules** and the settings displayed for the selected type, then click **Save**. See [Basic Information Configuration](./basic_information_configuration.md).
|
||||
2. **Configure the ingestion pipeline**: Create or open a pipeline under **Agent > Ingestion pipeline**. Add **Compiler**, select the saved template group under **Operator**, and choose the model used for compilation. Connect the processing steps to **Indexer**.
|
||||
3. **Publish the pipeline**: Click **Save draft**, resolve any reported configuration issues, then click **Publish** and confirm.
|
||||
4. **Apply the pipeline**: Open the target Dataset's **Configuration**, open **Parsing mode**, expand the custom pipeline, select its published version within that dropdown, and click **Save**.
|
||||
5. **Execute and check compilation**: Upload and parse a representative document. Document parsing and background Dataset-level artifact processing complete separately; Wiki generation and merging may finish later. Check the compilation status and **Logs > Dataset** for pending tasks or errors, and wait for background processing to complete before assessing Dataset-level artifacts. A missing artifact immediately after parsing does not by itself indicate a pipeline failure. Inspect the completed results before processing more documents. See [Apply a Knowledge Compilation Template](./apply_knowledge_compilation_template.md).
|
||||
|
||||
Typical flow: Parser -> Chunker -> Compiler -> Indexer.
|
||||
|
||||
|
||||
@@ -92,9 +92,14 @@ To add a custom model:
|
||||
|
||||
### Verify Models
|
||||
|
||||
After adding models, verify them individually, or click **Verify all models** to verify every model currently shown by the active search and type filters. Verification checks each model together with the current instance credentials and endpoint. If verification fails, check the authentication information, Base URL, network connection, account quota, model name, and model availability.
|
||||
Verify the models you plan to use with the instance's current credentials and endpoint.
|
||||
|
||||
|
||||
1. Open **User settings > Model providers**, select a provider, and open the instance you want to check.
|
||||
2. Complete the required connection fields, such as **API Key** and **Base URL**, and make sure the required models are in the instance's model list.
|
||||
3. To check one model, click the circular-arrow verification icon on its row. The button is identified as **Verify** followed by the model name.
|
||||
4. To check multiple models, use the model search and type tabs to narrow the list, then click **Verify all models**. This checks the models displayed by the active filters. Clear the search and select **All models** if you want to check the full list.
|
||||
5. Wait for the row indicators: a spinner means verification is in progress, a green check means success, and a warning symbol means failure. For a failed model, check the reported error and correct the credentials, endpoint, model name, service availability, or account quota, then verify it again.
|
||||
6. Click **Save** to save the instance configuration. Verification does not replace saving.
|
||||
|
||||
## Set Default Models
|
||||
|
||||
@@ -109,6 +114,16 @@ If you have configured a rerank model, it is also recommended to set a default r
|
||||
|
||||
|
||||
|
||||
### Decision Model
|
||||
|
||||
**Decision model** selects the default model used to judge whether retrieved passages are relevant enough to pass to the LLM. It is separate from the LLM that generates the answer and from the rerank model that scores and orders candidates. Leave it unset if you do not need this filtering.
|
||||
|
||||
1. Add and verify a model that supports the **Decision** type under **User settings > Model providers**.
|
||||
2. Open **Set default models** and select the model in **Decision model**.
|
||||
3. Check that the selected model and provider instance are displayed in the field.
|
||||
|
||||
For a particular Chat, you can select its decision model under **Chat setting > Advanced settings > Agentic > Decision model** and save the Chat settings. See [Chat Configuration](../chat/chat_configuration.md#agentic-settings).
|
||||
|
||||
## Model Types and Usage
|
||||
|
||||
| Model type | Full name | Main function | Input | Output | Typical scenarios |
|
||||
@@ -119,6 +134,7 @@ If you have configured a rerank model, it is also recommended to set a default r
|
||||
| VLM | Vision-Language Model | Understands images and the text, objects, and scene information in them | Images, text, or images with text | Text | Image Q&A, chart understanding, and visual content analysis |
|
||||
| ASR | Automatic Speech Recognition model | Converts speech into text | Audio | Text | Speech transcription, meeting records, and real-time captions |
|
||||
| TTS | Text-to-Speech model | Converts text into speech | Text | Audio | Voice playback, audio content, and voice interaction |
|
||||
| Decision | Decision model | Judges the relevance of retrieved passages before they are passed to the LLM | Query and retrieved content | Relevance decision | Filtering retrieval evidence |
|
||||
| OCR | Optical Character Recognition model | Recognizes text in images or scanned documents | Images or scanned documents | Recognized text | Scanned document recognition and receipt recognition |
|
||||
|
||||
The following model types serve different parts of retrieval, generation, and multimodal workflows:
|
||||
|
||||
@@ -11,12 +11,12 @@ sidebar_custom_props:
|
||||
|
||||
Search provides retrieval capabilities for knowledge bases, helping users quickly find relevant content in parsed knowledge bases. Users can enter natural-language questions and narrow the search scope by configuring document filters, the number of results, and other options.
|
||||
|
||||
Search also supports features such as AI Summary, Related Search, and Query Mind Map. These features summarize search results, generate related questions, and present the topic structure of the current query as a mind map, helping users further understand and explore knowledge content.
|
||||
Search also supports features such as AI Summary, Related Search, and Query Mindmap. These features summarize search results, generate related questions, and present the topic structure of the current query as a mind map, helping users further understand and explore knowledge content.
|
||||
|
||||
The following sections describe how to create, configure, and use Search.
|
||||
|
||||
1. Go to the **Search** page from the top navigation bar.
|
||||
2. Click **Create Search**.
|
||||
3. Enter a name for the Search and confirm.
|
||||
4. Open the newly created Search and go to **Search Settings**.
|
||||
5. Under **Datasets**, select at least one knowledge base and click **OK** to save.
|
||||
4. Open the newly created Search. If the **Search settings** panel is closed, click the settings button to open it.
|
||||
5. Under **Datasets**, select at least one knowledge base and click **Save** to save.
|
||||
@@ -25,7 +25,7 @@ Use **Metadata** to restrict retrieval by document metadata. Available fields de
|
||||
|
||||
## Similarity threshold
|
||||
|
||||
Sets the minimum similarity threshold for search results. It is used to filter out chunks that have low relevance to the query.
|
||||
Sets the minimum similarity threshold for search results. The UI displays this on a percentage scale: `20` means 20%. It is used to filter out chunks that have low relevance to the query.
|
||||
|
||||
Only content with a similarity score that meets or exceeds the threshold is included in the search results.
|
||||
|
||||
@@ -66,6 +66,28 @@ Reranking can generally improve the quality of the final result ordering, but it
|
||||
|
||||
Enable it if search accuracy is the priority. Leave it disabled if response speed is more important or no rerank model has been configured.
|
||||
|
||||
## Model
|
||||
|
||||
Use **Model** below **Rerank model** to select the LLM used by Search's generated content, such as **AI summary**, **Enable related search**, and **Show query mindmap**. This is separate from the embedding model used to retrieve content and the rerank model used to order results.
|
||||
|
||||
1. Add and verify an available LLM in **User settings > Model providers**.
|
||||
2. Open the Search's **Search settings** panel and select that model under **Model**.
|
||||
3. Enable the generation features you need and click **Save**.
|
||||
4. Submit a representative query and review the generated content along with its source results.
|
||||
|
||||
## Model Settings
|
||||
|
||||
Expand **Model settings** below **Model** to adjust the generation parameters supported by the selected model.
|
||||
|
||||
| Setting | Purpose |
|
||||
| --- | --- |
|
||||
| Temperature | Adjust the variation in generated text. Start with a lower value when consistent summaries are important. |
|
||||
| Top P | Limit token sampling to a probability mass. Keep the default unless the generated content requires adjustment. |
|
||||
| Presence penalty | Adjust the tendency to introduce topics not yet mentioned in the generated text. |
|
||||
| Frequency penalty | Adjust the tendency to repeat words or phrases. |
|
||||
|
||||
Change one parameter at a time, click **Save**, and compare the results using the same query. These settings control generated text; use the retrieval parameters above to change which source chunks are retrieved.
|
||||
|
||||
## AI summary
|
||||
|
||||
Controls whether an AI-generated summary is produced for the search results.
|
||||
|
||||
@@ -225,7 +225,7 @@ In RAGFlow, keyword analysis is used to enrich query representation, helping the
|
||||
|
||||
A knowledge artifact is a structured representation of knowledge generated from documents or knowledge base content through Knowledge Compilation.
|
||||
|
||||
Depending on the Knowledge Compilation template used, different forms of knowledge artifacts can be generated, including Wiki, Graph, Tree, PageIndex, Mind Map, Timeline, and Skills.
|
||||
Depending on the Knowledge Compilation template used, different forms of knowledge artifacts can be generated, including Wiki, Graph, Tree, PageIndex, Mindmap, Timeline, and Skills.
|
||||
|
||||
These artifacts reorganize existing knowledge into different structures and can be used for knowledge browsing, understanding, and subsequent applications.
|
||||
|
||||
@@ -233,13 +233,13 @@ These artifacts reorganize existing knowledge into different structures and can
|
||||
|
||||
Knowledge Compilation further refines, organizes, and structures existing document or knowledge base content.
|
||||
|
||||
Knowledge Compilation can be performed on an individual document or an entire knowledge base. By selecting different compilation templates, raw content can be transformed into knowledge artifacts such as Wiki, Graph, Tree, PageIndex, Mind Map, Timeline, or Skills.
|
||||
Knowledge Compilation can be performed on an individual document or an entire knowledge base. By selecting different compilation templates, raw content can be transformed into knowledge artifacts such as Wiki, Graph, Tree, PageIndex, Mindmap, Timeline, or Skills.
|
||||
|
||||
**Knowledge Compilation Template**
|
||||
|
||||
A Knowledge Compilation Template is a predefined template that determines how knowledge is compiled and how the resulting artifact is structured.
|
||||
|
||||
In RAGFlow, different templates can compile source documents or knowledge base content into specific forms of knowledge artifacts, such as Wiki, Graph, Tree, Page Index, Mind Map, Timeline, and Skills, to support different knowledge organization and usage scenarios.
|
||||
In RAGFlow, different templates can compile source documents or knowledge base content into specific forms of knowledge artifacts, such as Wiki, Graph, Tree, Page Index, Mindmap, Timeline, and Skills, to support different knowledge organization and usage scenarios.
|
||||
|
||||
### **L**
|
||||
|
||||
@@ -275,9 +275,9 @@ Metadata filtering restricts the retrieval scope based on document or chunk meta
|
||||
|
||||
For example, retrieval can be limited to content that matches a specified category, source, or other business attribute, making retrieval results more targeted.
|
||||
|
||||
**Mind Map**
|
||||
**Mindmap**
|
||||
|
||||
Mind Map is a knowledge artifact supported by Knowledge Compilation.
|
||||
Mindmap is a knowledge artifact supported by Knowledge Compilation.
|
||||
|
||||
It organizes the main topics and subtopics in the content into a hierarchical mind map, helping users quickly understand the knowledge structure and relationships among different topics.
|
||||
|
||||
|
||||
@@ -134,7 +134,7 @@ Released on Aug 28, 2026.
|
||||
Released on Aug 19, 2026.
|
||||
|
||||
### New features
|
||||
- Brand new document level and dataset level knowledge compilation, supporting Wiki, Graph, Tree, Page Index, Mind Map, Timeline, and To Skills ([#16777](https://github.com/infiniflow/ragflow/pull/16777), [#17546](https://github.com/infiniflow/ragflow/pull/17546), [#16797](https://github.com/infiniflow/ragflow/pull/16797), [#16749](https://github.com/infiniflow/ragflow/pull/16749), [#16899](https://github.com/infiniflow/ragflow/pull/16899), [#17996](https://github.com/infiniflow/ragflow/pull/17996))
|
||||
- Brand new document level and dataset level knowledge compilation, supporting Wiki, Graph, Tree, Page Index, Mindmap, Timeline, and To Skills ([#16777](https://github.com/infiniflow/ragflow/pull/16777), [#17546](https://github.com/infiniflow/ragflow/pull/17546), [#16797](https://github.com/infiniflow/ragflow/pull/16797), [#16749](https://github.com/infiniflow/ragflow/pull/16749), [#16899](https://github.com/infiniflow/ragflow/pull/16899), [#17996](https://github.com/infiniflow/ragflow/pull/17996))
|
||||
- The previous GraphRAG and RAPTOR features have been deprecated and are no longer available in the UI. Their replacements, Graph and Tree, are now integrated into Knowledge Compilation. Previously generated GraphRAG and RAPTOR content remains searchable.
|
||||
- Brand new Agentic RAG with four thinking modes when answering - Low, Medium, High, and Ultra ([#18303](https://github.com/infiniflow/ragflow/pull/18303), [#18138](https://github.com/infiniflow/ragflow/pull/18138), [#17342](https://github.com/infiniflow/ragflow/pull/17342), [#17444](https://github.com/infiniflow/ragflow/pull/17444))
|
||||
|
||||
|
||||
Reference in new issue
Block a user